 AI Briefing
colibri: Ultra-lightweight inference engine running 744B MoE models on consumer hardware
JustVugg/colibri
About the project
By integrating VRAM, RAM, and storage into a single tier, this engine runs MoE models ranging from 744B to 2.8T parameters on consumer hardware. Written in pure C, the engine minimizes dependencies and supports the latest large models, including GLM-5.2, Kimi K3, and DeepSeek V4 Flash, through a single interface.
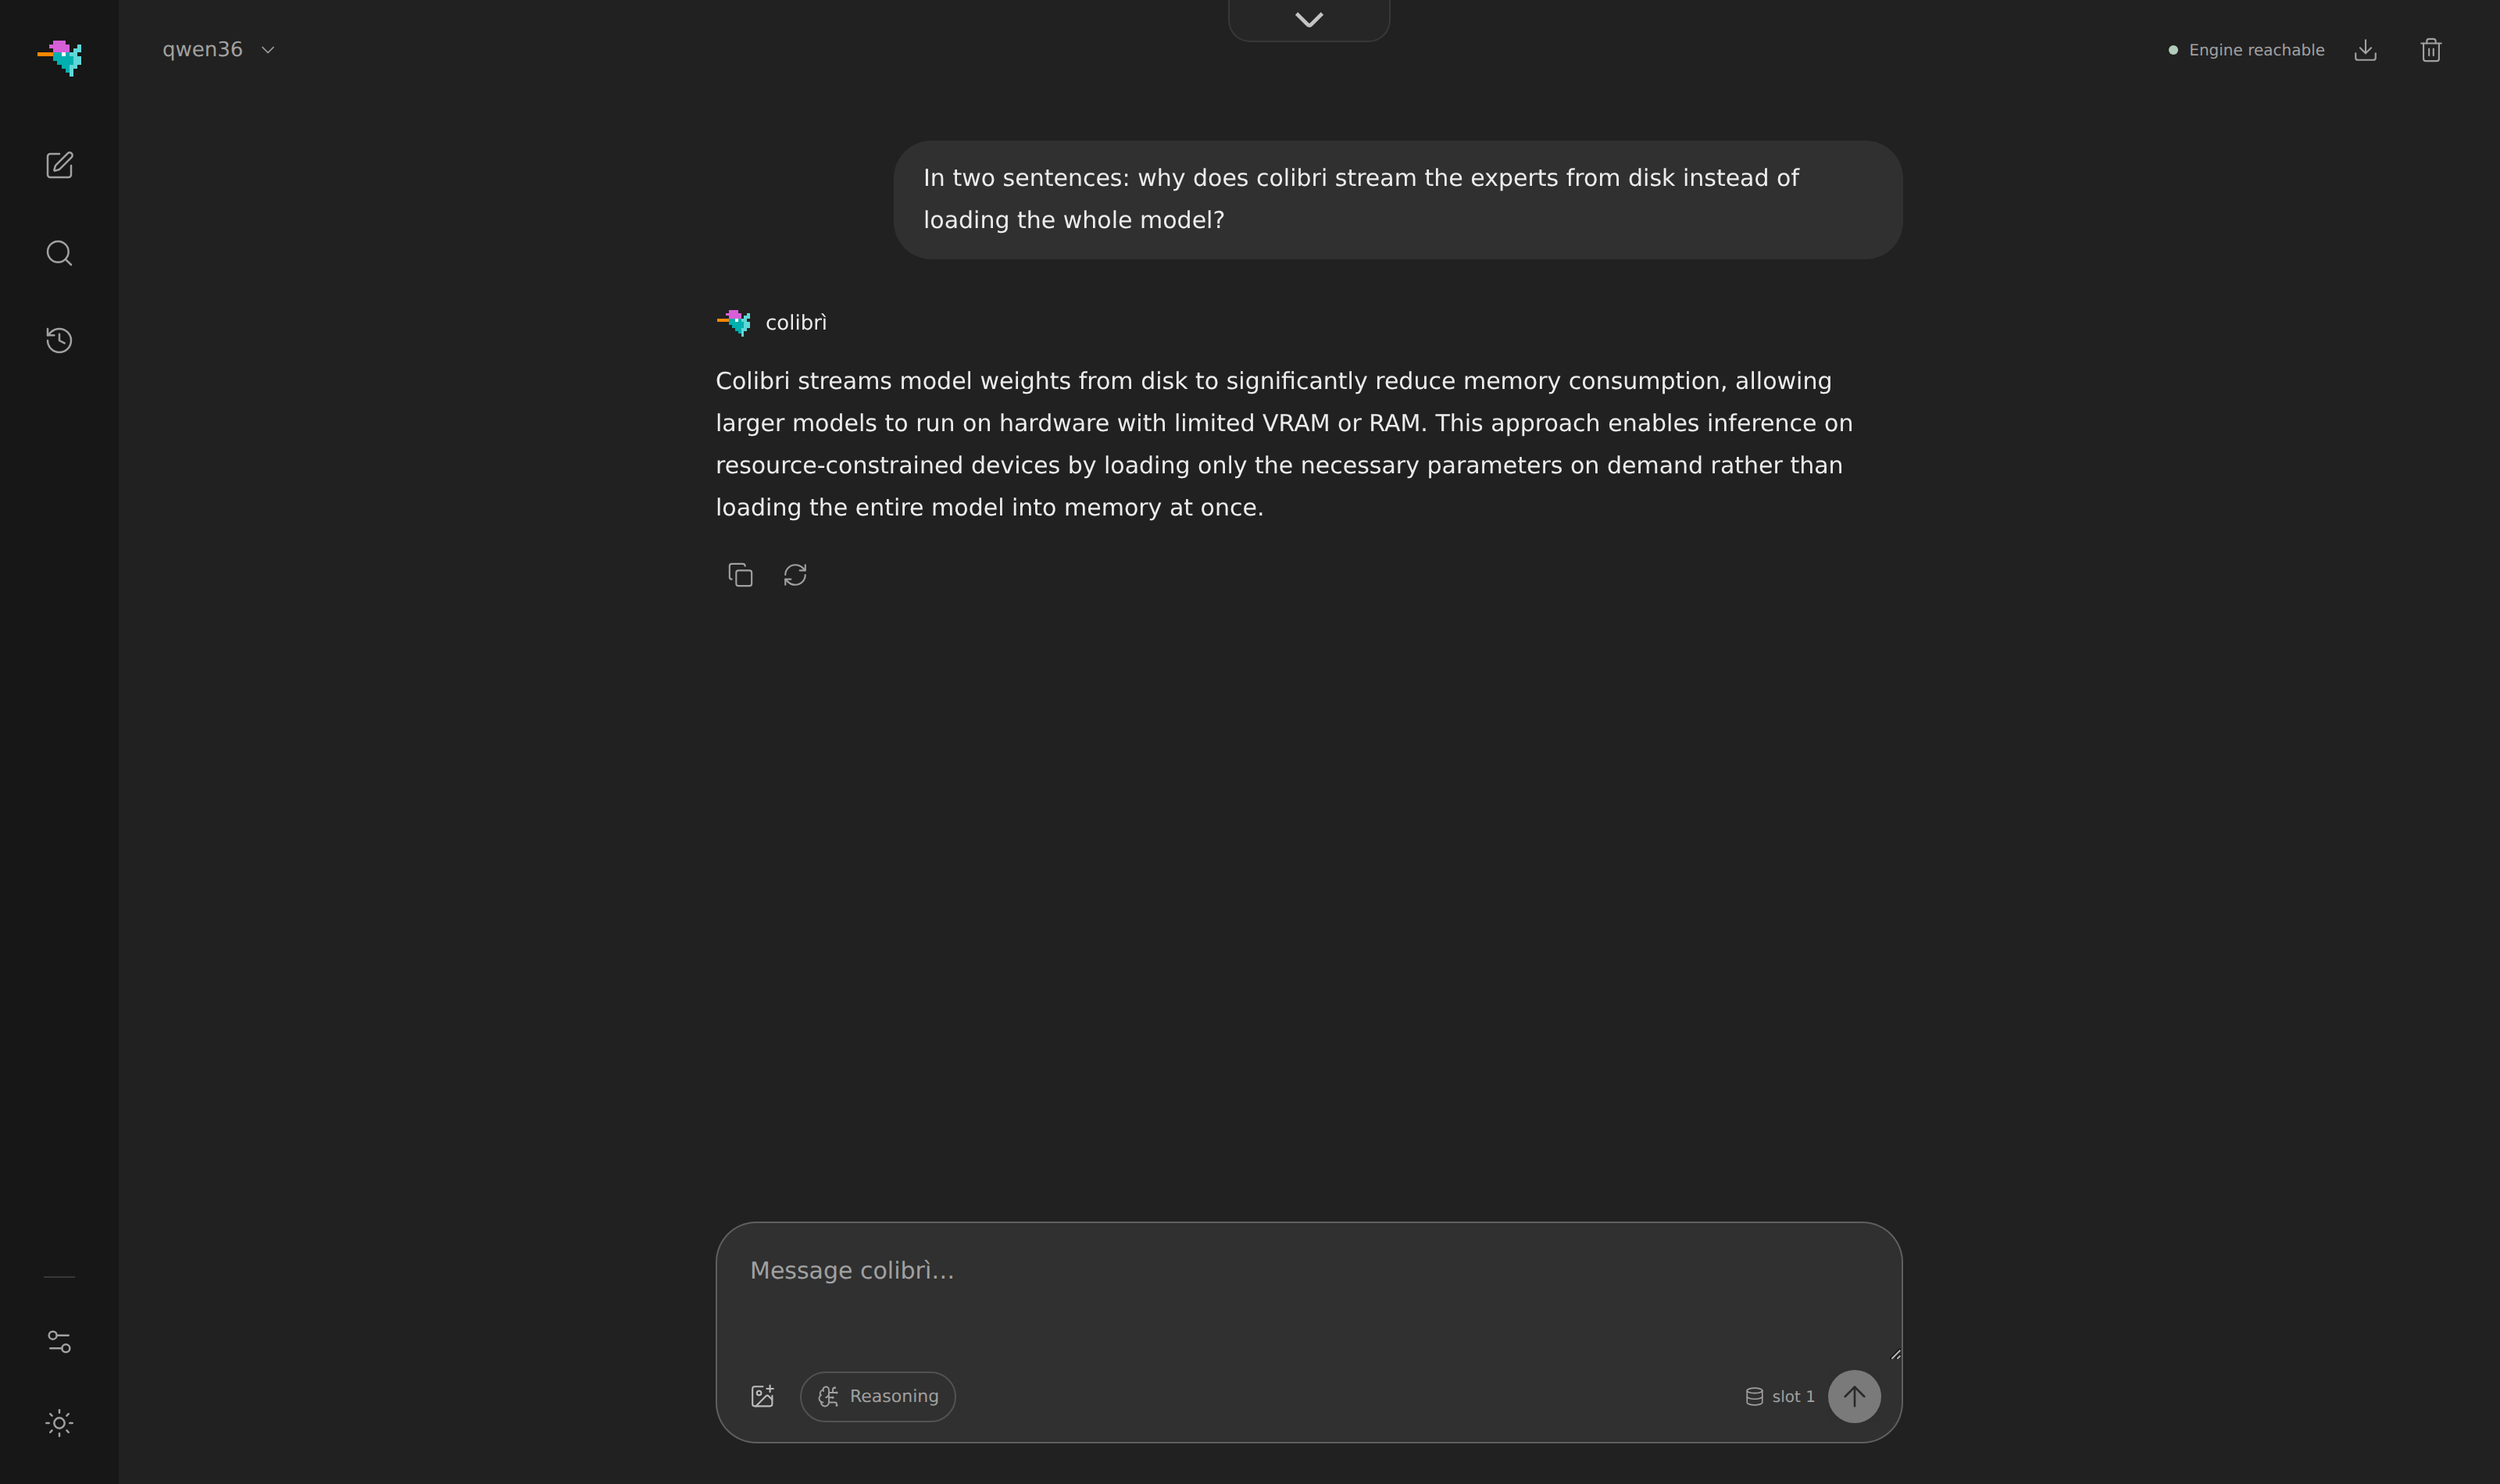

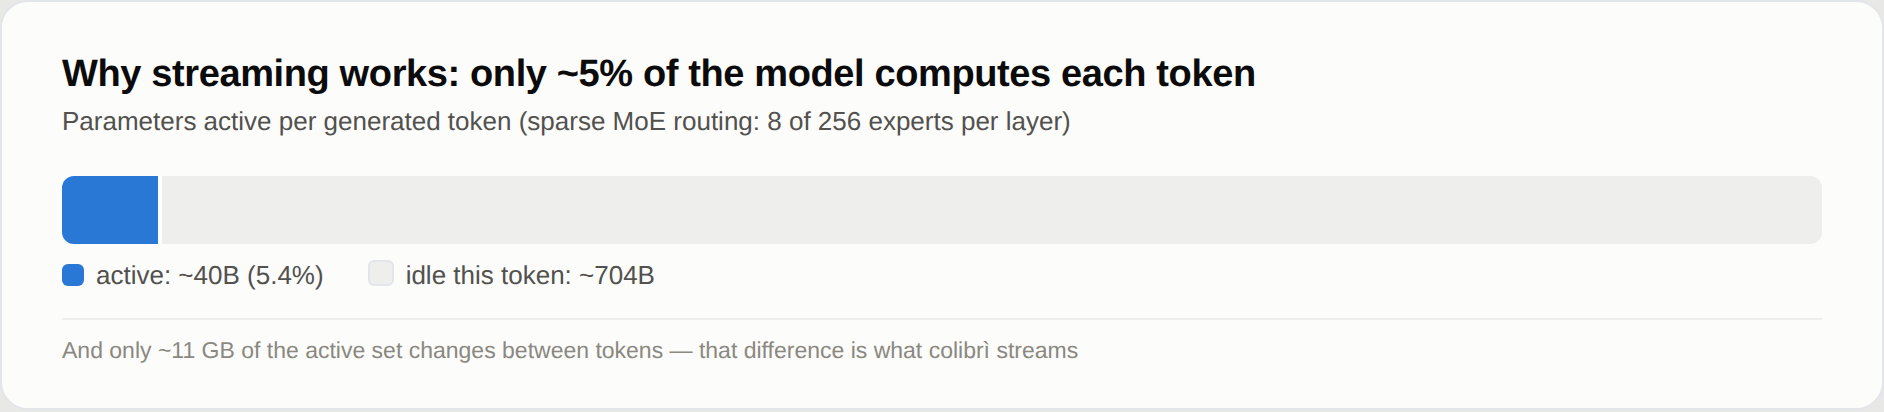
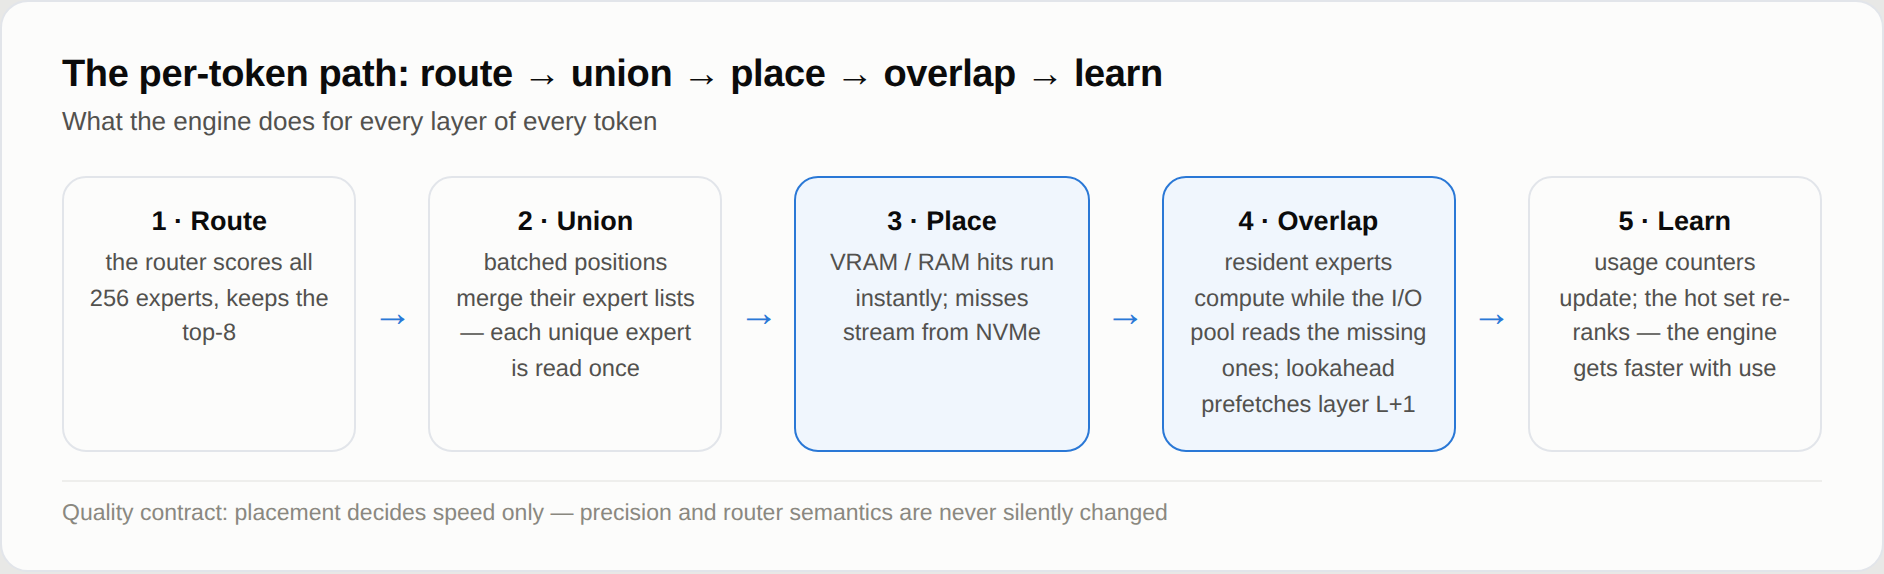
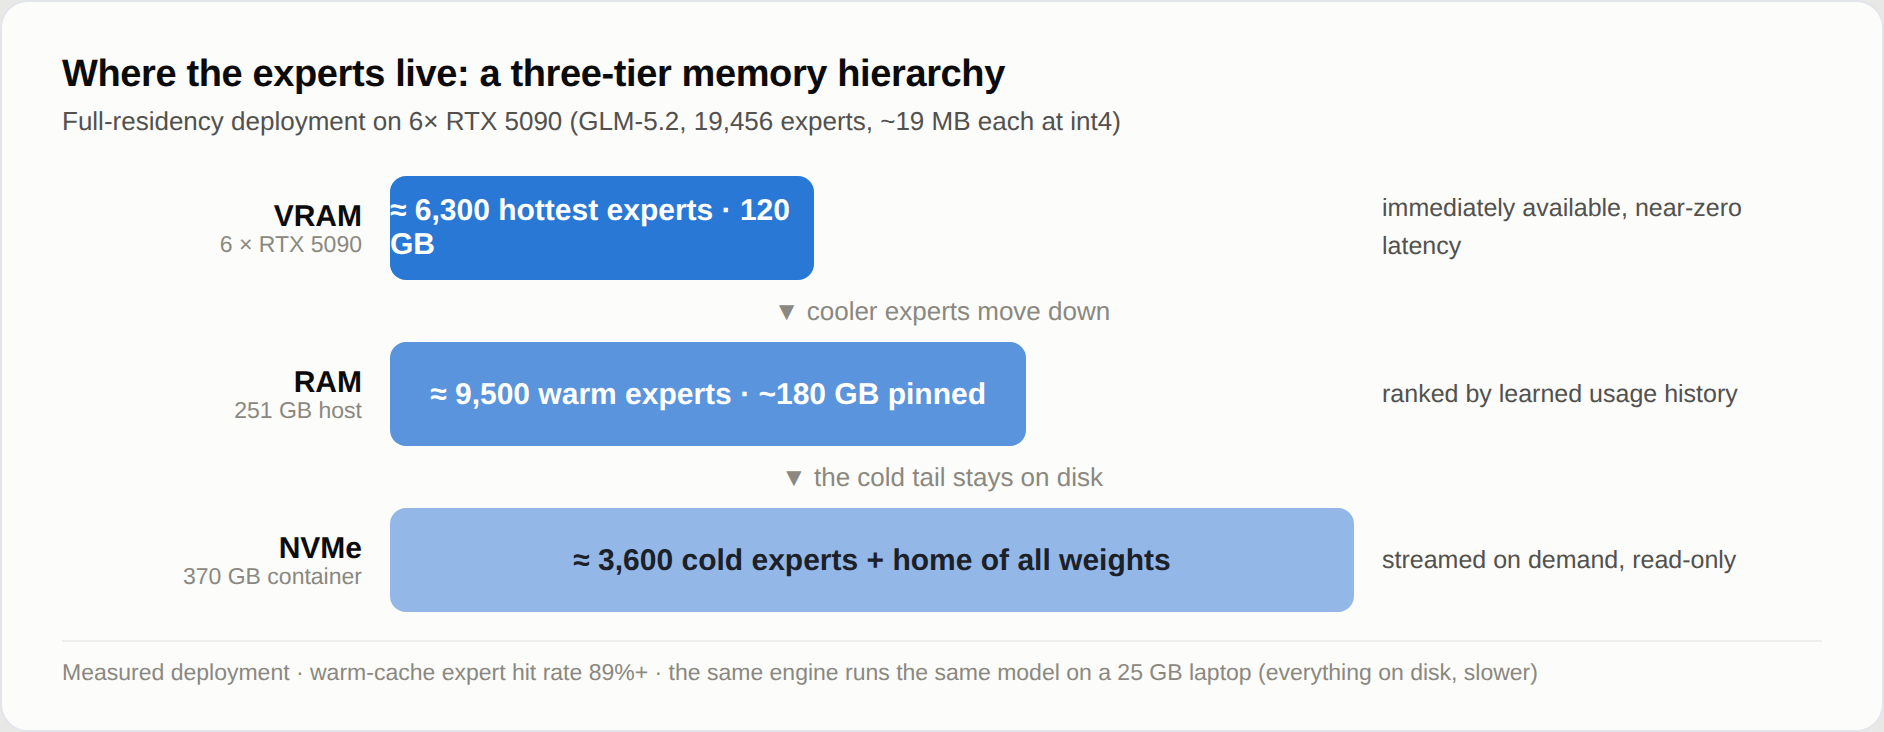
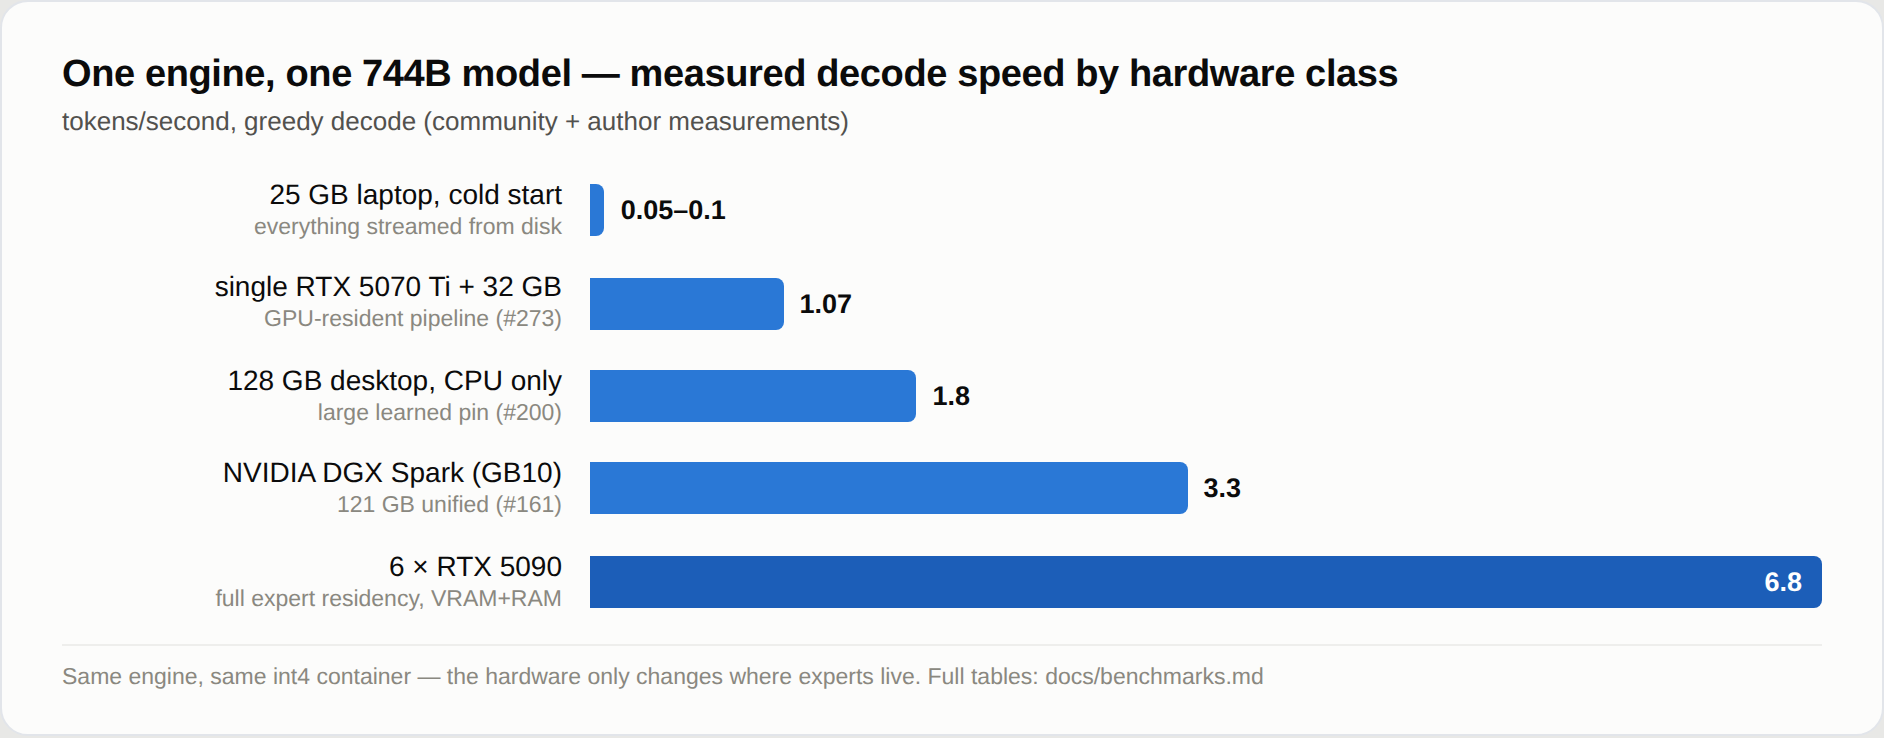
It adopts a strategy that does not keep weights resident in memory, loading them on-demand via JIT based on routing hits. The router pre-computes the next layer for prefetching and leverages CPU, GPU, and NVMe to resolve bandwidth bottlenecks. This ensures model accuracy and inference speed even in environments with limited VRAM.
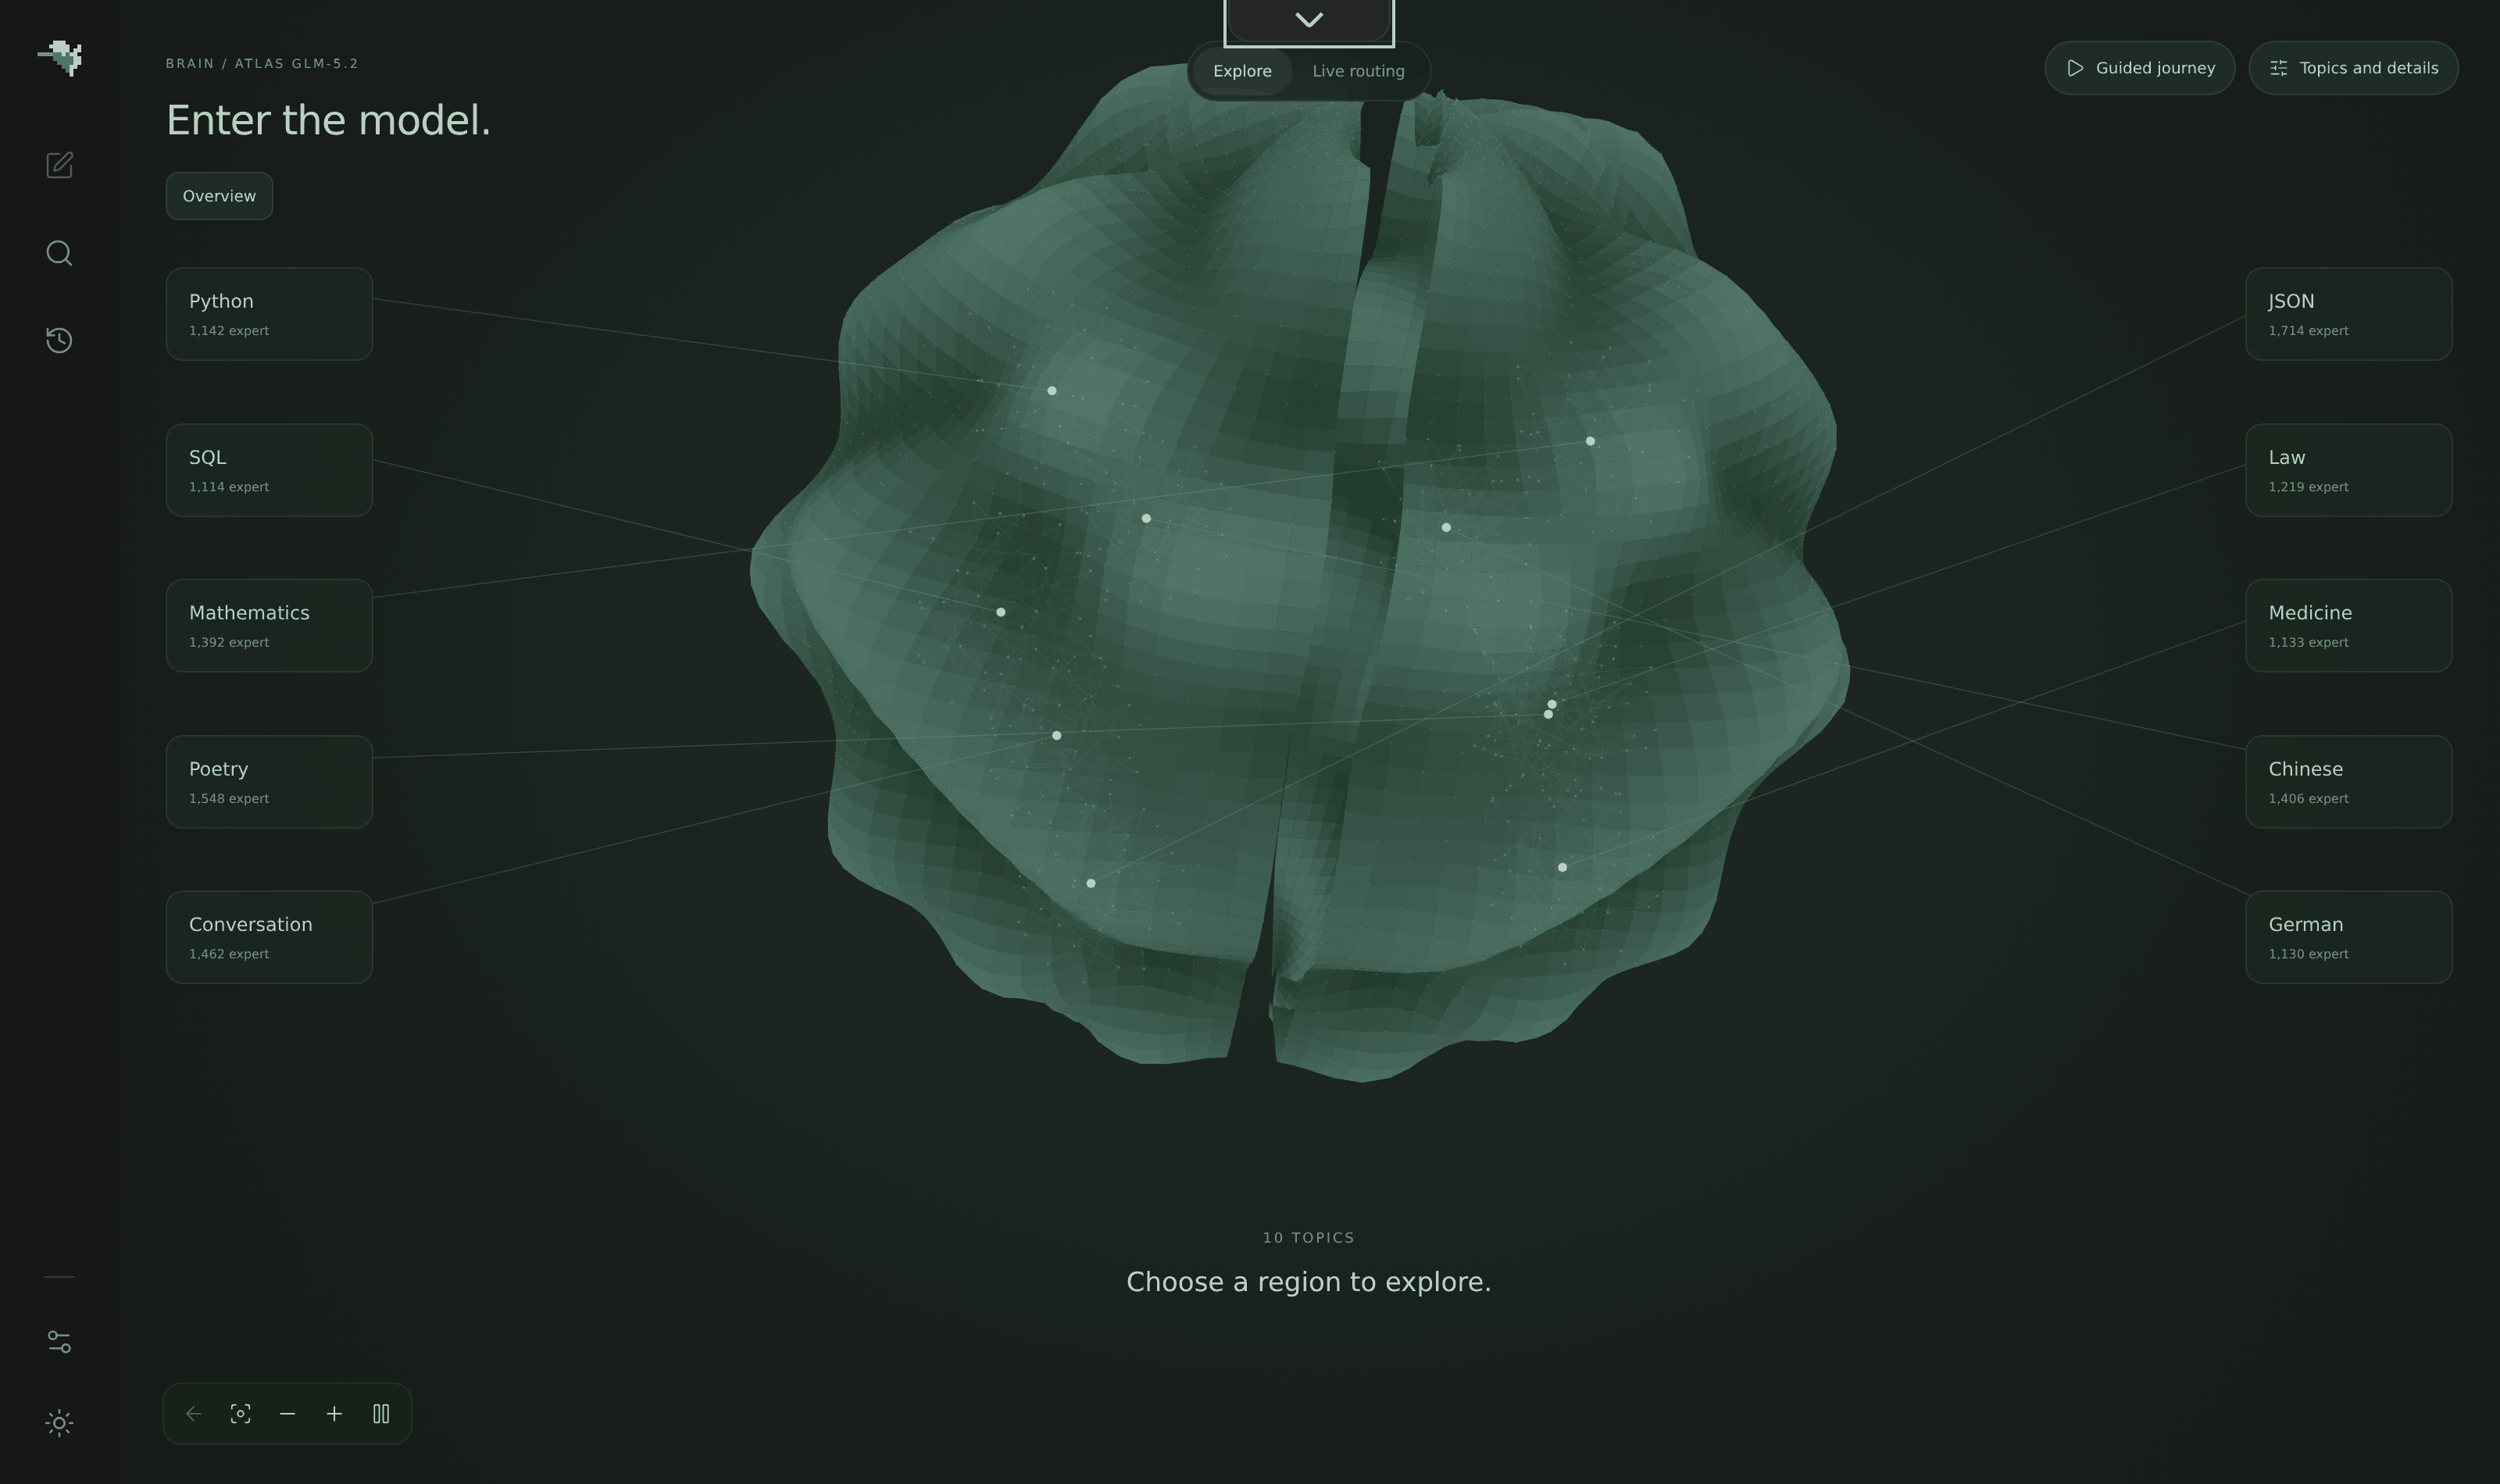
A web dashboard visualizes the real-time routing of 19,456 experts, allowing users to inspect each expert's topic preferences and storage tier. Without requiring hyperscaler-grade equipment, developers can directly measure and optimize the internal behavior of frontier models, making this suitable for those looking to operate or research large LLMs at low cost.
JustVugg/colibri
Run frontier MoE models on hardware you already own — pure C, zero deps, experts streamed from disk. Tiny engine, immense model. 🐦
C
This introduction was generated automatically by AI. Check the original for the author's claims and context. Copyright belongs to the original author.
Our guide explains how the AI works. Report errors, attribution issues, or removal requests via Contact.