 AI Briefing
higgsfield: Trillion-parameter model, distributed training with a single GitHub commit
higgsfield-ai/higgsfield
About the project
It frees you from complex cluster configurations and dependency hell for training LLMs with billions to trillions of parameters. It automates GPU resource allocation, execution, and monitoring, supporting ZeRO-3 DeepSpeed and PyTorch FSDP to enable efficient distributed processing of large-scale models.
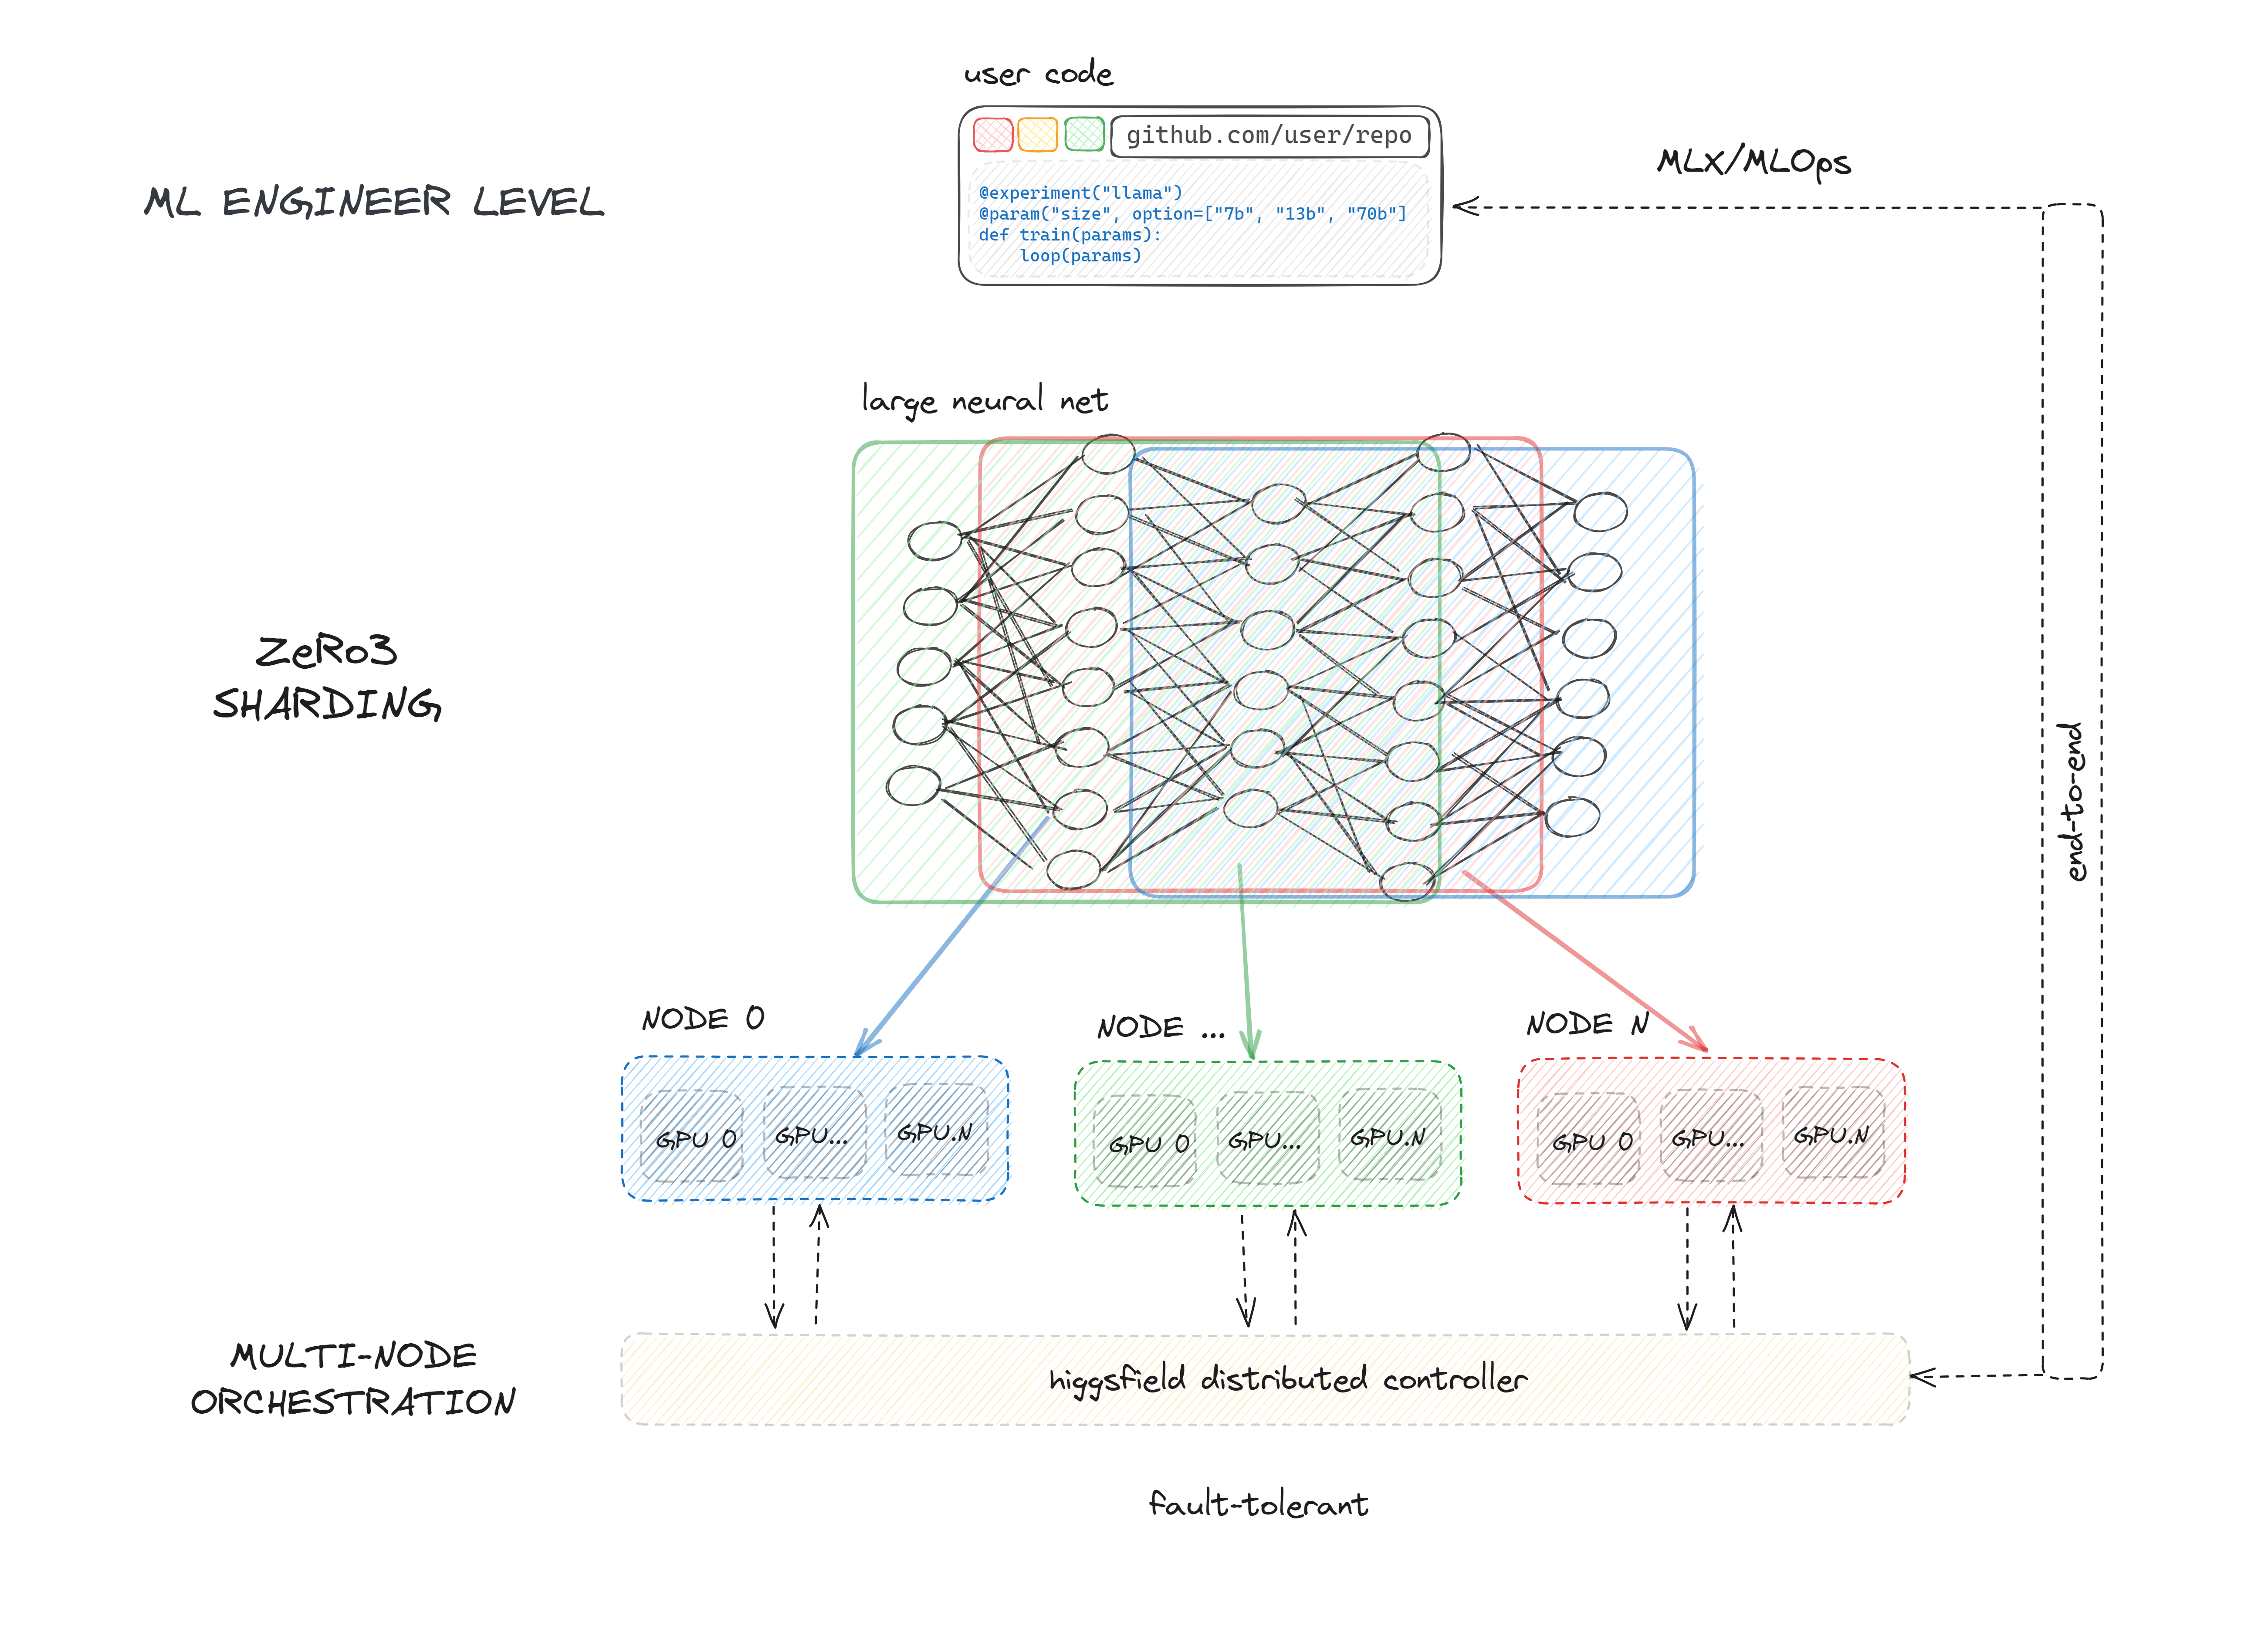
Integrated with GitHub Actions, it deploys and runs experiments on nodes with just a code commit. Instead of YAML hell defining over 600 arguments, it offers a simple interface for configuring experiments and automatically handles version control for checkpoint saving and reproducibility.
Validated in major cloud environments such as Azure, LambdaLabs, and FluidStack, it is ready for immediate use on any Ubuntu-based node with SSH access. Following standard PyTorch workflows ensures high compatibility with existing code, and it is optimized for training large models like LLaMA 70B in distributed environments.
higgsfield-ai/higgsfield
Fault-tolerant, highly scalable GPU orchestration, and a machine learning framework designed for training models with billions to trillions of parameters
Jupyter Notebook
This introduction was generated automatically by AI. Check the original for the author's claims and context. Copyright belongs to the original author.
Our guide explains how the AI works. Report errors, attribution issues, or removal requests via Contact.