 AI Briefing
minimind: An educational repository for assembling a 64M LLM from scratch on a $3 GPU
jingyaogong/minimind
About the project
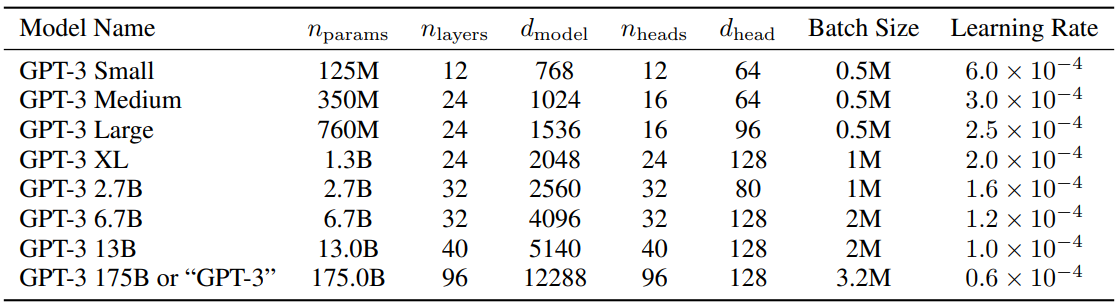
An environment has been established that allows you to directly train an ultra-lightweight 64M LLM in just 2 hours, rather than working with massive models containing tens of billions of parameters. With a single NVIDIA 3090 and approximately $3 in cloud costs, you can complete the entire pipeline from Pretrain to SFT and RLHF. At 1/2700 the size of GPT-3, it allows for effortless experimentation on personal hardware.
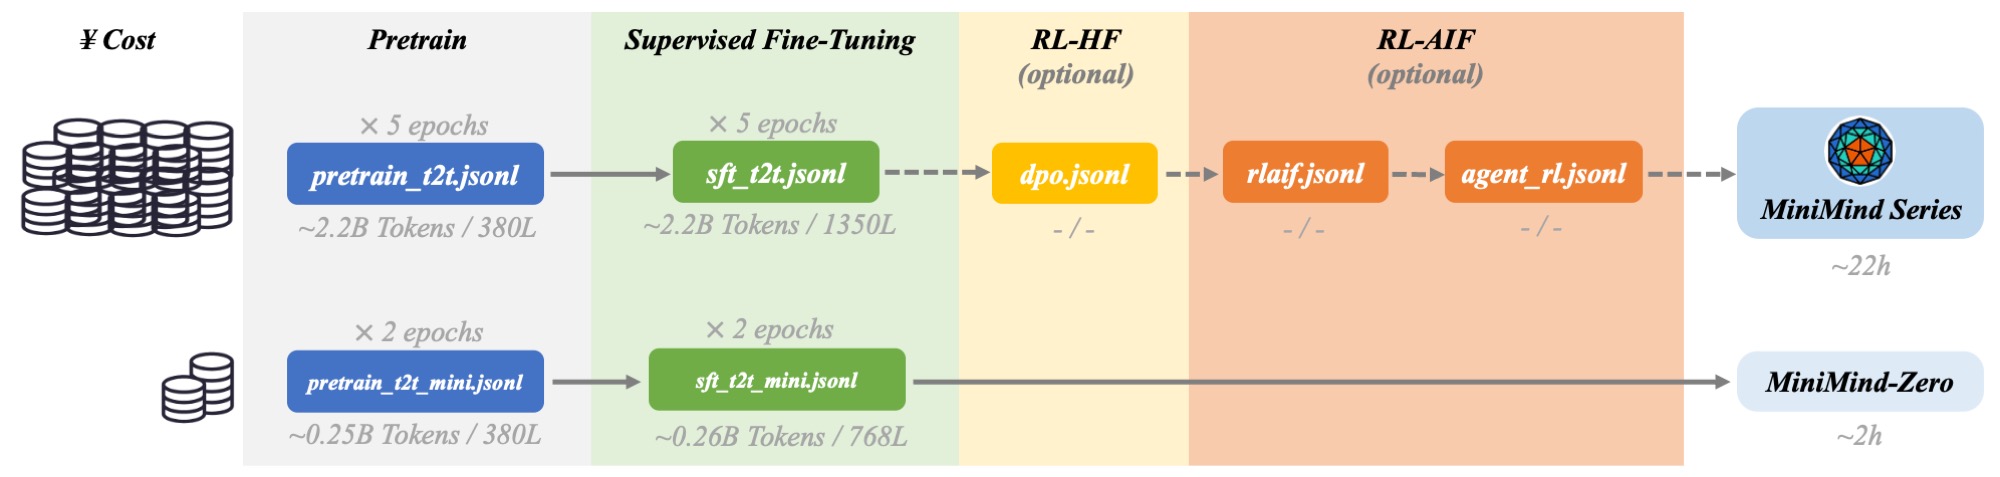
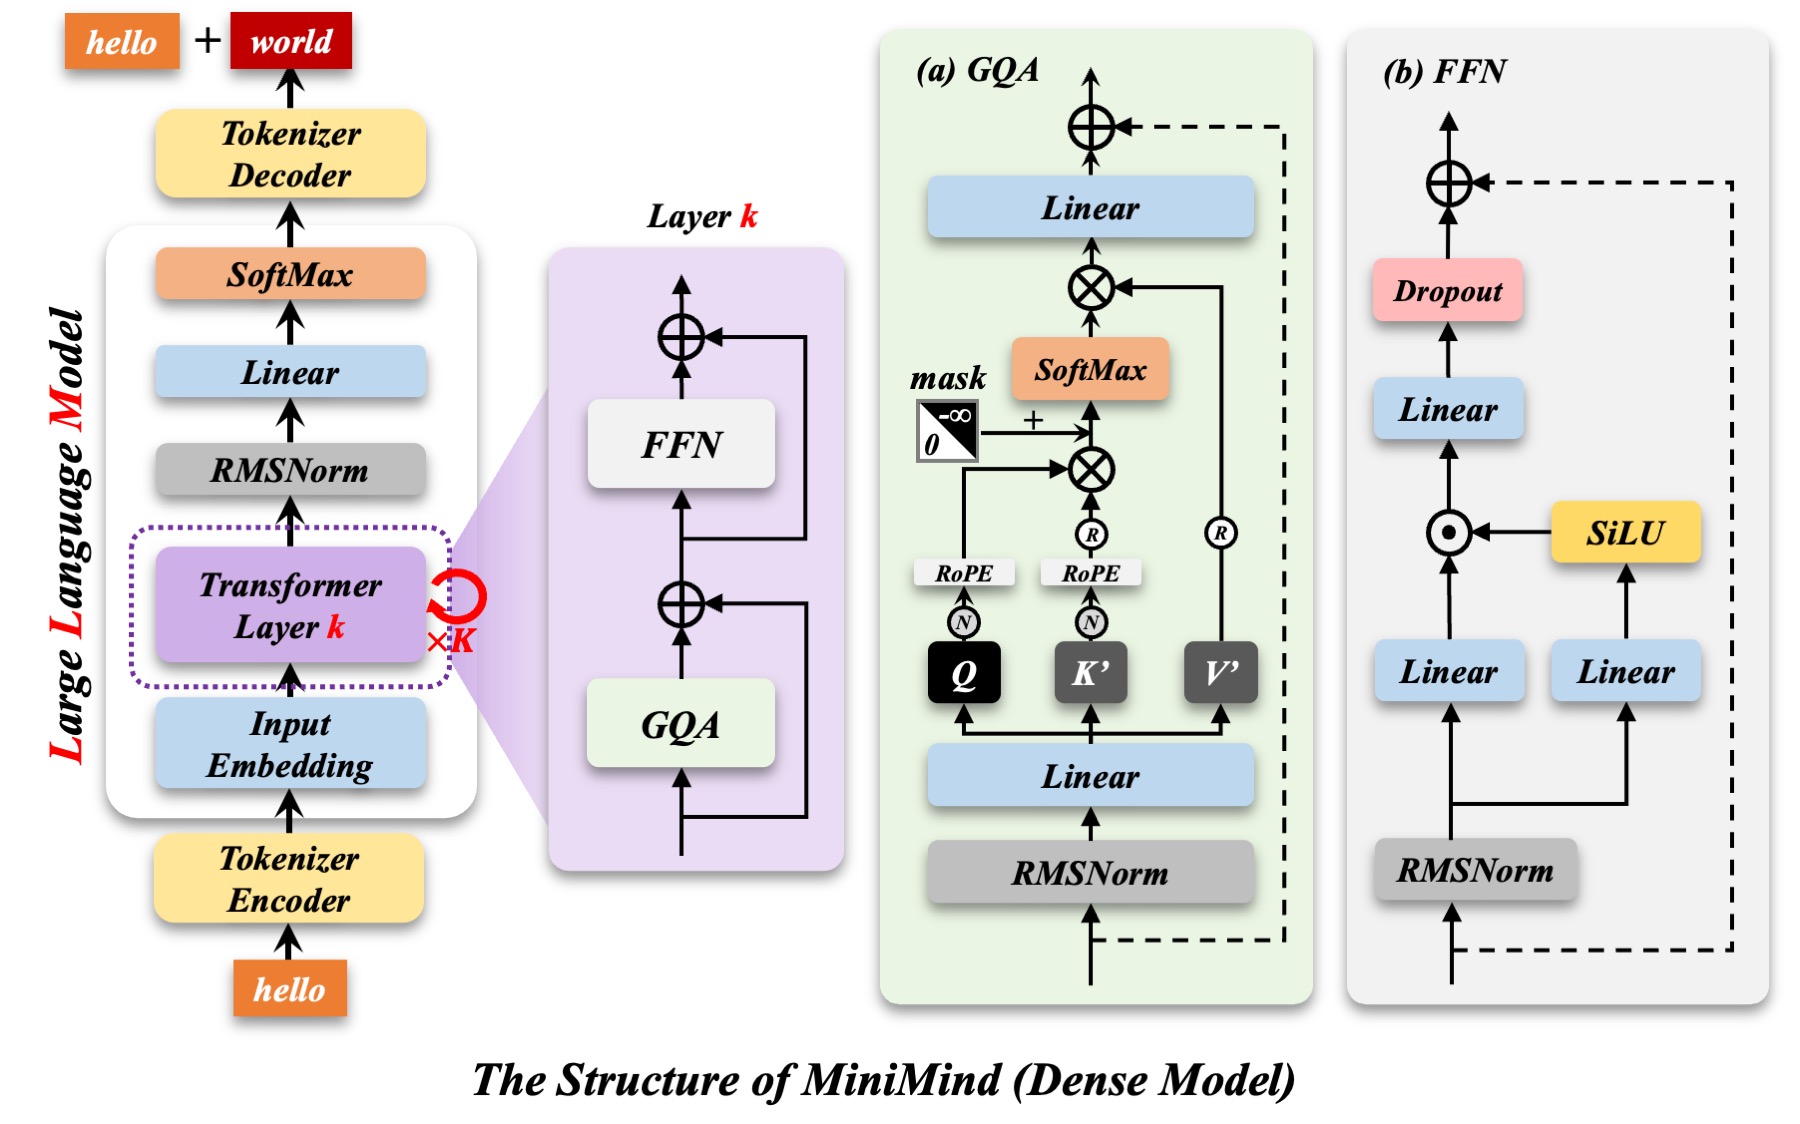
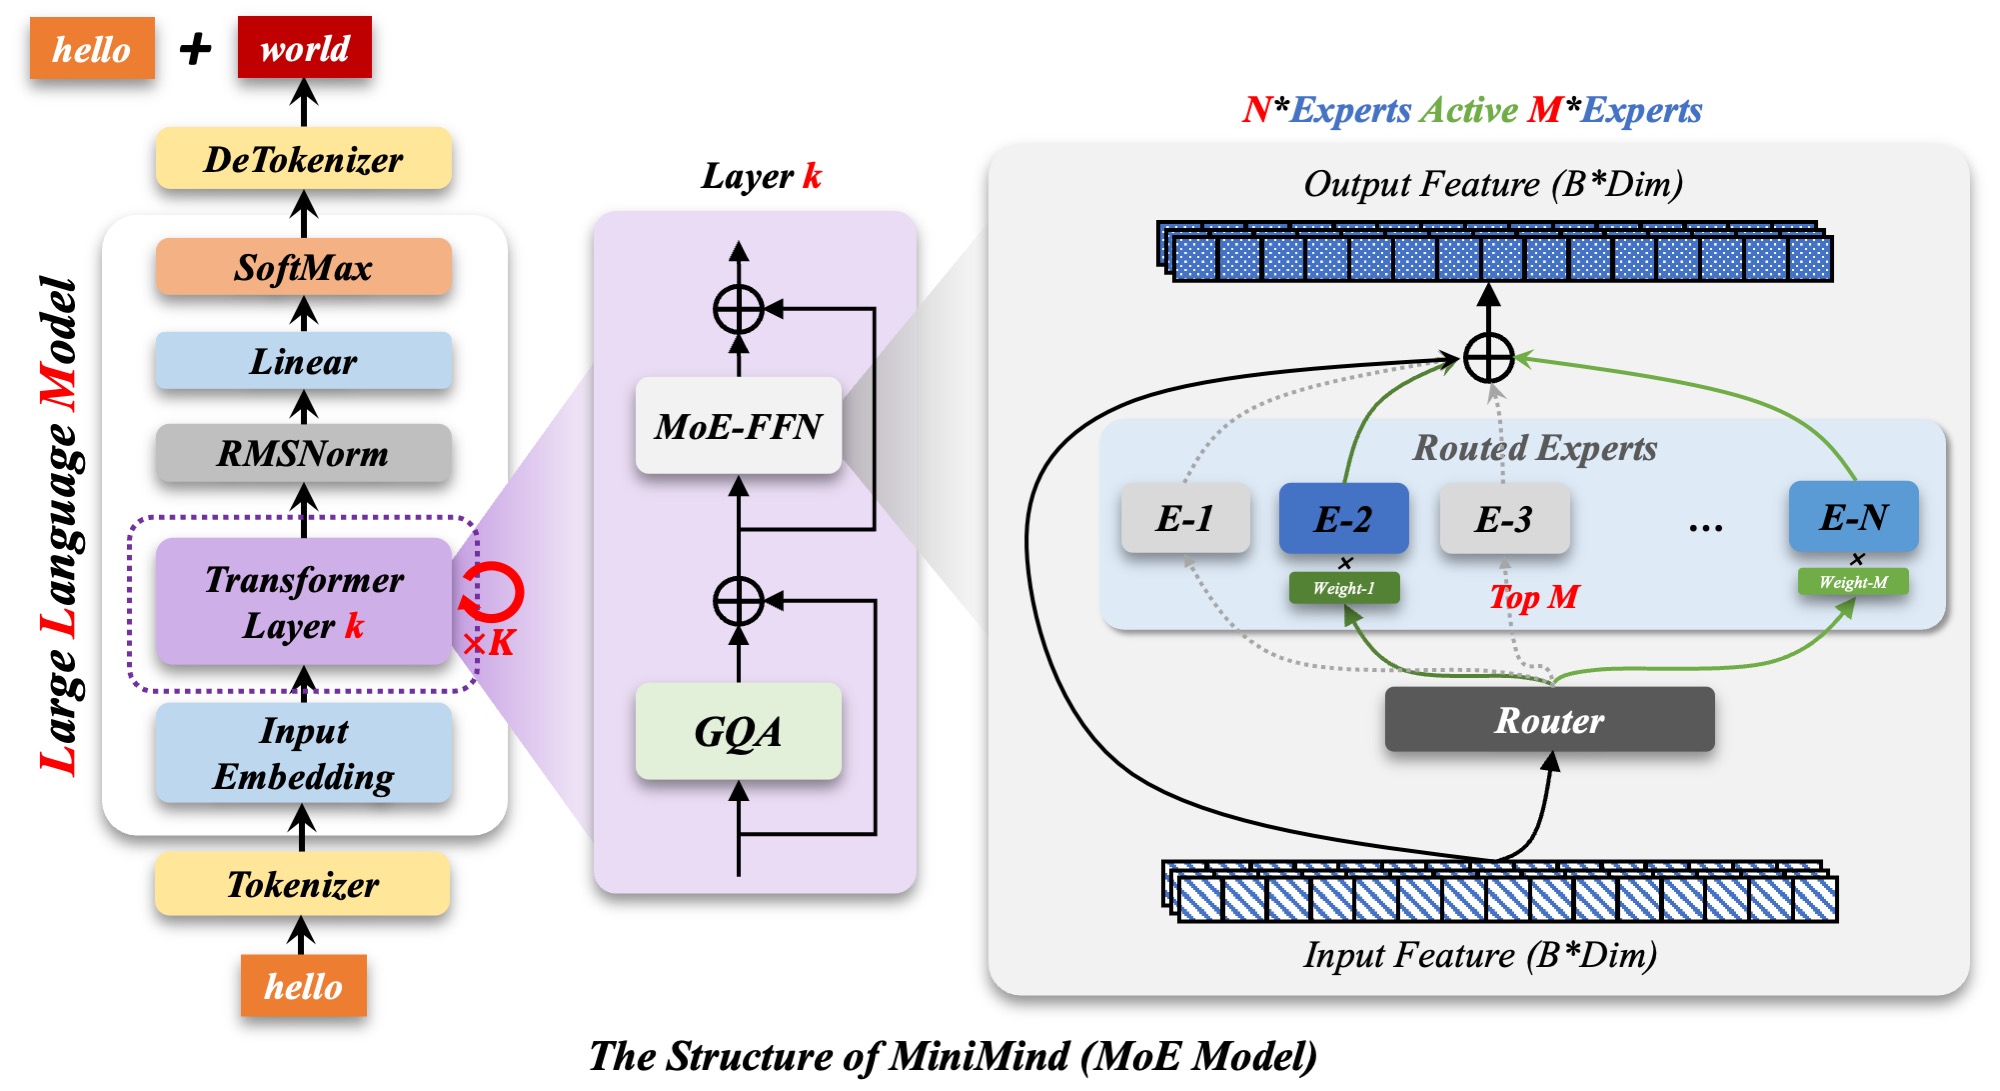
Without relying on high-level libraries like transformers or trl, all algorithms are implemented in raw PyTorch code. You can understand how complex training techniques such as MoE architecture, LoRA, DPO, PPO, and GRPO work by examining every line of code. The structure is optimized for developers seeking to grasp the internal principles hidden behind abstracted interfaces.
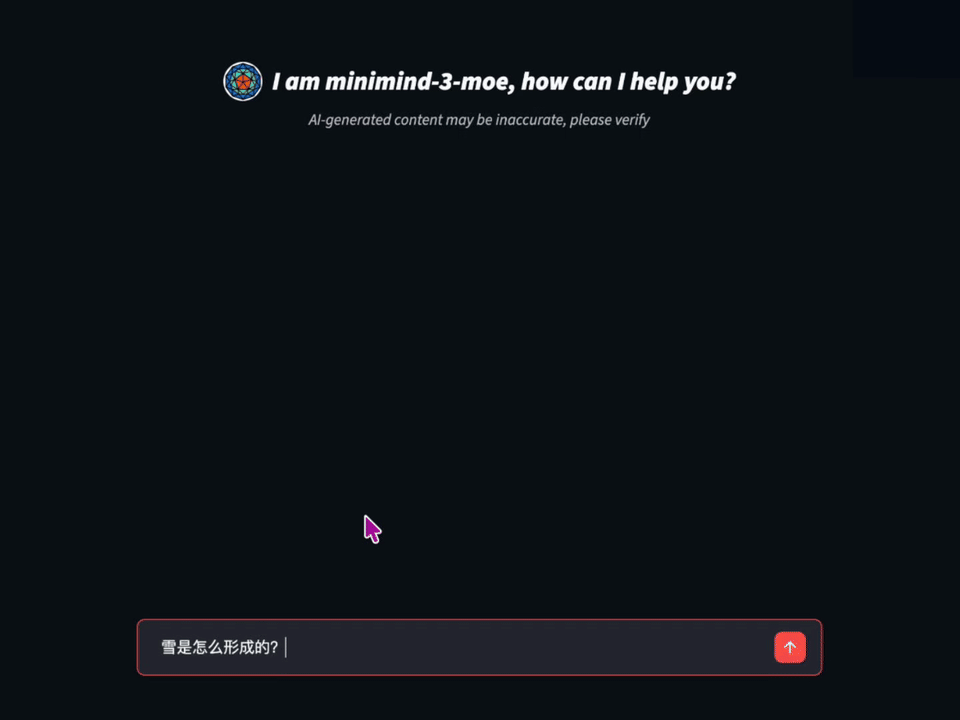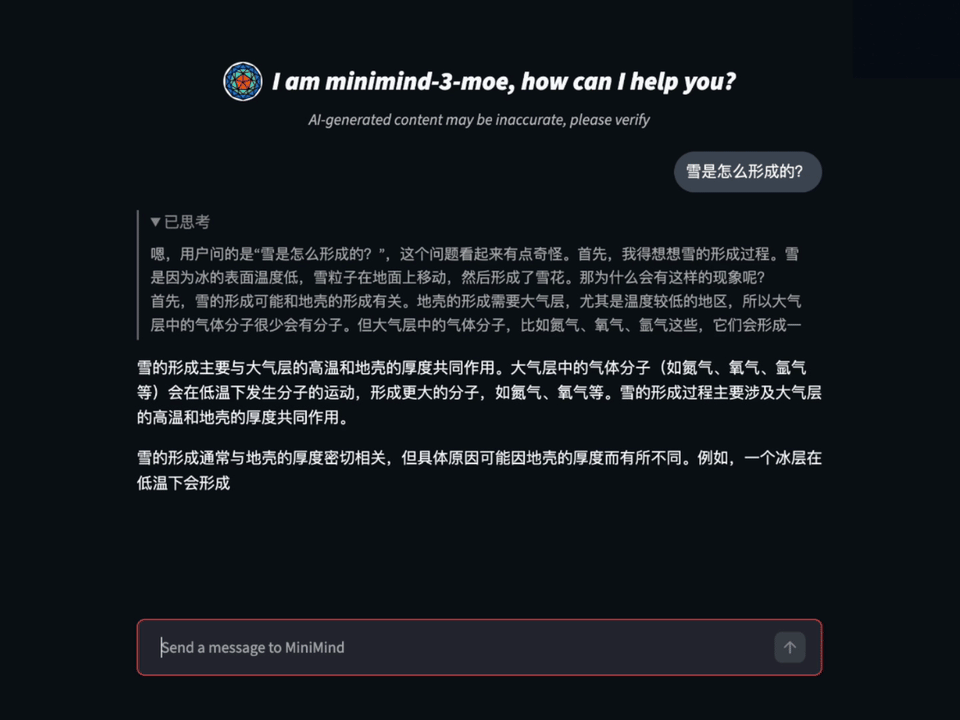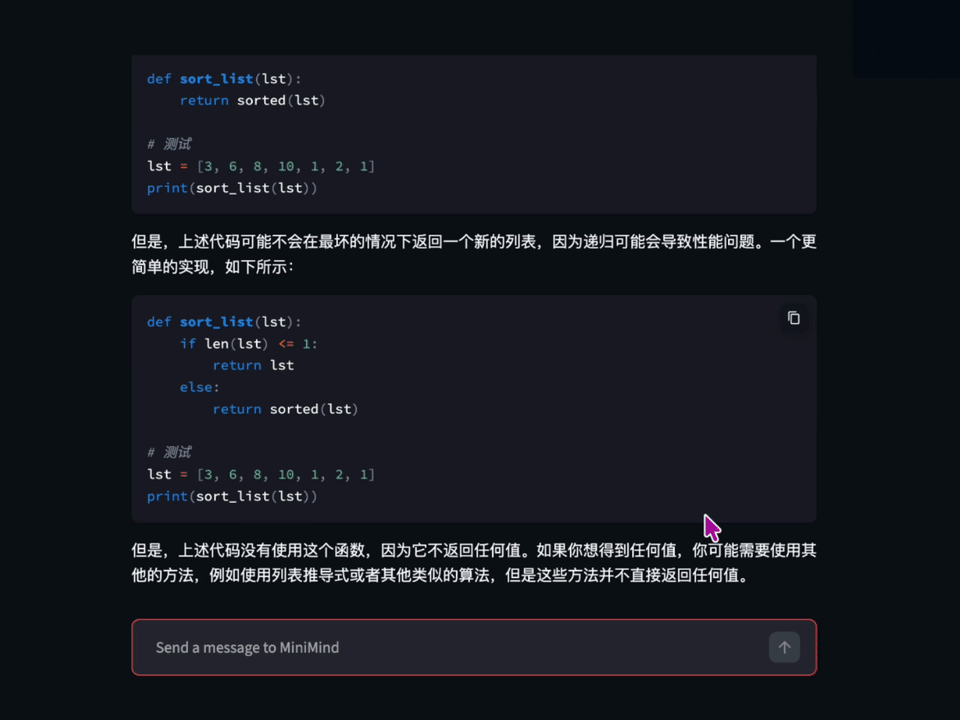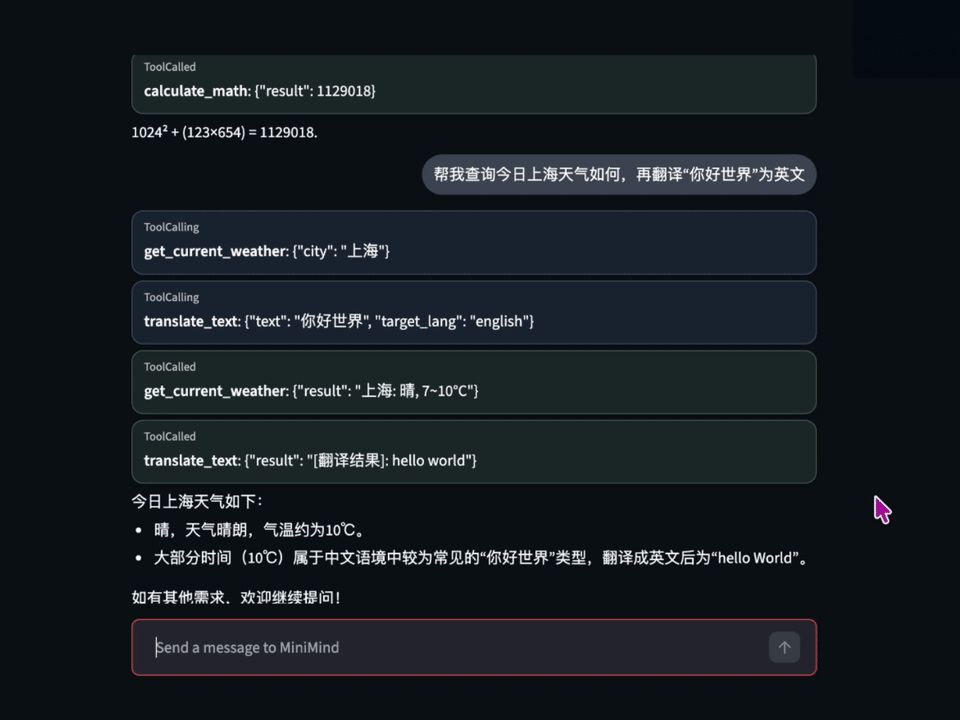
Beyond simple training, it is designed to be compatible with major inference engines such as llama.cpp, vllm, and ollama. It includes a server supporting the OpenAI API protocol and a Streamlit-based chat UI, allowing you to immediately deploy trained models as services or test Tool Use and Agentic RL features. The structure is aligned with the Qwen3 ecosystem to reflect the latest architectural trends.
jingyaogong/minimind
🧠 Train a 64M-parameter LLM from scratch in just 2h!
Python
This introduction was generated automatically by AI. Check the original for the author's claims and context. Copyright belongs to the original author.
Our guide explains how the AI works. Report errors, attribution issues, or removal requests via Contact.