 AI Briefing
PickMiMo-V2.6-Flash-RL: 159B Multimodal LLM Understanding Video and Audio Beyond Text
XiaomiMiMo/MiMo-V2.6-Flash-RL
About the project
This is a multimodal language model that accepts and processes images, audio, and video as inputs in addition to text. It can interpret visual information and voice data simultaneously, enabling complex understanding beyond simple text generation.
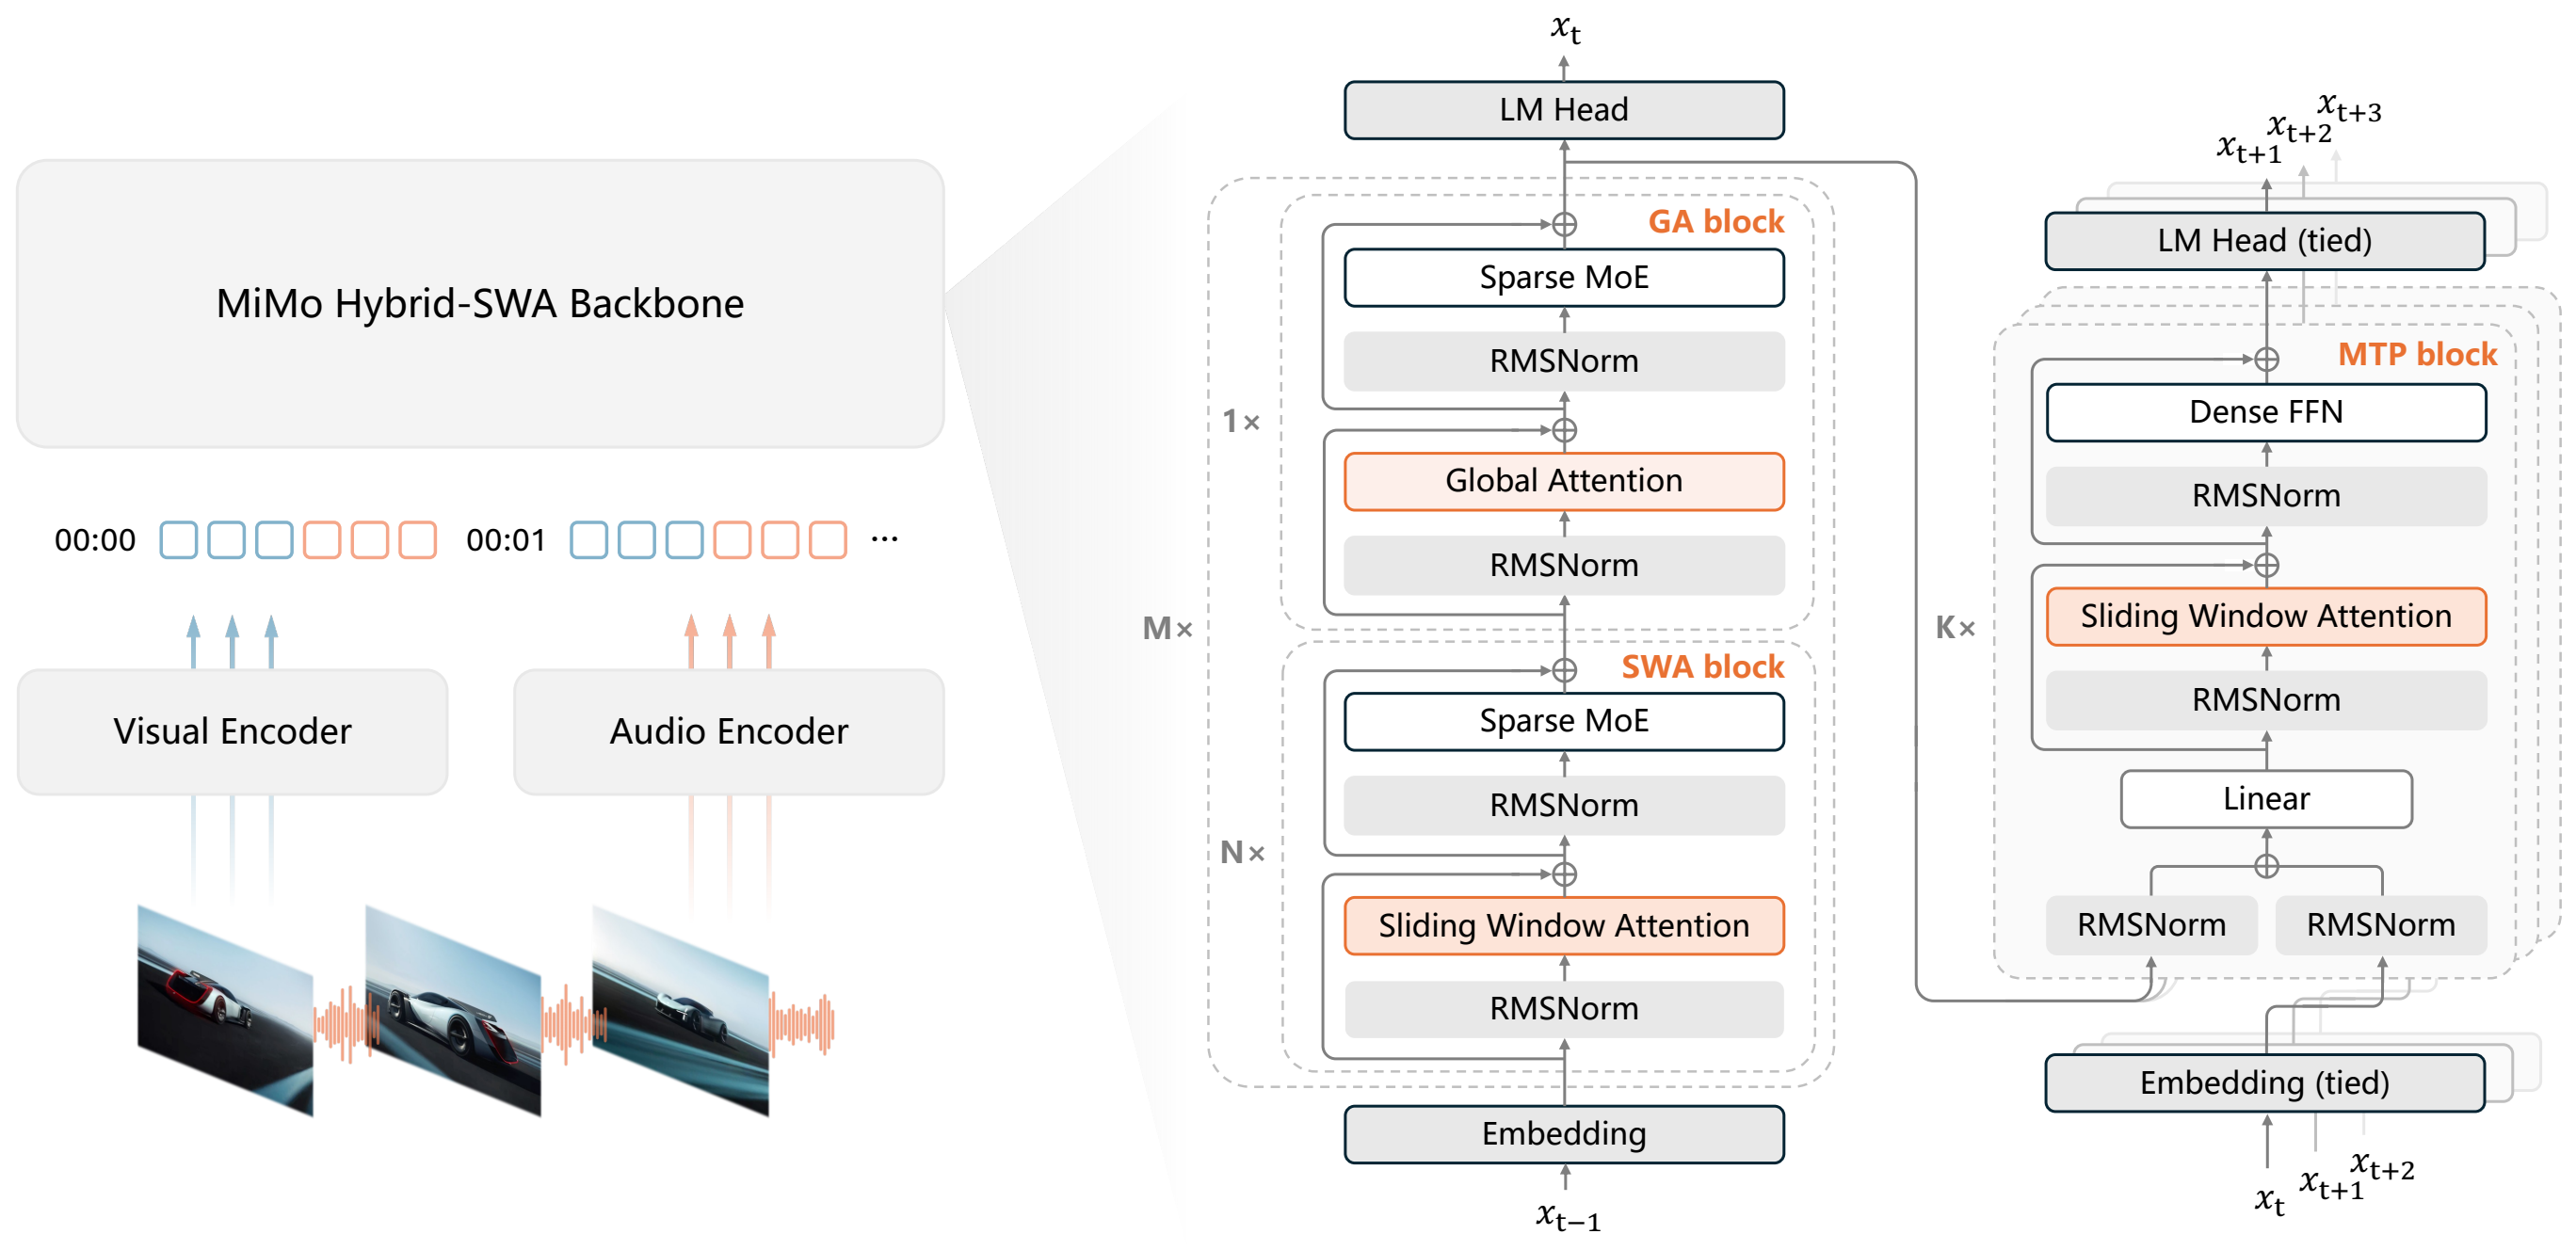
With approximately 159B parameters, it supports long-context capabilities for effectively handling long contexts. It is specialized for agent tasks, making it suitable for external tool calling and complex reasoning processes.
Based on English and Chinese, it supports FP8 and 8-bit precision quantization to ensure flexibility according to deployment environments. It can be easily loaded via the Transformers library and is freely usable in the open-source ecosystem under the MIT license.
XiaomiMiMo/MiMo-V2.6-Flash-RL
The original page has no description.
text-generation
This introduction was generated automatically by AI. Check the original for the author's claims and context. Copyright belongs to the original author.
Our guide explains how the AI works. Report errors, attribution issues, or removal requests via Contact.