 AI Briefing
MiMo-V2.6-Pro-RL: TerminalBench 89.9, Agent Coding Specialized Model
XiaomiMiMo/MiMo-V2.6-Pro-RL
About the project
Achieved a score of 89.9 on the TerminalBench 2.1 benchmark, demonstrating the ability to control complex terminal environments. It also scored 71.9 on the Deep Swe benchmark, showing high performance in real-world software development scenarios. With a Toolathlon Verified evaluation score of 76.9, external tool invocation and agent task execution are implemented reliably.
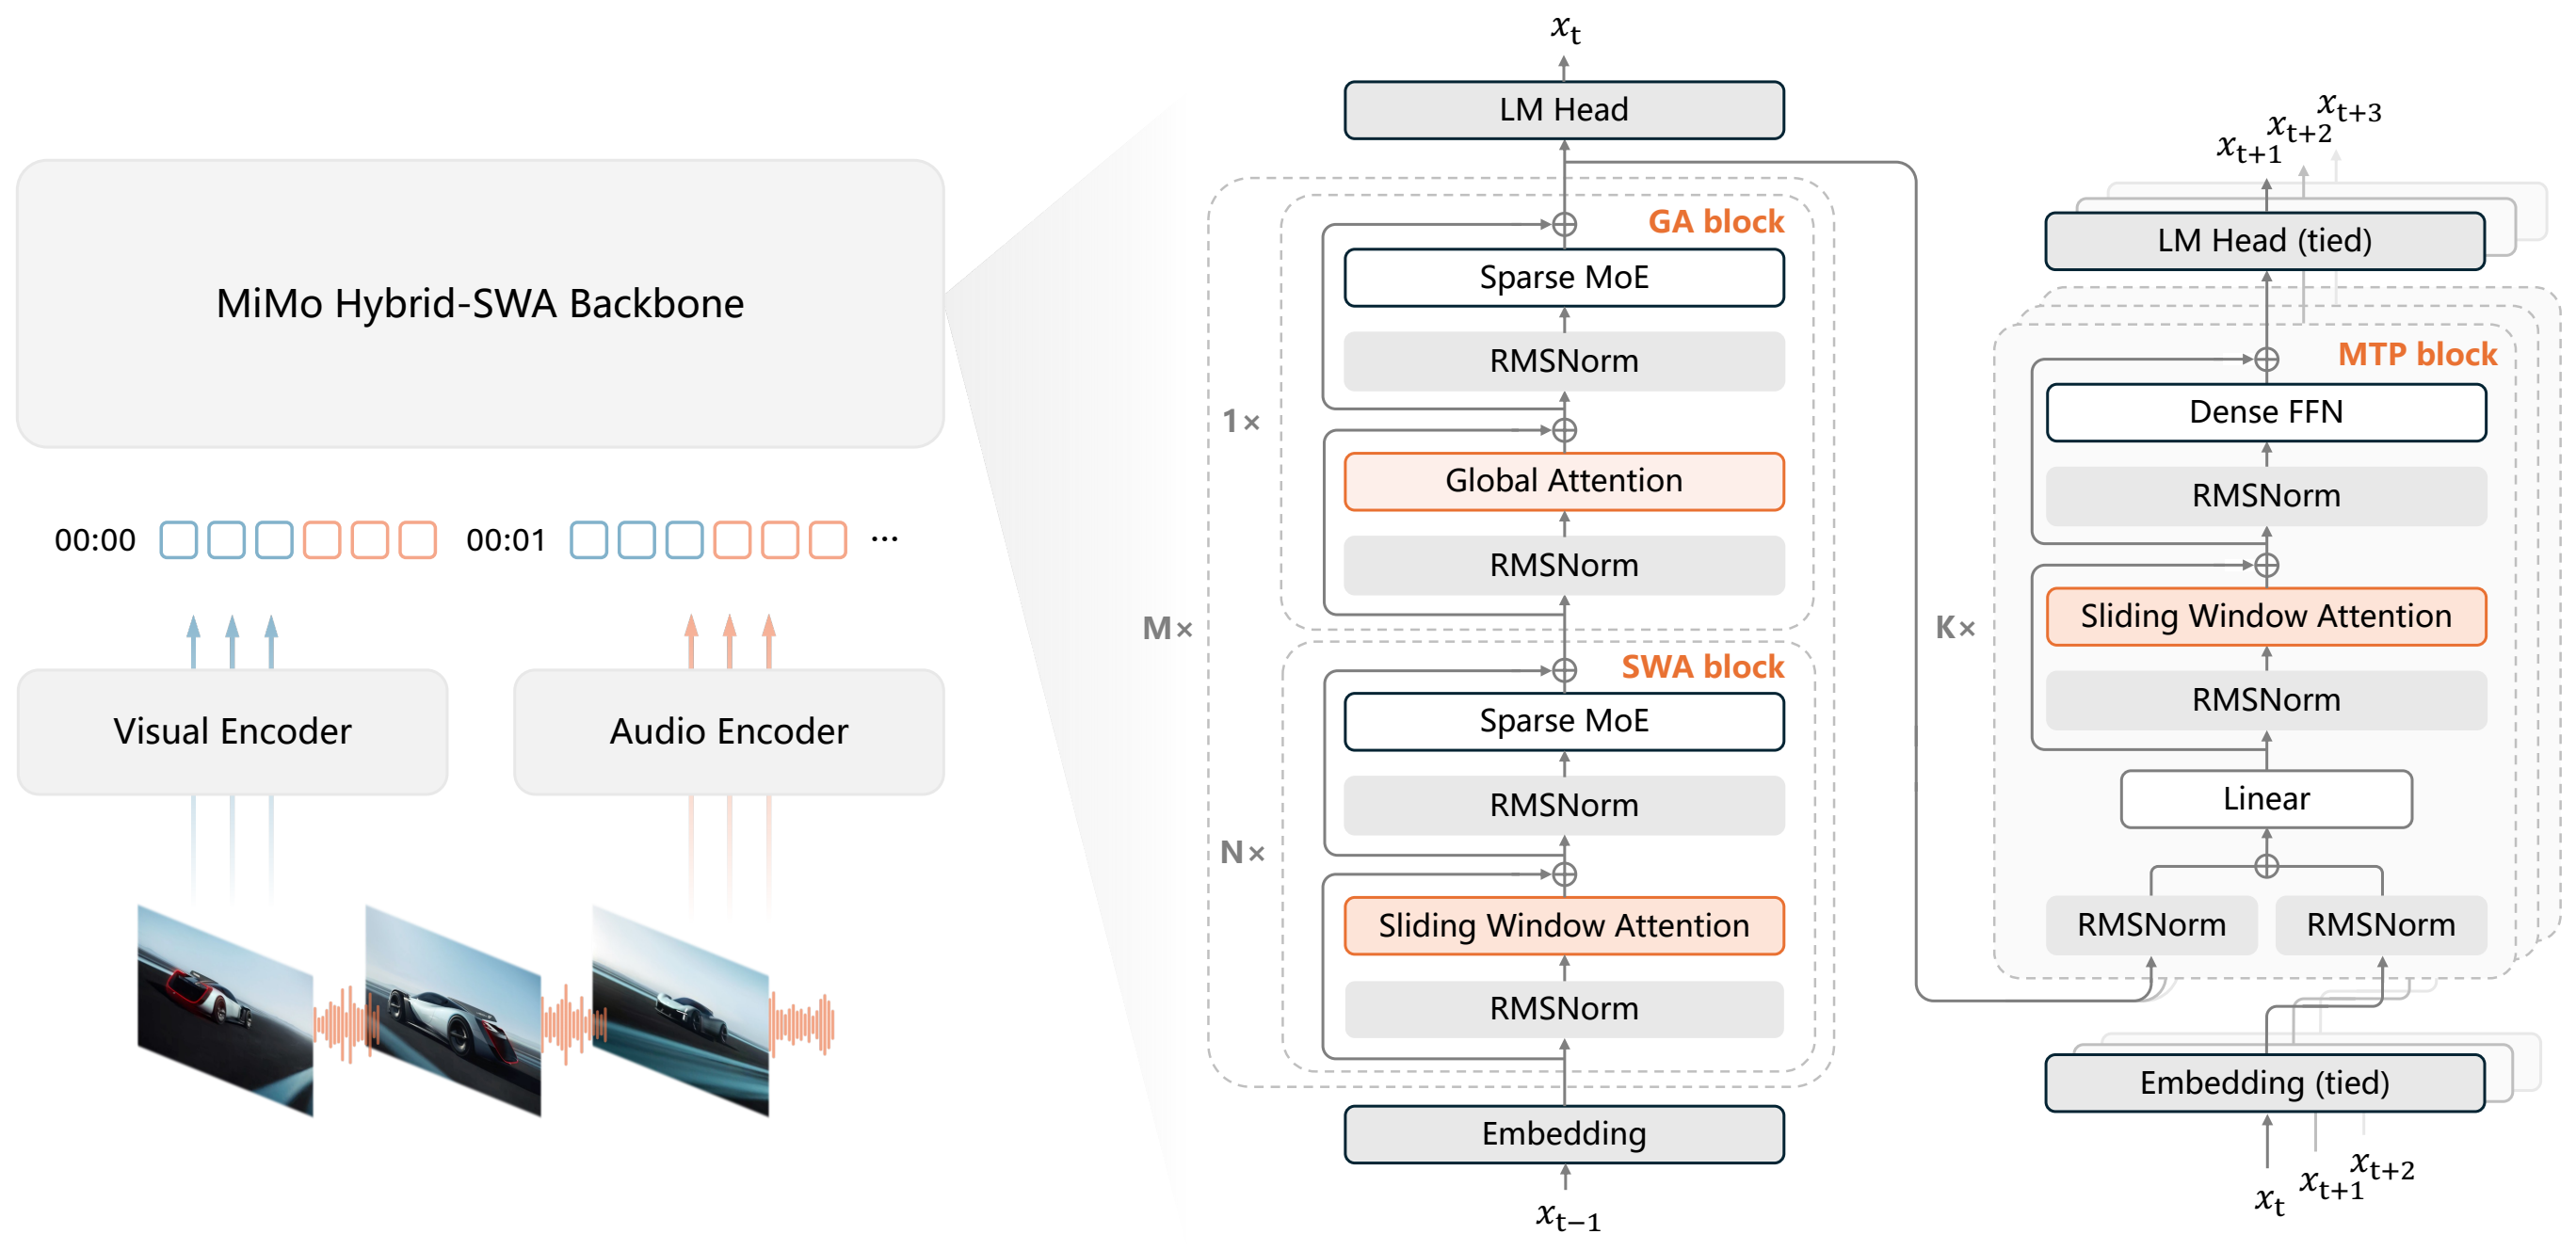
It features a multimodal architecture capable of processing text, images, audio, and video inputs. It supports long contexts, allowing for the analysis of vast codebases or entire documents at once. With built-in thinking mode and tool call capabilities, it is suitable for agent applications requiring complex logical reasoning and external API integration.
With approximately 524B parameters, it supports FP8 and 8-bit quantization formats, ensuring deployment flexibility. Under the MIT license, it can be adopted for commercial projects without restrictions. Optimized for English and Chinese processing, it is well-suited for developing coding agents or multimodal chatbots.
XiaomiMiMo/MiMo-V2.6-Pro-RL
The original page has no description.
text-generation
This introduction was generated automatically by AI. Check the original for the author's claims and context. Copyright belongs to the original author.
Our guide explains how the AI works. Report errors, attribution issues, or removal requests via Contact.