 AI Briefing
DeepSeek-V4.1-Flash: 552B Parameters, KV Cache Compressed to 890 Bytes per Token
deepseek-ai/DeepSeek-V4.1-Flash
About the project
A multimodal MoE model with 552B backbone parameters supports a 1M token context. It accepts text and images as simultaneous inputs to generate text, using 45T tokens for pre-training.
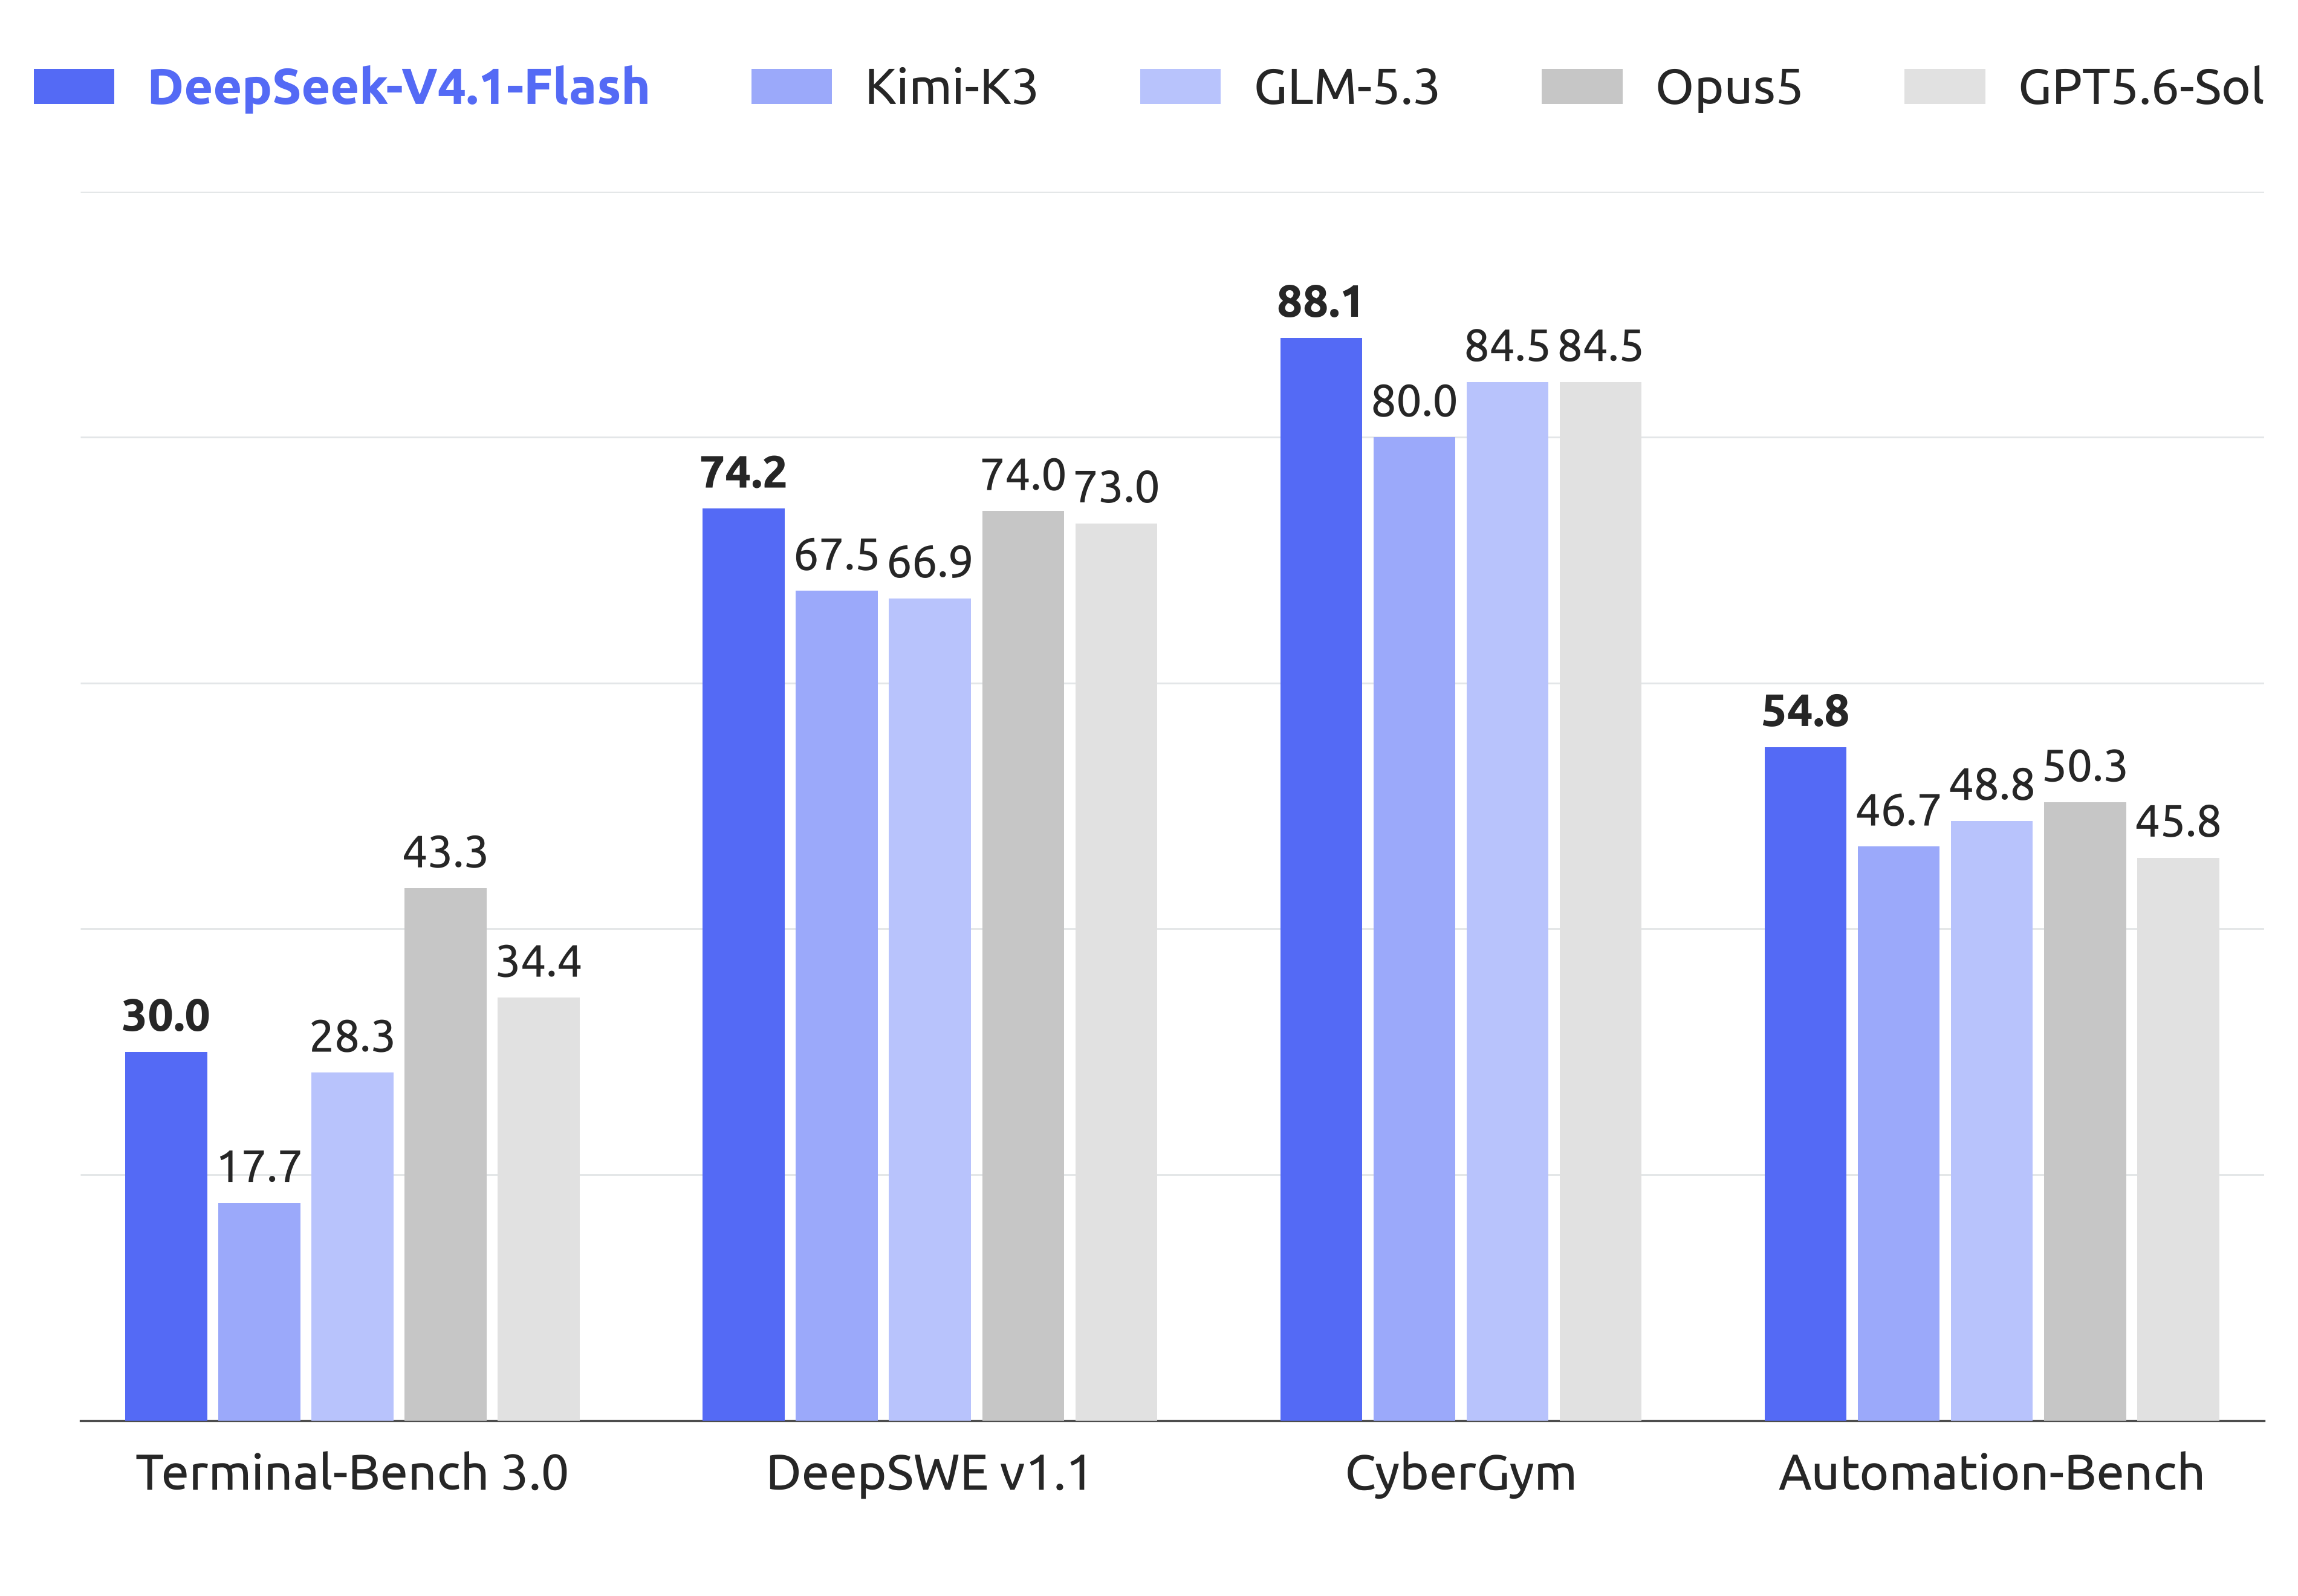
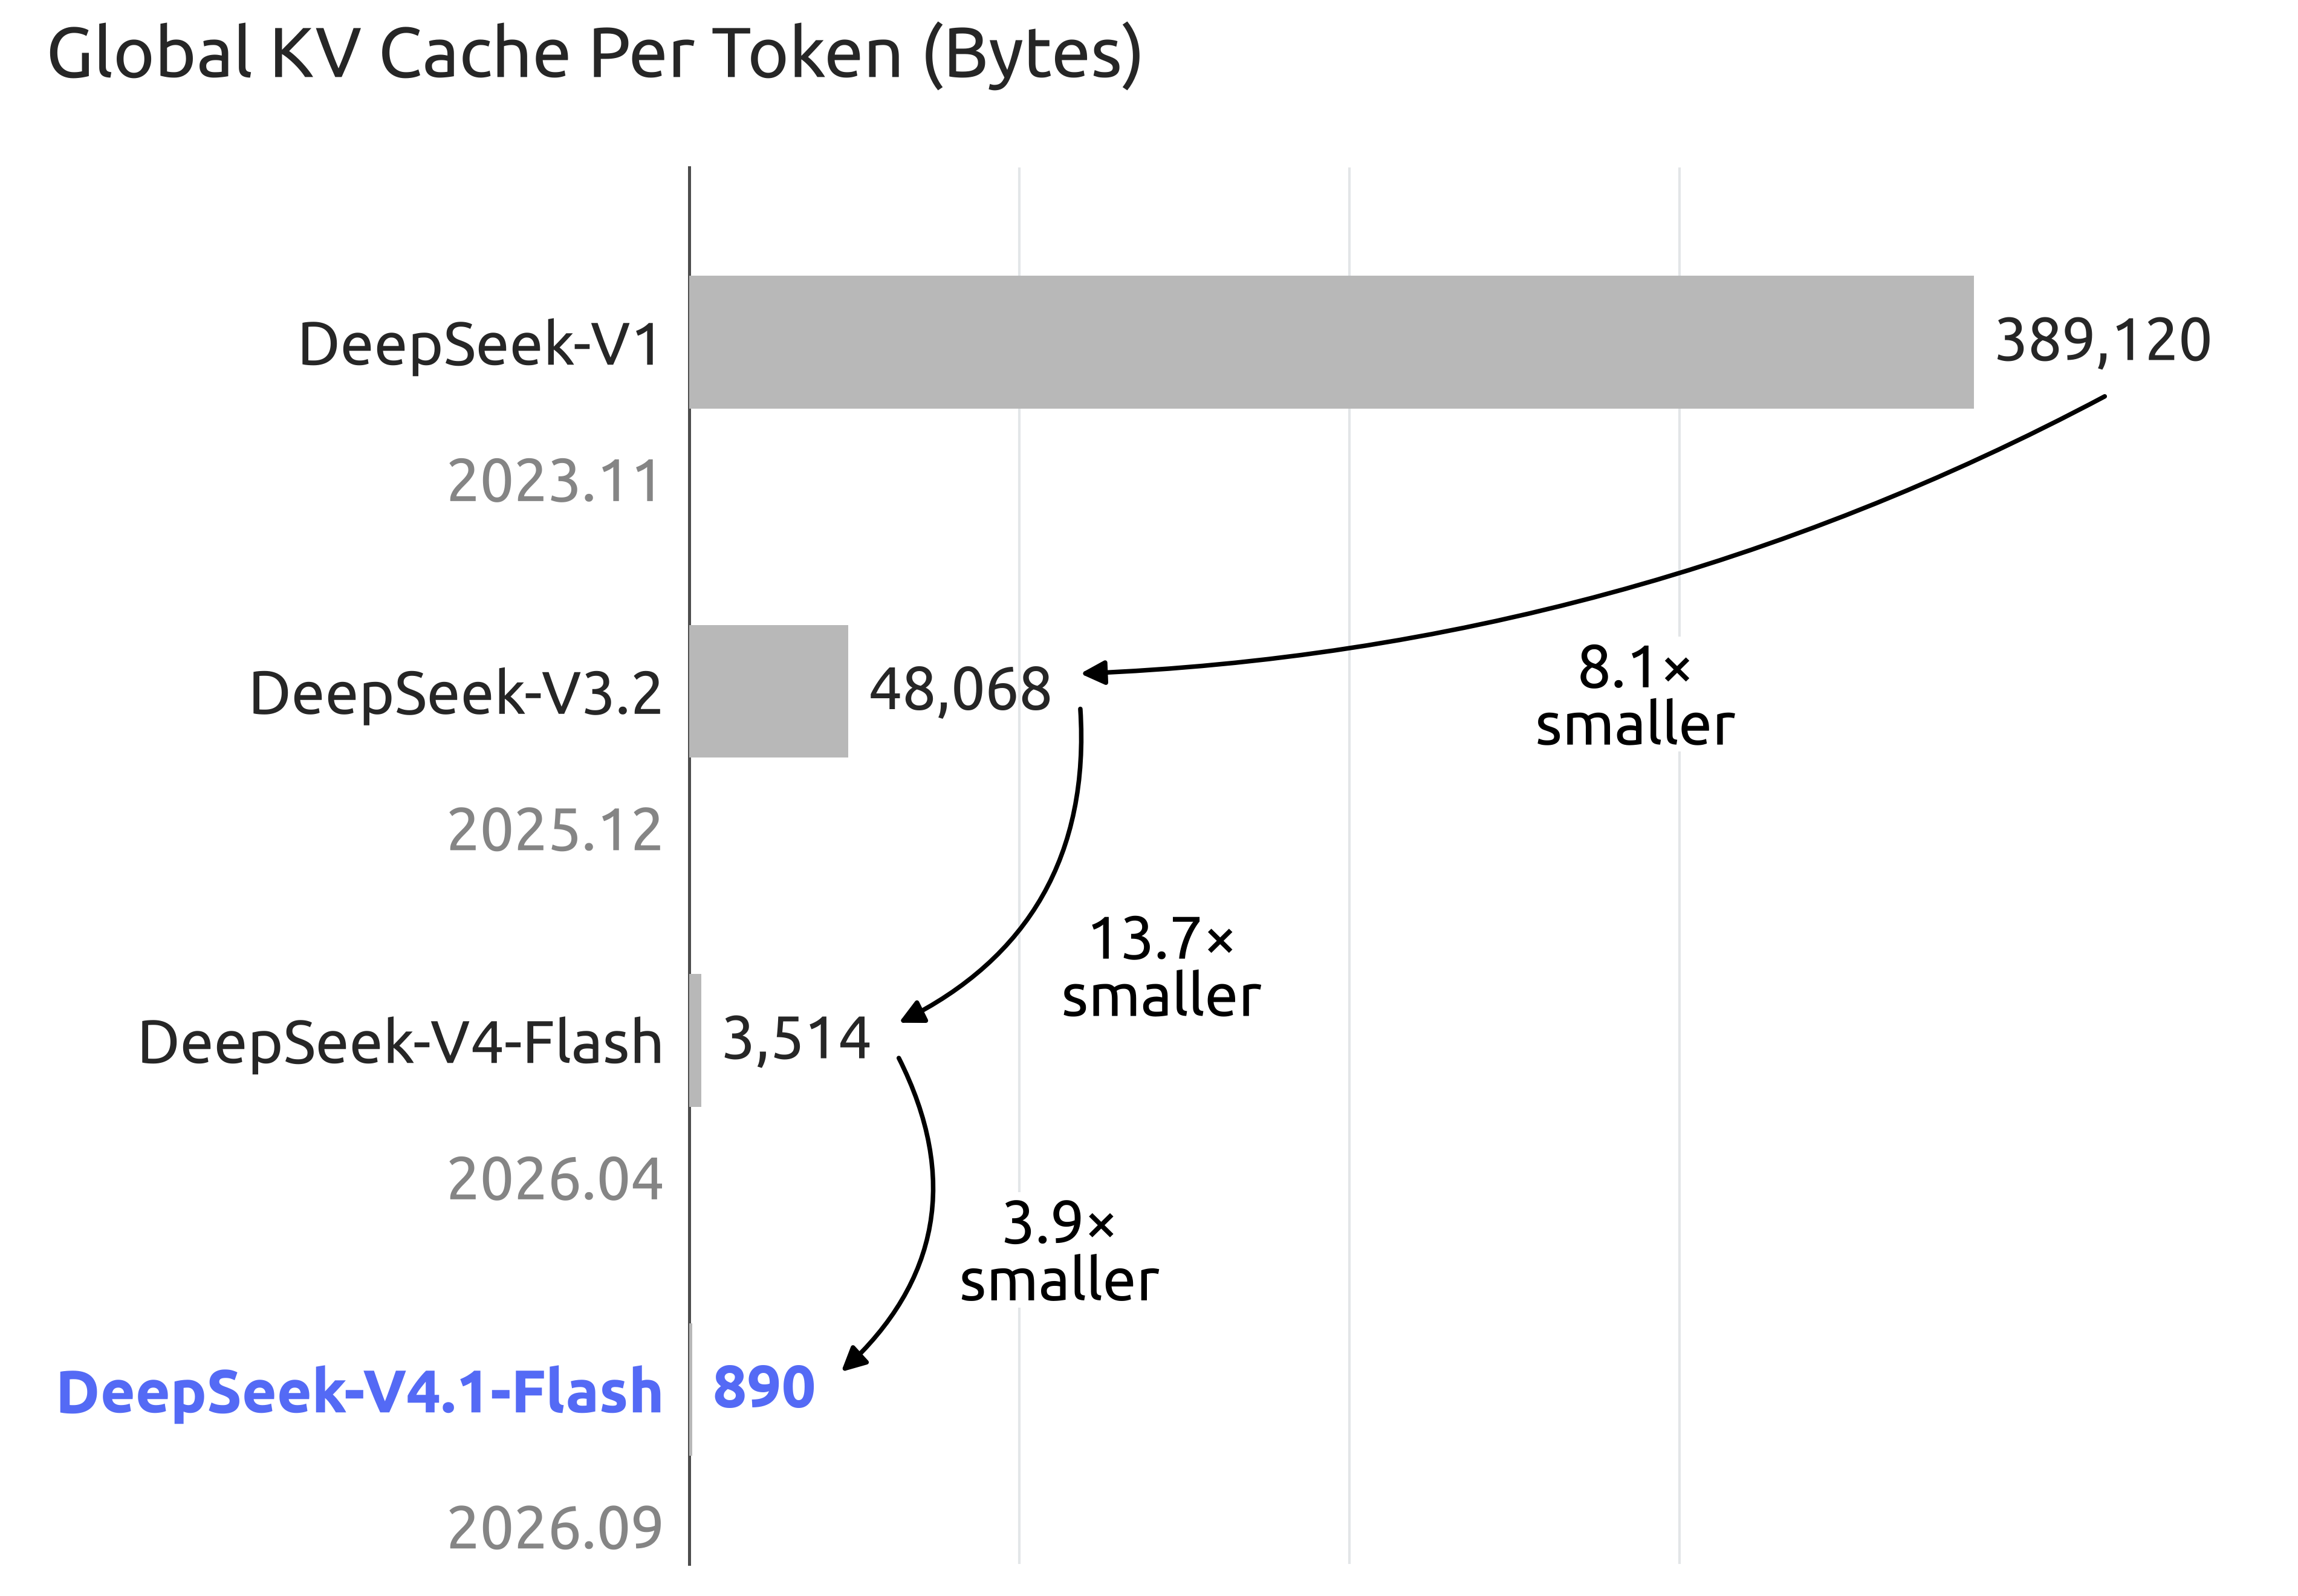
By applying a Causal Encoder-Decoder architecture and CSA2 technique, the global KV cache is reduced to 890 bytes per token. This is approximately one-quarter of the previous generation, improving cost efficiency for agent tasks with large inputs.
Only 8B parameters are activated during the prefill stage and 16B during the decode stage. A tunable reasoning intensity setting from 1 to 100 allows direct control over the balance between accuracy and computational cost.
deepseek-ai/DeepSeek-V4.1-Flash
The original page has no description.
image-text-to-text
This introduction was generated automatically by AI. Check the original for the author's claims and context. Copyright belongs to the original author.
Our guide explains how the AI works. Report errors, attribution issues, or removal requests via Contact.