 AI Briefing
dots3-note-prev: dots3-note: Ranked #1 among models under 500B, achieving 79.1% on MMMU-Pro
dots-studio/dots3-note-prev
About the project
This is a preview version released from the dots3-note model lineup by dots-studio. It is classified as a multimodal LLM that processes image, audio, and video inputs alongside text generation. Distributed under the Apache-2.0 license, it is available for use in commercial environments.


It highlights long-context processing and agentic task execution as key features. It supports a conversational interface and allows automation of workflows that execute external APIs or functions through tool calling capabilities. It is specialized for code writing and problem-solving tasks that require complex reasoning.
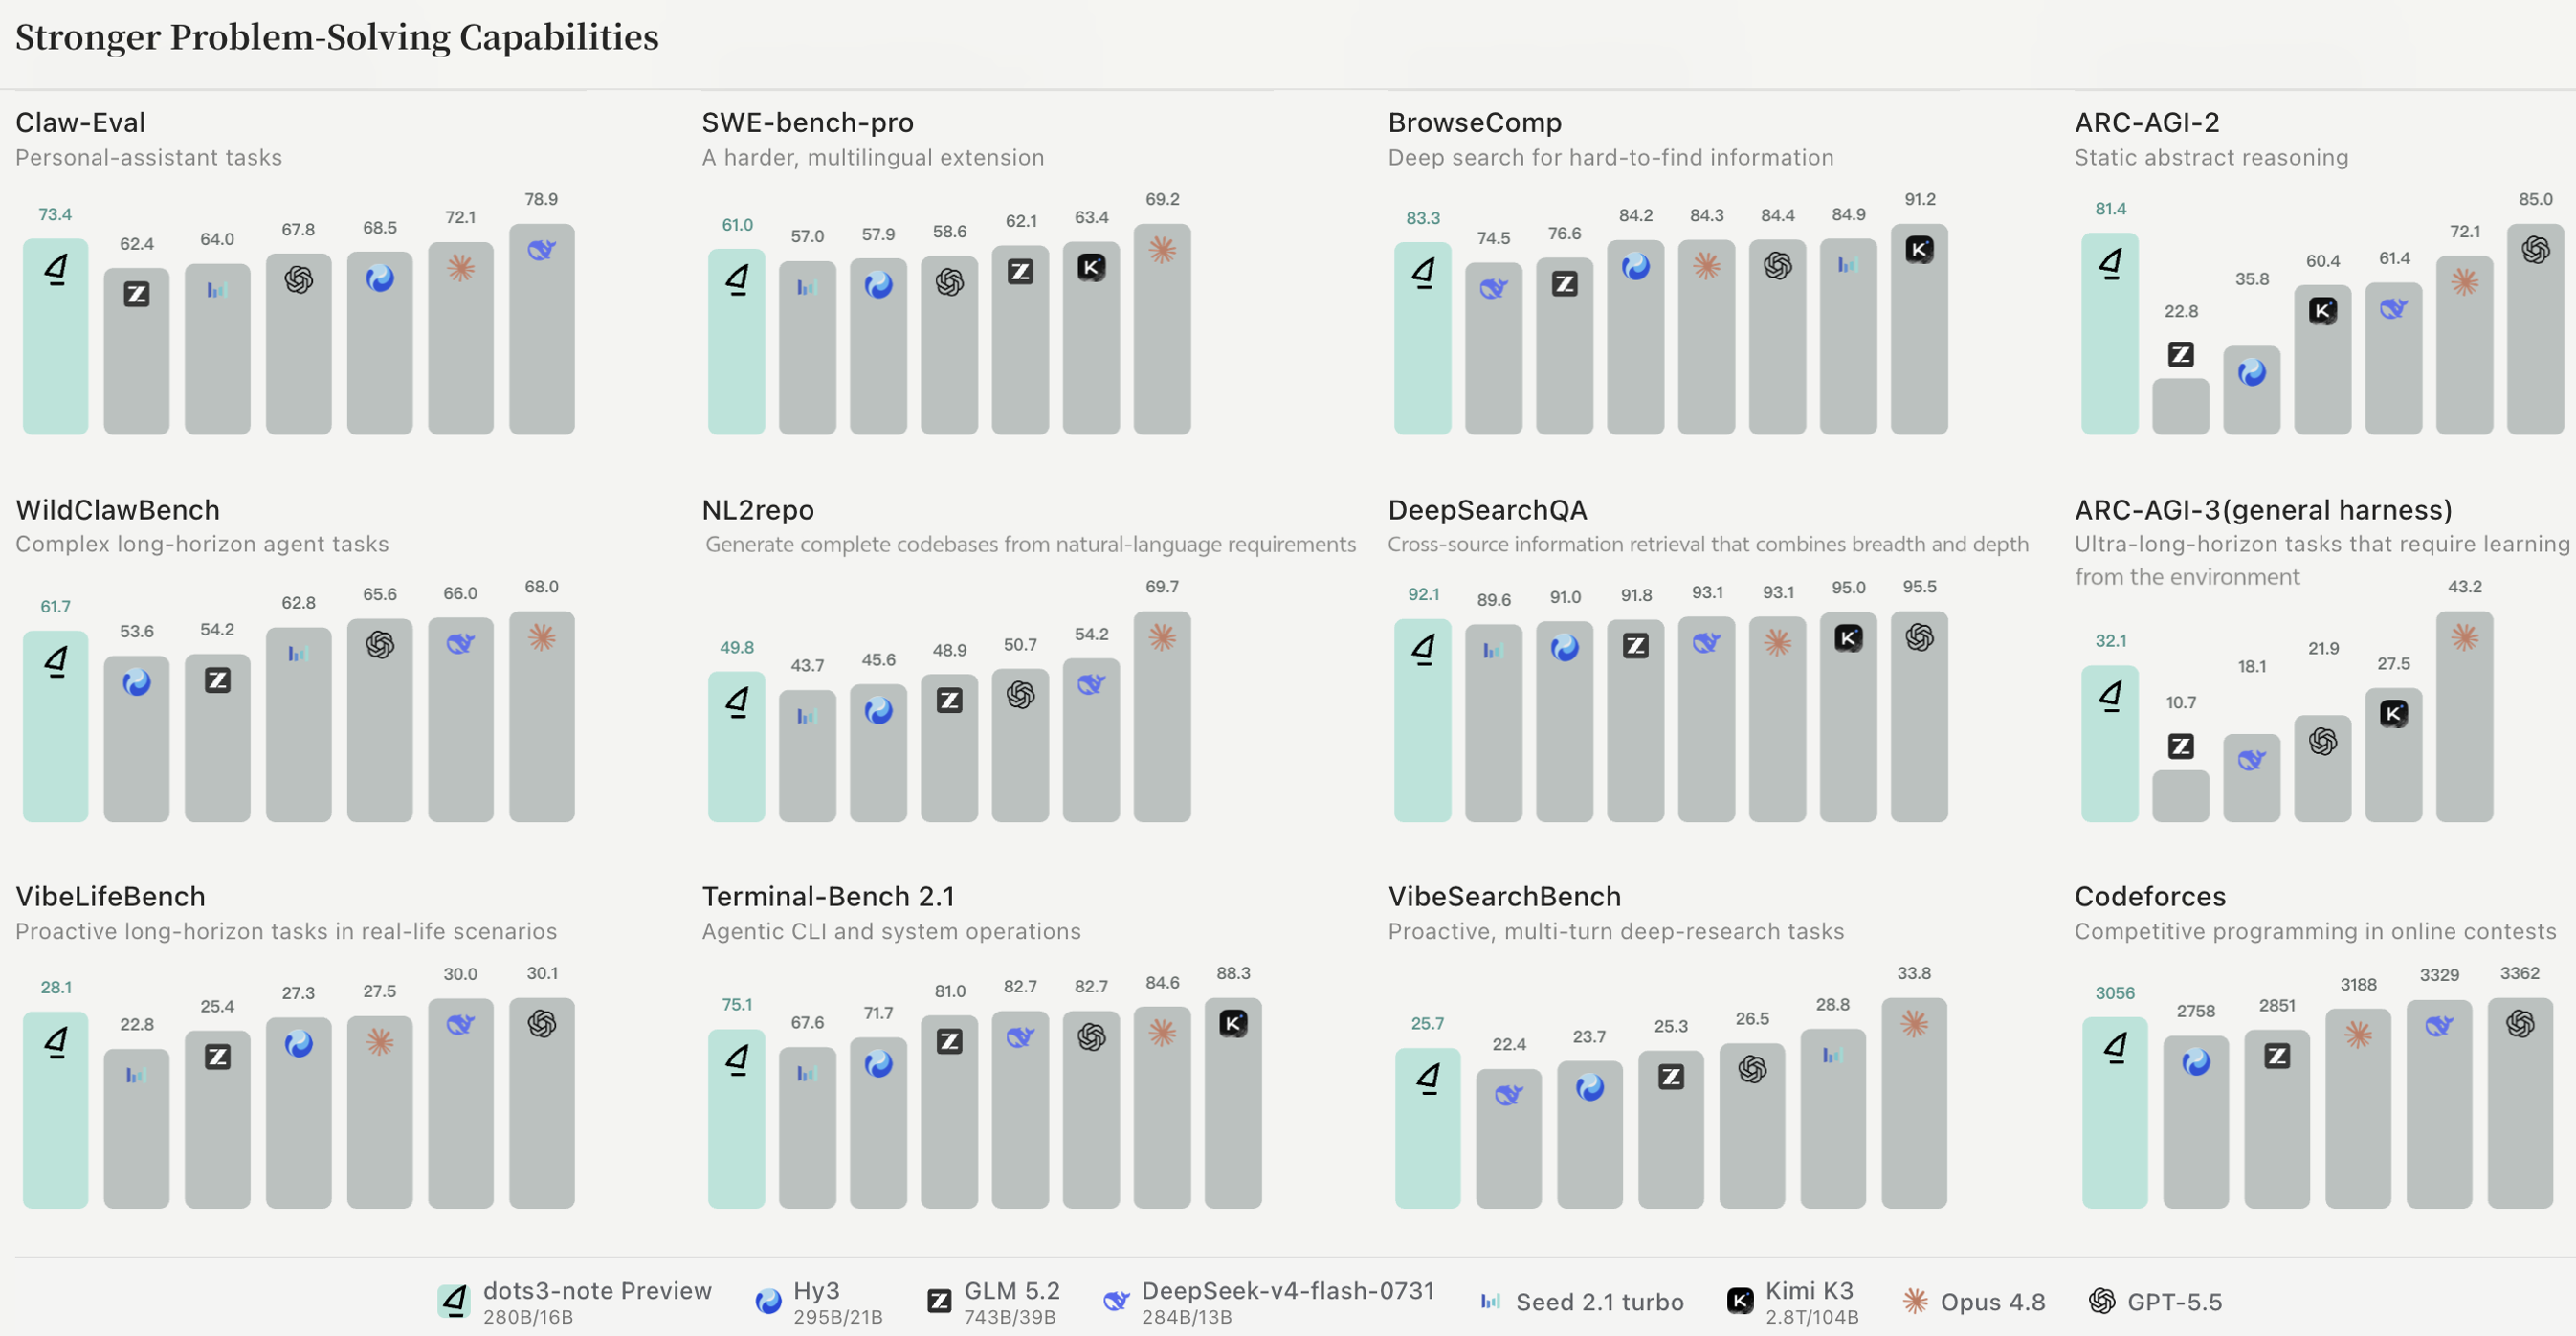
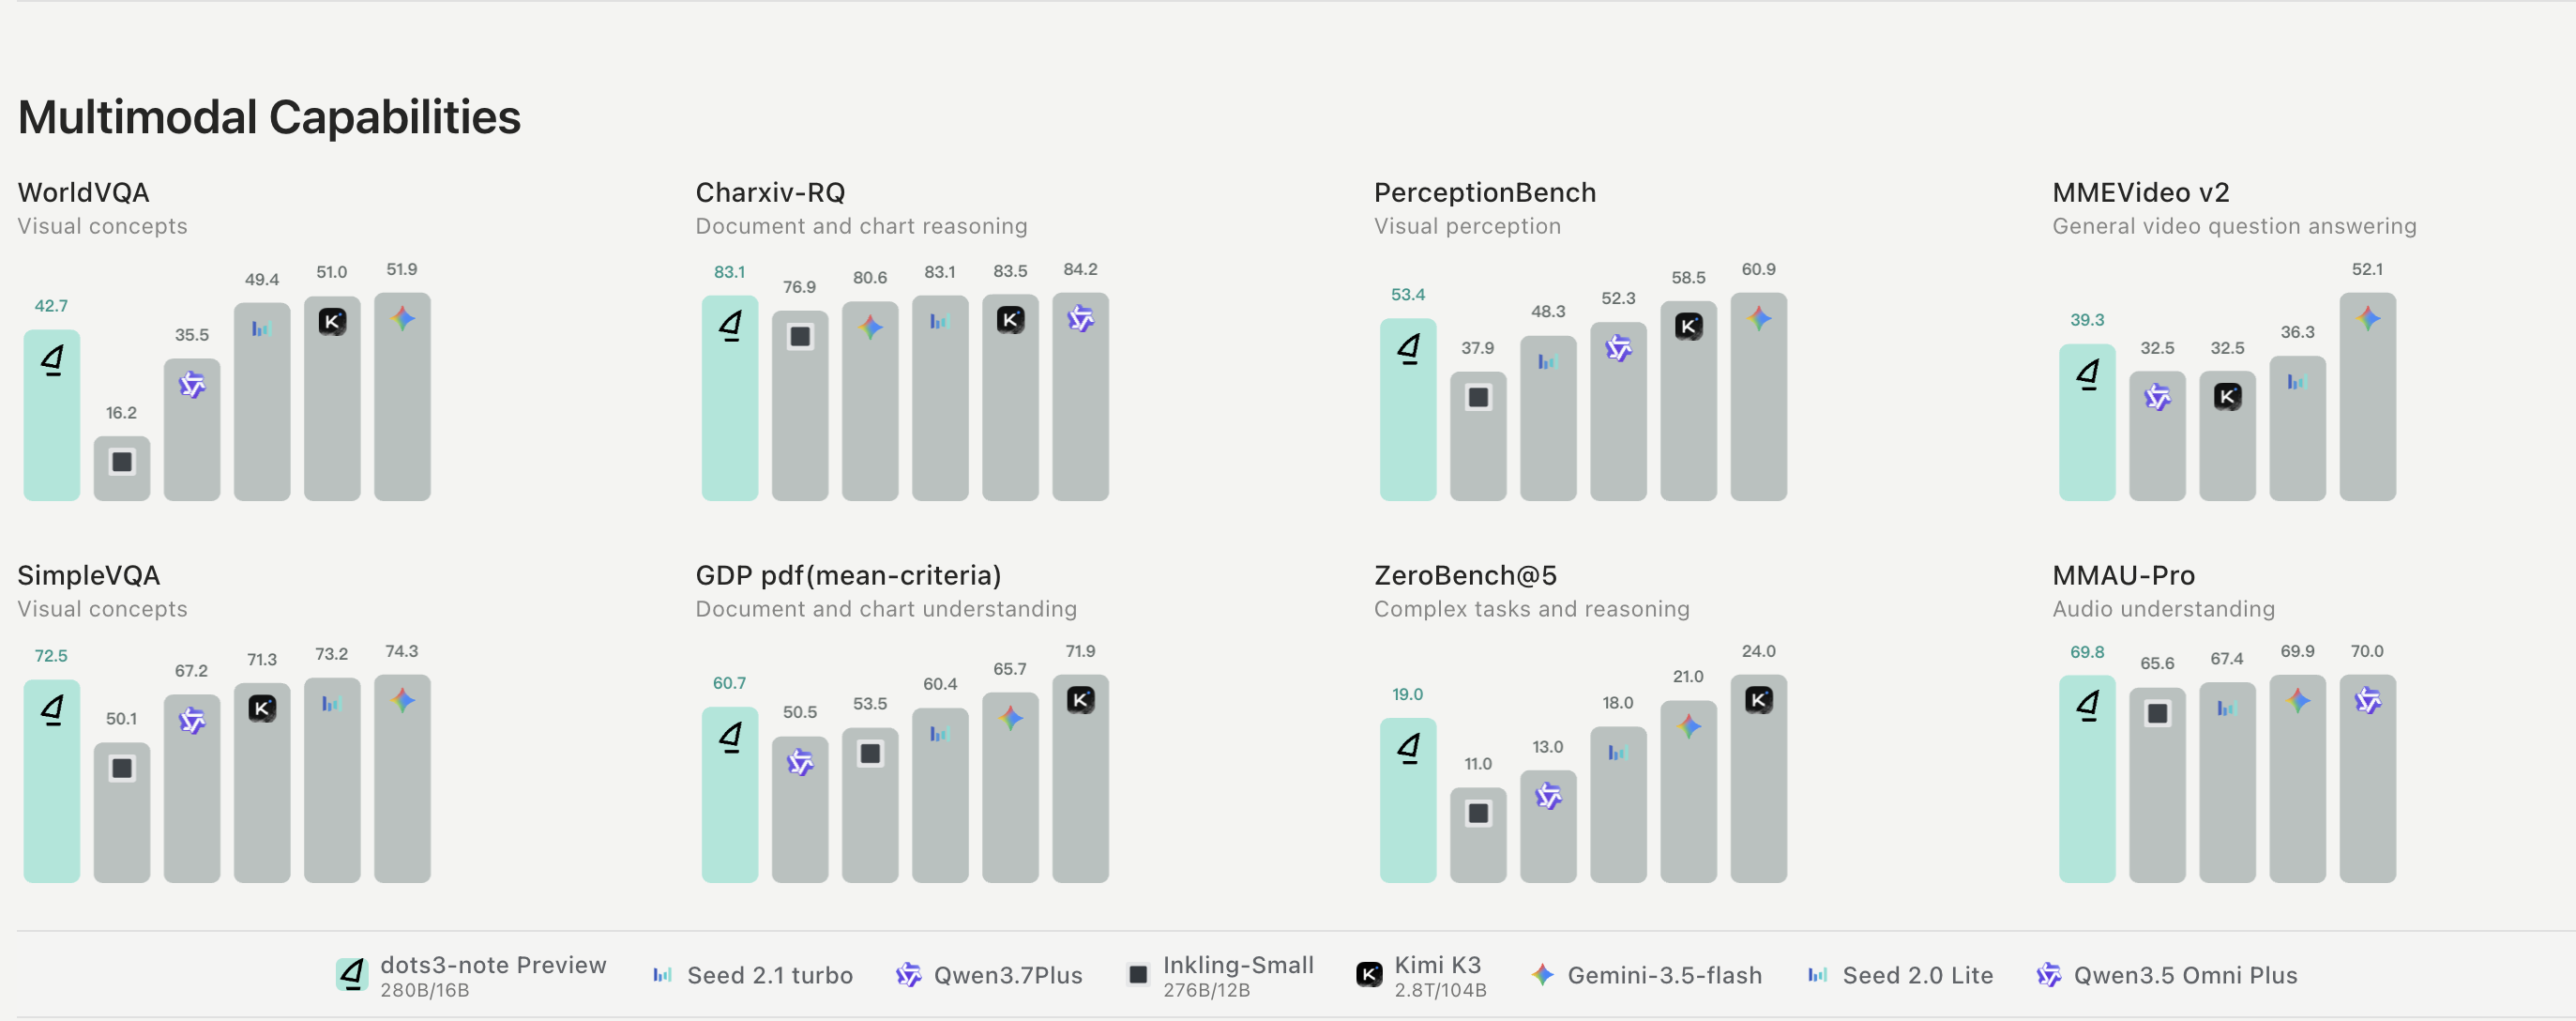
According to published benchmark results, it recorded scores of 78.4% on SWE-bench Verified and 61% on SWE-bench Pro. It achieved 79.1% on MMMU-Pro, which measures multimodal understanding, ranking first among models with fewer than 500B parameters. Additionally, it showed top-tier performance among comparable models with a comprehensive score of 61.7% on WildClawBench.
It is suitable for developers planning software engineering automation, complex multimodal data analysis, and building tool-based agent systems. Given its verified performance in code modification and bug fixing (SWE-bench), it has value for use in CI/CD pipelines or code review assistance tools. You can run inference directly via the Transformers library or serve it as an API through Hugging Face Inference Endpoints.
dots-studio/dots3-note-prev
The original page has no description.
image-text-to-text
This introduction was generated automatically by AI. Check the original for the author's claims and context. Copyright belongs to the original author.
Our guide explains how the AI works. Report errors, attribution issues, or removal requests via Contact.