 AI Briefing
Minimax-h3-Turbo: 340K Monthly Downloads, Apache-2.0 Video Generation Model
lightx2v/Minimax-h3-Turbo
About the project
This model generates short videos from text prompts and images. It is an optimized version by the LightX2V team based on MiniMaxAI's MiniMax-H3, easily accessible via the Diffusers library. It supports text-to-video (t2v), image-to-video (i2v), and reference-to-video (r2v) tasks.
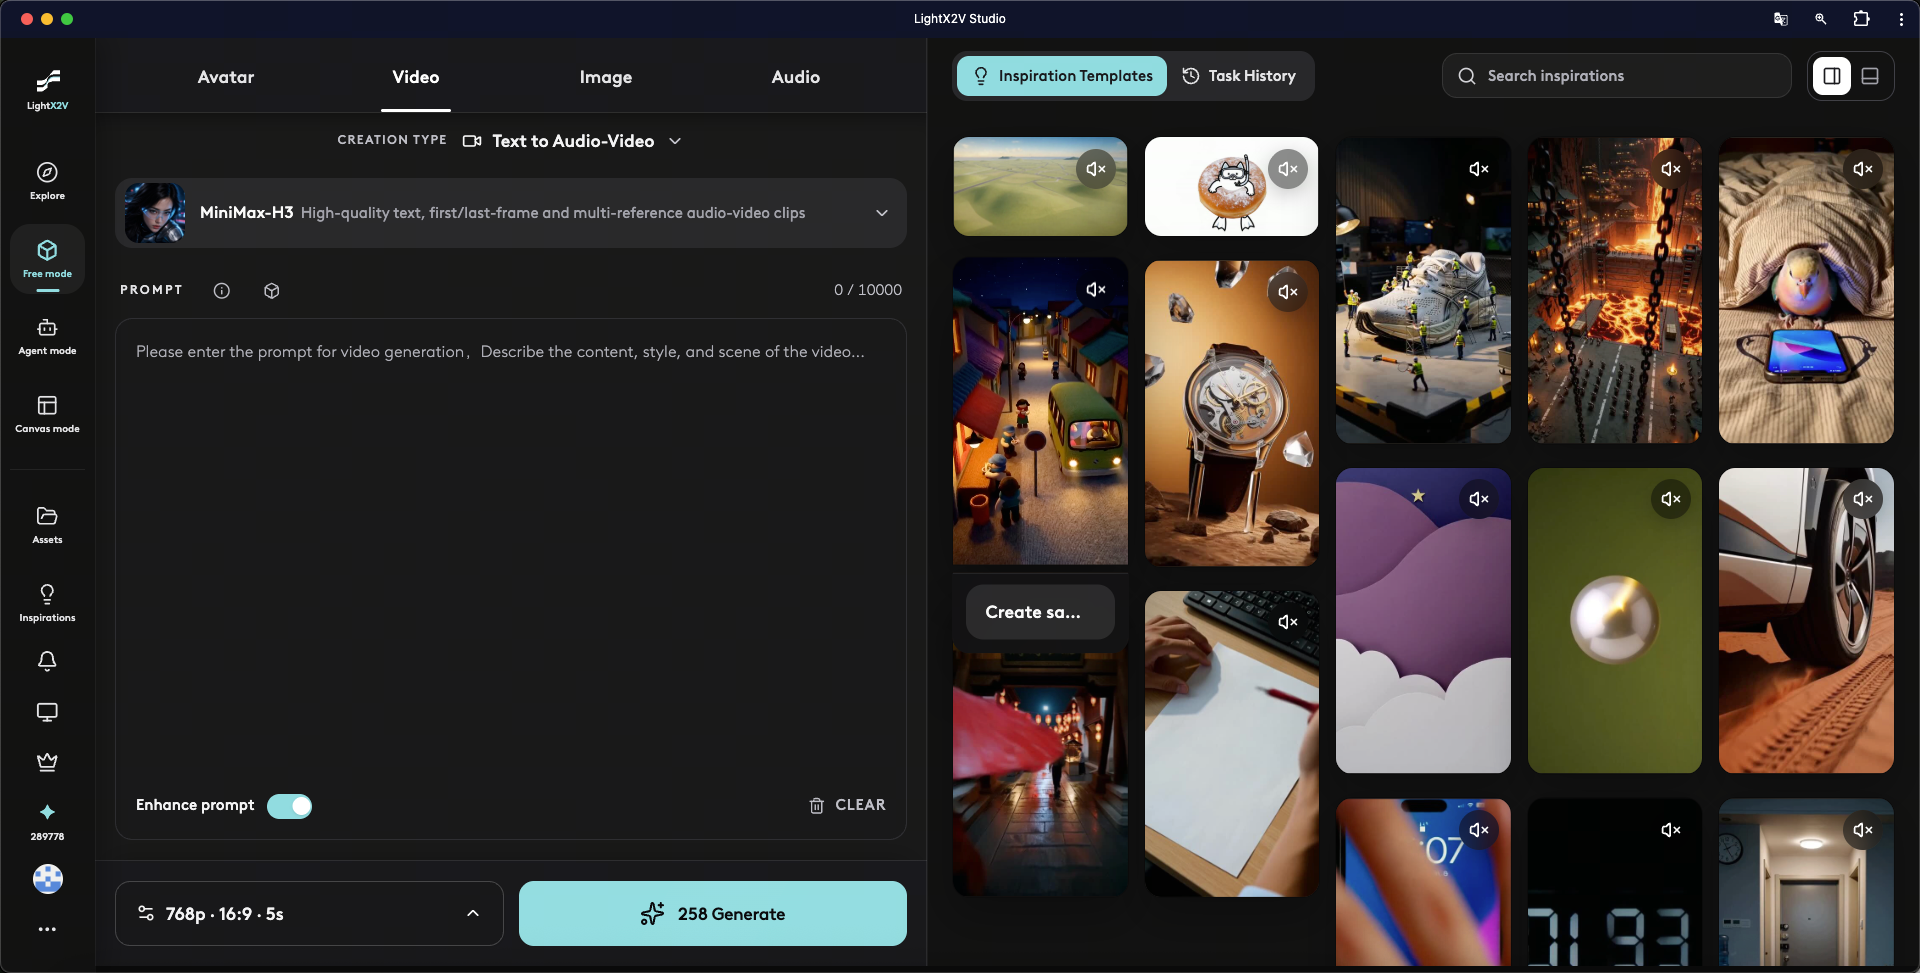
Distributed under the Apache-2.0 license, it can be freely used in commercial projects. It supports English and Chinese prompts, with bfloat16 data type and CUDA devices recommended. On Apple devices, it can be run by specifying the mps device.
The model has garnered significant community interest, with monthly downloads exceeding 340K last month. Various demos utilizing this model can be found across 44 Spaces, and there are 74 derivative models. These metrics demonstrate the model's scalability and practicality.
It is suitable for developers who want to quickly prototype video generation tasks or generate videos in specific styles. Compatible with the Diffusers ecosystem, it can be easily integrated into existing workflows. For detailed model specifications, refer to the official repository.
lightx2v/Minimax-h3-Turbo
The original page has no description.
image-to-video
This introduction was generated automatically by AI. Check the original for the author's claims and context. Copyright belongs to the original author.
Our guide explains how the AI works. Report errors, attribution issues, or removal requests via Contact.