 AI Briefing
Ornith-1.5-35B-A3B-GGUF: 35B MoE, Ultra-Lightweight Inference with 3B Active Parameters
ornith-ai/Ornith-1.5-35B-A3B-GGUF
About the project
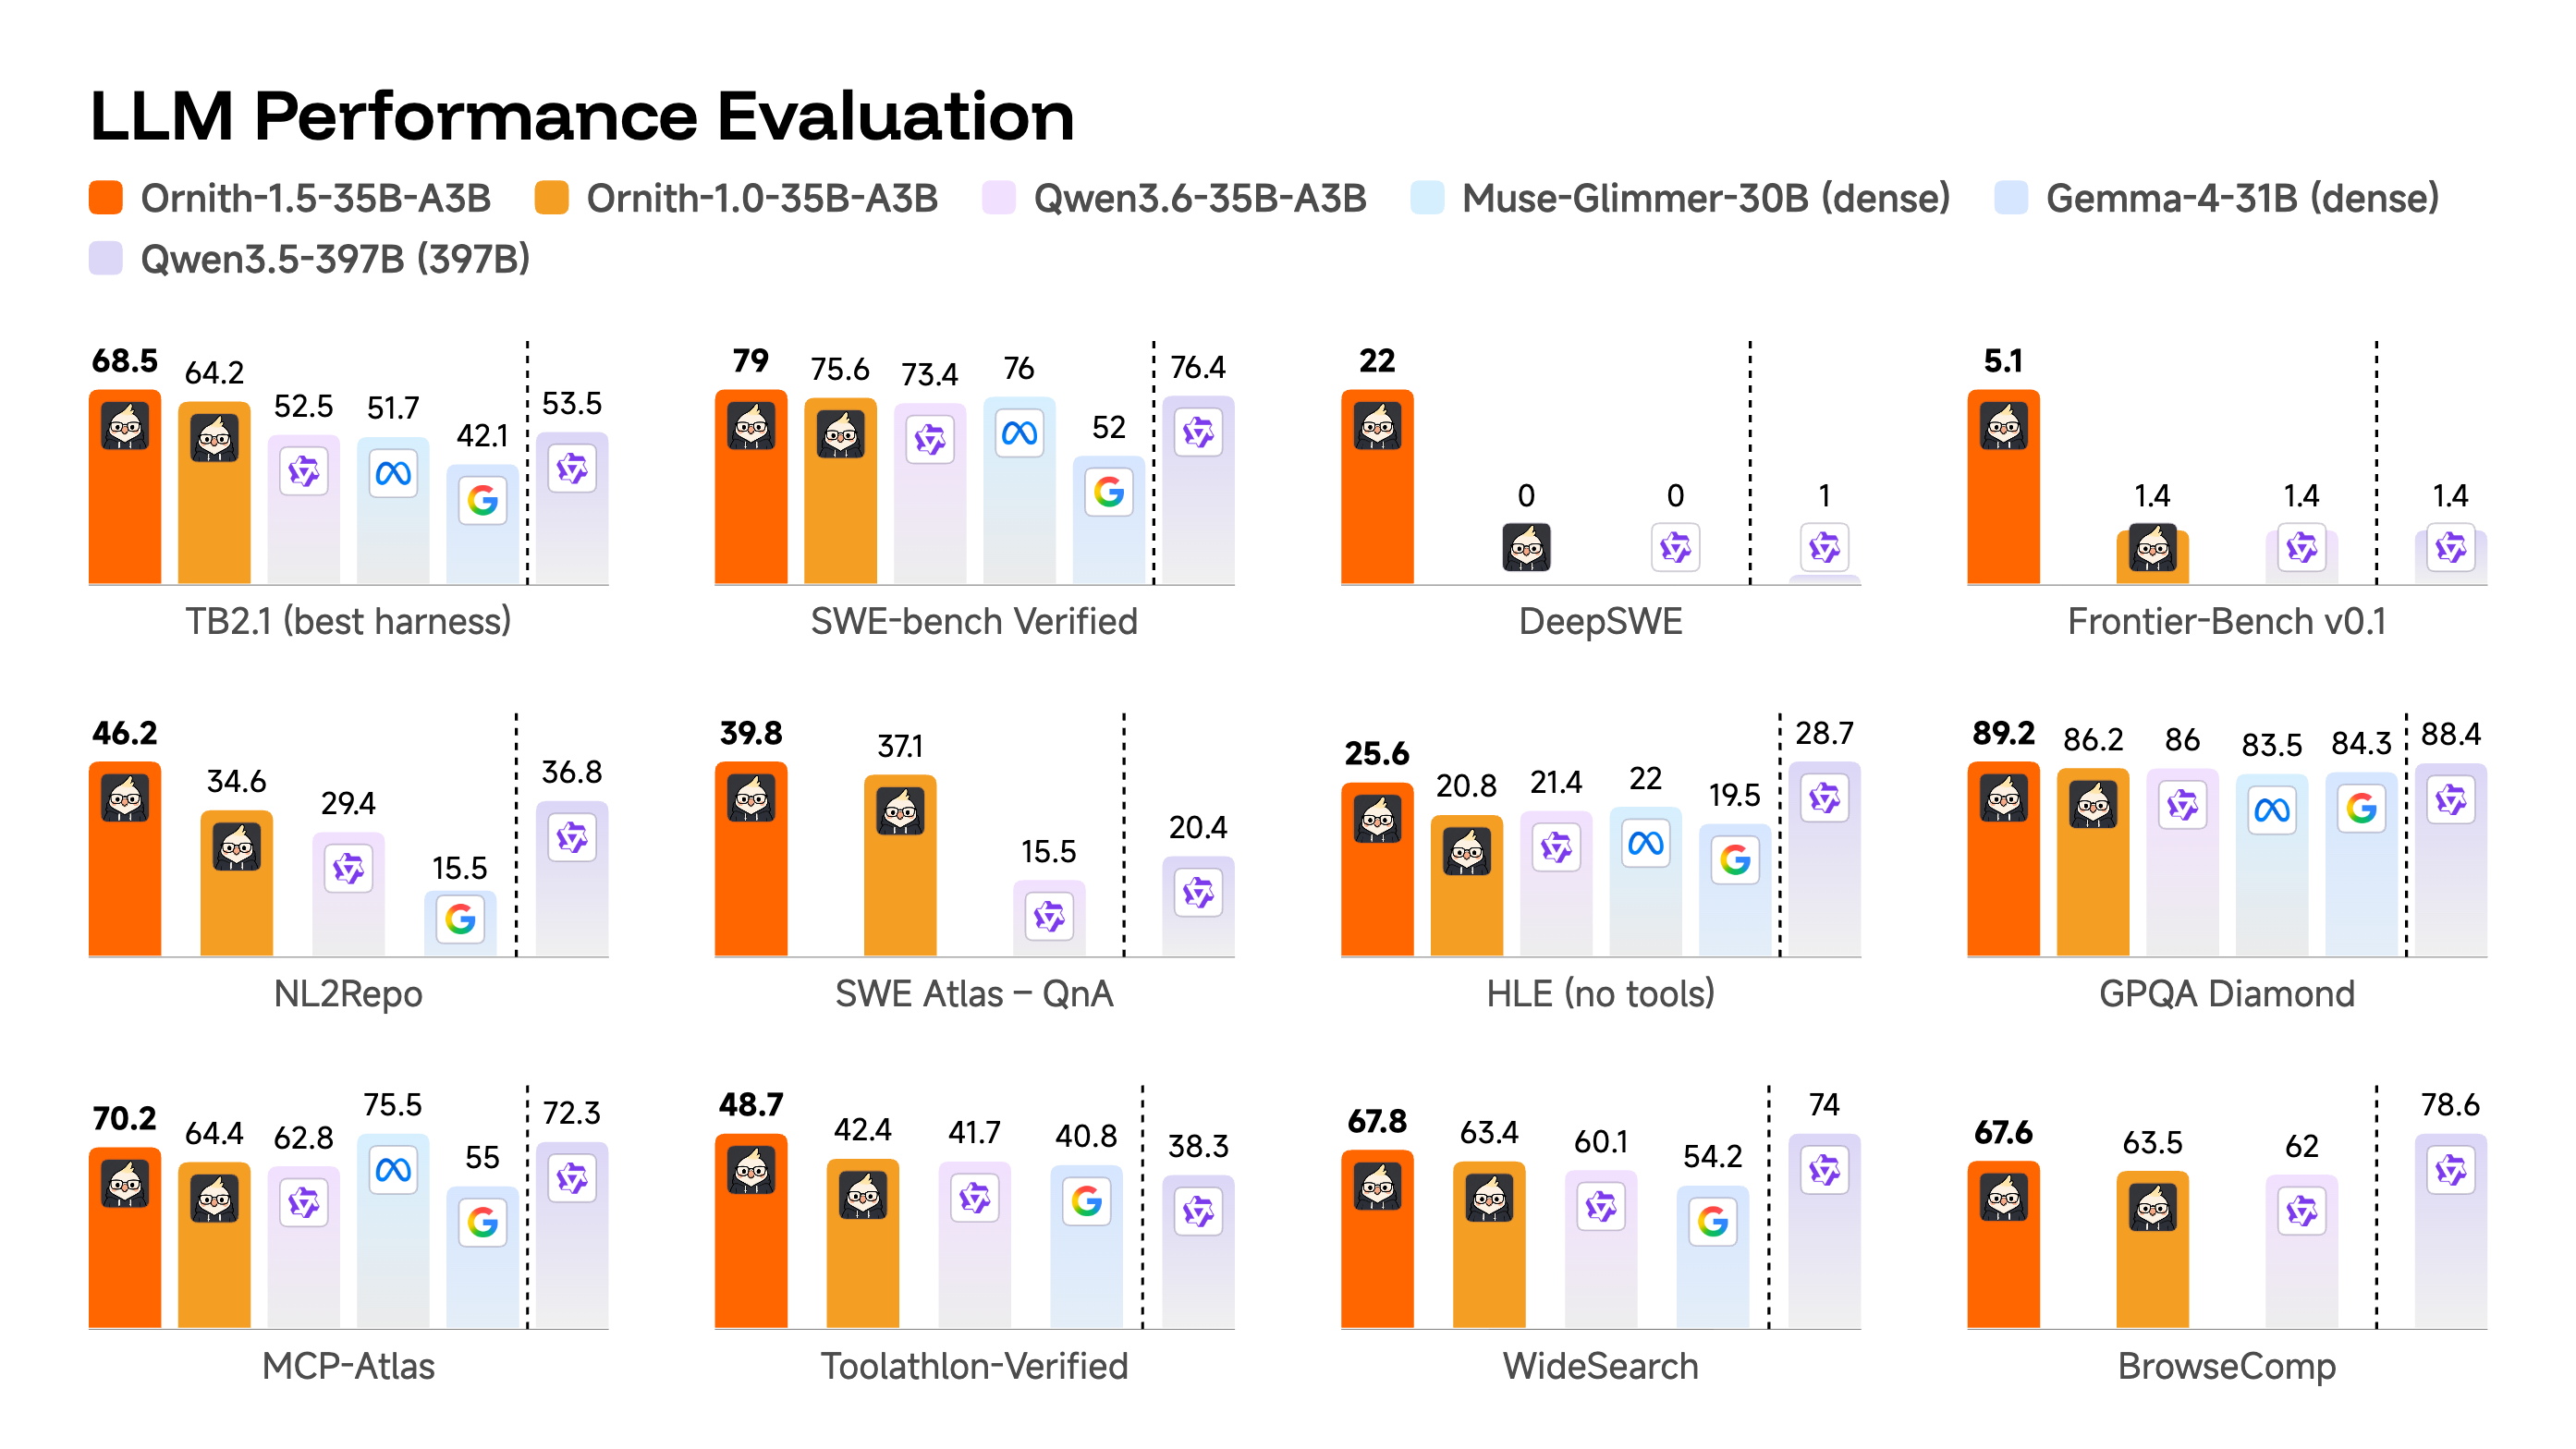
Ornith-1.5-35B-A3B adopts a Mixture of Experts (MoE) architecture with a total of 35 billion parameters. Only a subset of experts is activated for each input, keeping the number of active parameters used during actual inference at around 3 billion. This design significantly reduces inference costs while maintaining the performance of large models.
Provided in GGUF format, it can be run directly in local inference environments such as llama.cpp, Ollama, and LM Studio. Various quantization options from Q4_K_M to Q8_0 are available, allowing users to adjust memory usage according to their hardware specifications. The original BF16 files are also provided.
The chat template includes built-in tool calling and reasoning capabilities. Function call formats are defined in the system prompt, and the assistant's responses are processed to include the reasoning process. It can also be integrated directly via OpenAI-compatible APIs in server-side inference engines such as vLLM and SGLang.
Released under the MIT license, it can be freely used in commercial projects. It is suitable for local LLM deployment scenarios requiring high efficiency, particularly when running conversational AI or agent-based tasks in environments with limited GPU memory.
ornith-ai/Ornith-1.5-35B-A3B-GGUF
The original page has no description.
text-generation
This introduction was generated automatically by AI. Check the original for the author's claims and context. Copyright belongs to the original author.
Our guide explains how the AI works. Report errors, attribution issues, or removal requests via Contact.