 AI Briefing
GLM-5.3-Flash-GGUF: Run GLM-5.3-Flash Locally with 320B Parameters and 18B Active
unsloth/GLM-5.3-Flash-GGUF
About the project
This is a GGUF quantized version that enables running GLM-5.3-Flash, the first native multimodal model in the GLM-5 series, in local environments. It applies Unsloth Dynamic 3.0 quantization to improve memory efficiency while maintaining higher accuracy compared to previous methods.
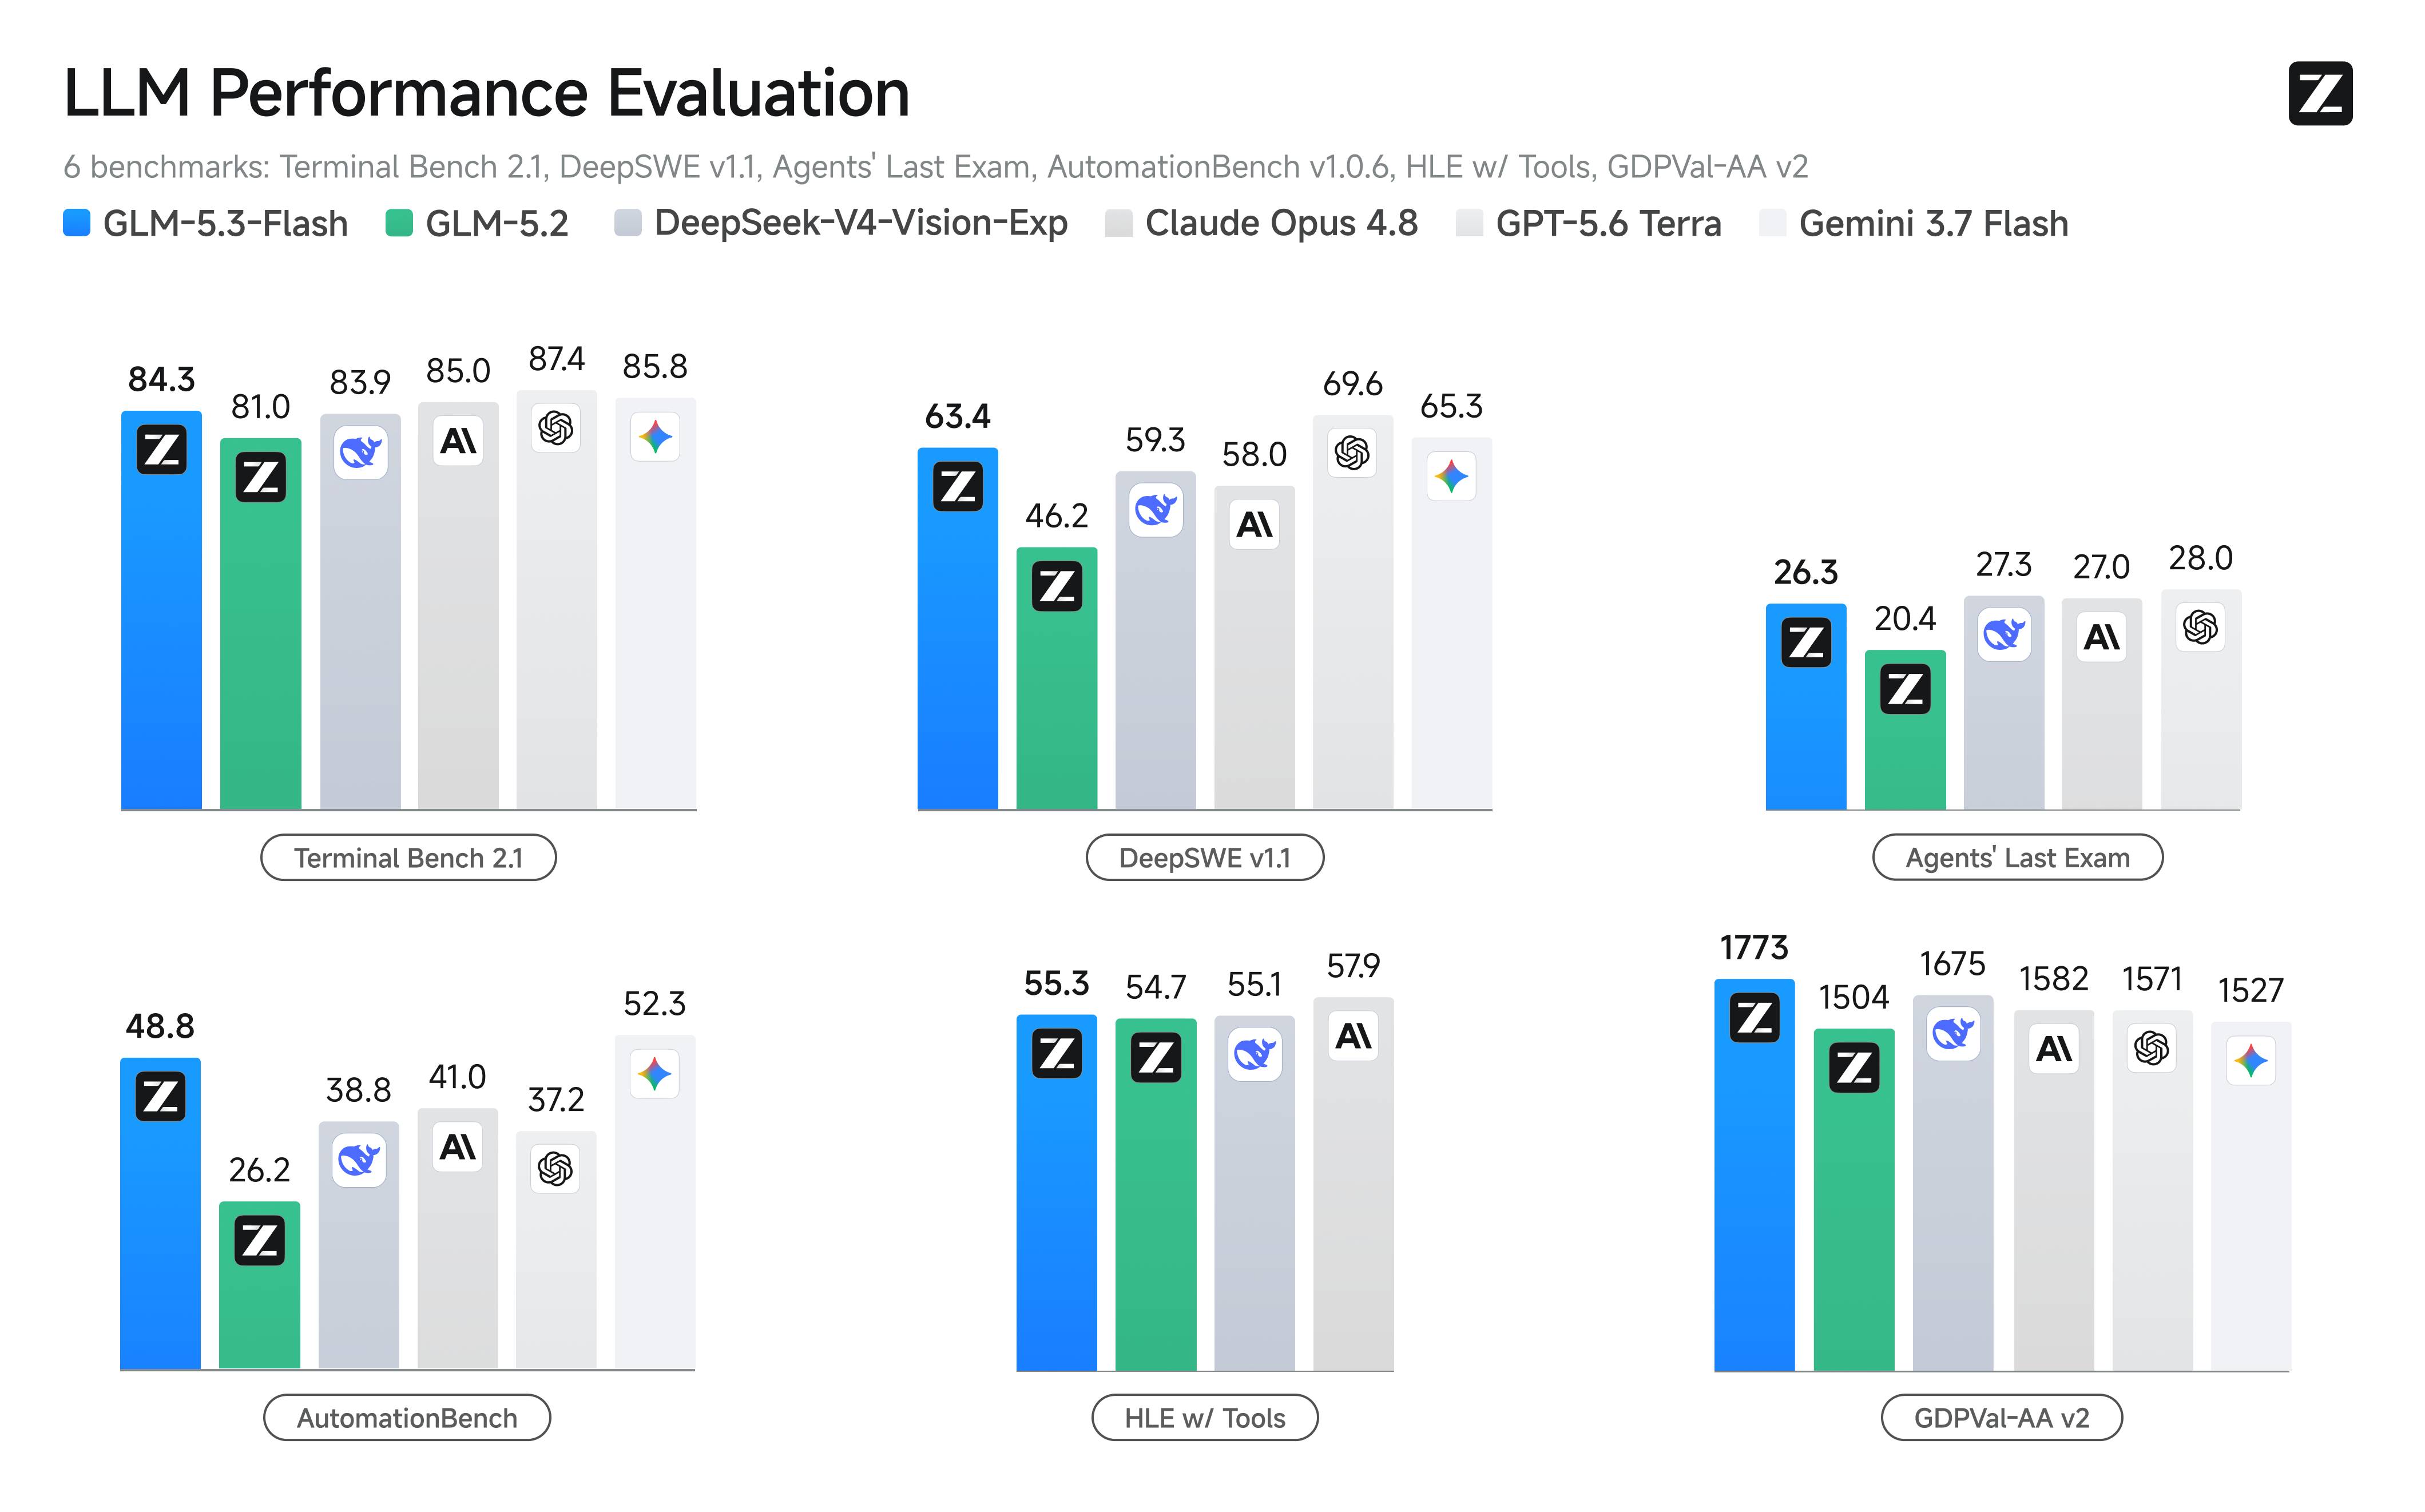
Although the total parameter count is 320B, only 18B parameters are actually activated. This delivers superior performance over GLM-5.2 while reducing costs to one-tenth of the level. On coding and agent benchmarks, it achieves results close to Claude Opus 4.8.
Unlike previous GLM series models, it adopts a hybrid architecture combining sparse attention and linear attention. This structure significantly reduces serving costs during long-context processing while preserving precise long-term memory capabilities. Additionally, it introduces Manifold-Constrained Hyper-Connections (mHC) to enhance scaling efficiency.
It is compatible with major inference frameworks such as vLLM, SGLang, and Docker Model Runner, allowing easy invocation via an OpenAI-compatible API. Distributed under the MIT license, it can be freely used in commercial projects.
unsloth/GLM-5.3-Flash-GGUF
The original page has no description.
text-generation
This introduction was generated automatically by AI. Check the original for the author's claims and context. Copyright belongs to the original author.
Our guide explains how the AI works. Report errors, attribution issues, or removal requests via Contact.