 AI Briefing
AliceAI-Foundation-80B-A3B-Base: Achieving 80B-class inference performance with 3B active parameters
yandex/AliceAI-Foundation-80B-A3B-Base
About the project
It adopts a Mixture-of-Experts structure that activates only 3 billion parameters per token out of a total of 80 billion. By combining a hybrid architecture with KDA layers, it processes long contexts of 262,000 tokens while improving computational efficiency. Through full pre-training, it possesses complex reasoning and tool-use capabilities.
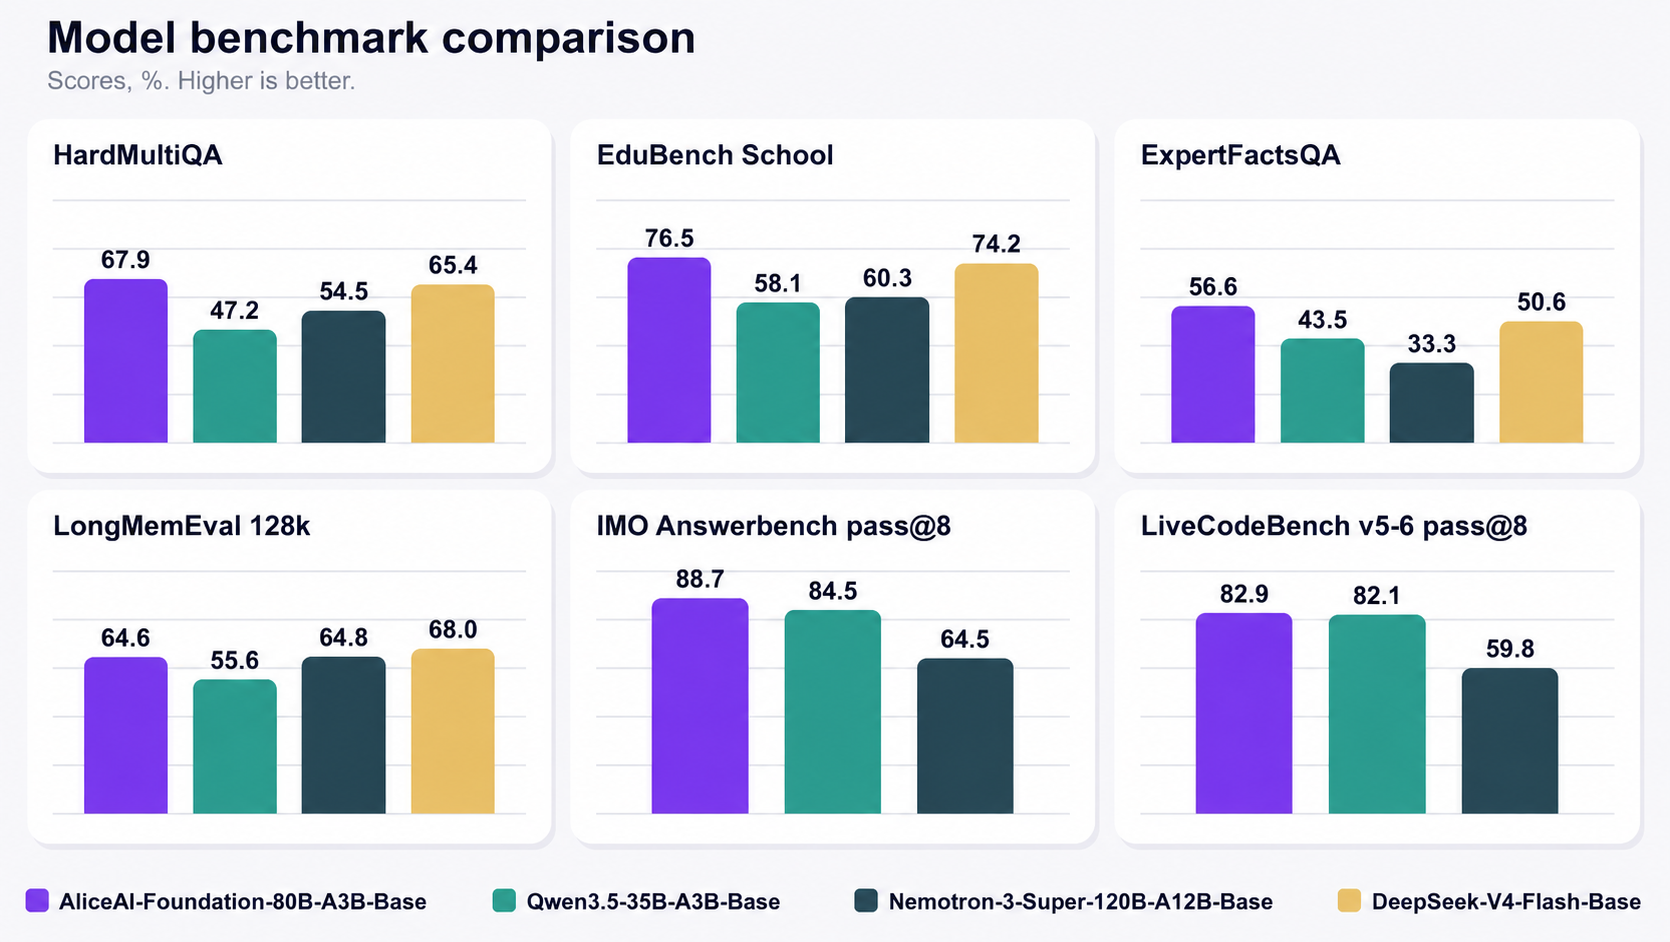
It demonstrates overwhelming performance on Russian factual knowledge benchmarks. It scored 86.5 on WikiWebFacts and 67.9 on HardMultiQA, significantly outperforming competing models such as Qwen3.5 and GLM-4.5-Air. Its mathematical and coding abilities are also top-tier, achieving a high accuracy of 96.7 on AIME 2026 problems.
It can be deployed via the vLLM and Transformers libraries. The flash-linear-attention library is required for GPU environments. Released under the Apache 2.0 license, it is available for commercial use and is suitable for fine-tuning based on Russian-specific datasets.
yandex/AliceAI-Foundation-80B-A3B-Base
The original page has no description.
text-generation
This introduction was generated automatically by AI. Check the original for the author's claims and context. Copyright belongs to the original author.
Our guide explains how the AI works. Report errors, attribution issues, or removal requests via Contact.