 AI Briefing
Qwen3.8-27B-DFlash2: DFlash 2 Boosts Qwen3.8-27B Inference Speed by 3.4x
z-lab/Qwen3.8-27B-DFlash2
About the project
DFlash 2 is a draft model designed to accelerate the inference speed of the Qwen3.8-27B model. It does not operate independently but serves as an auxiliary component for speculative decoding within inference servers such as SGLang or vLLM. It pre-generates tokens for the target model to verify.
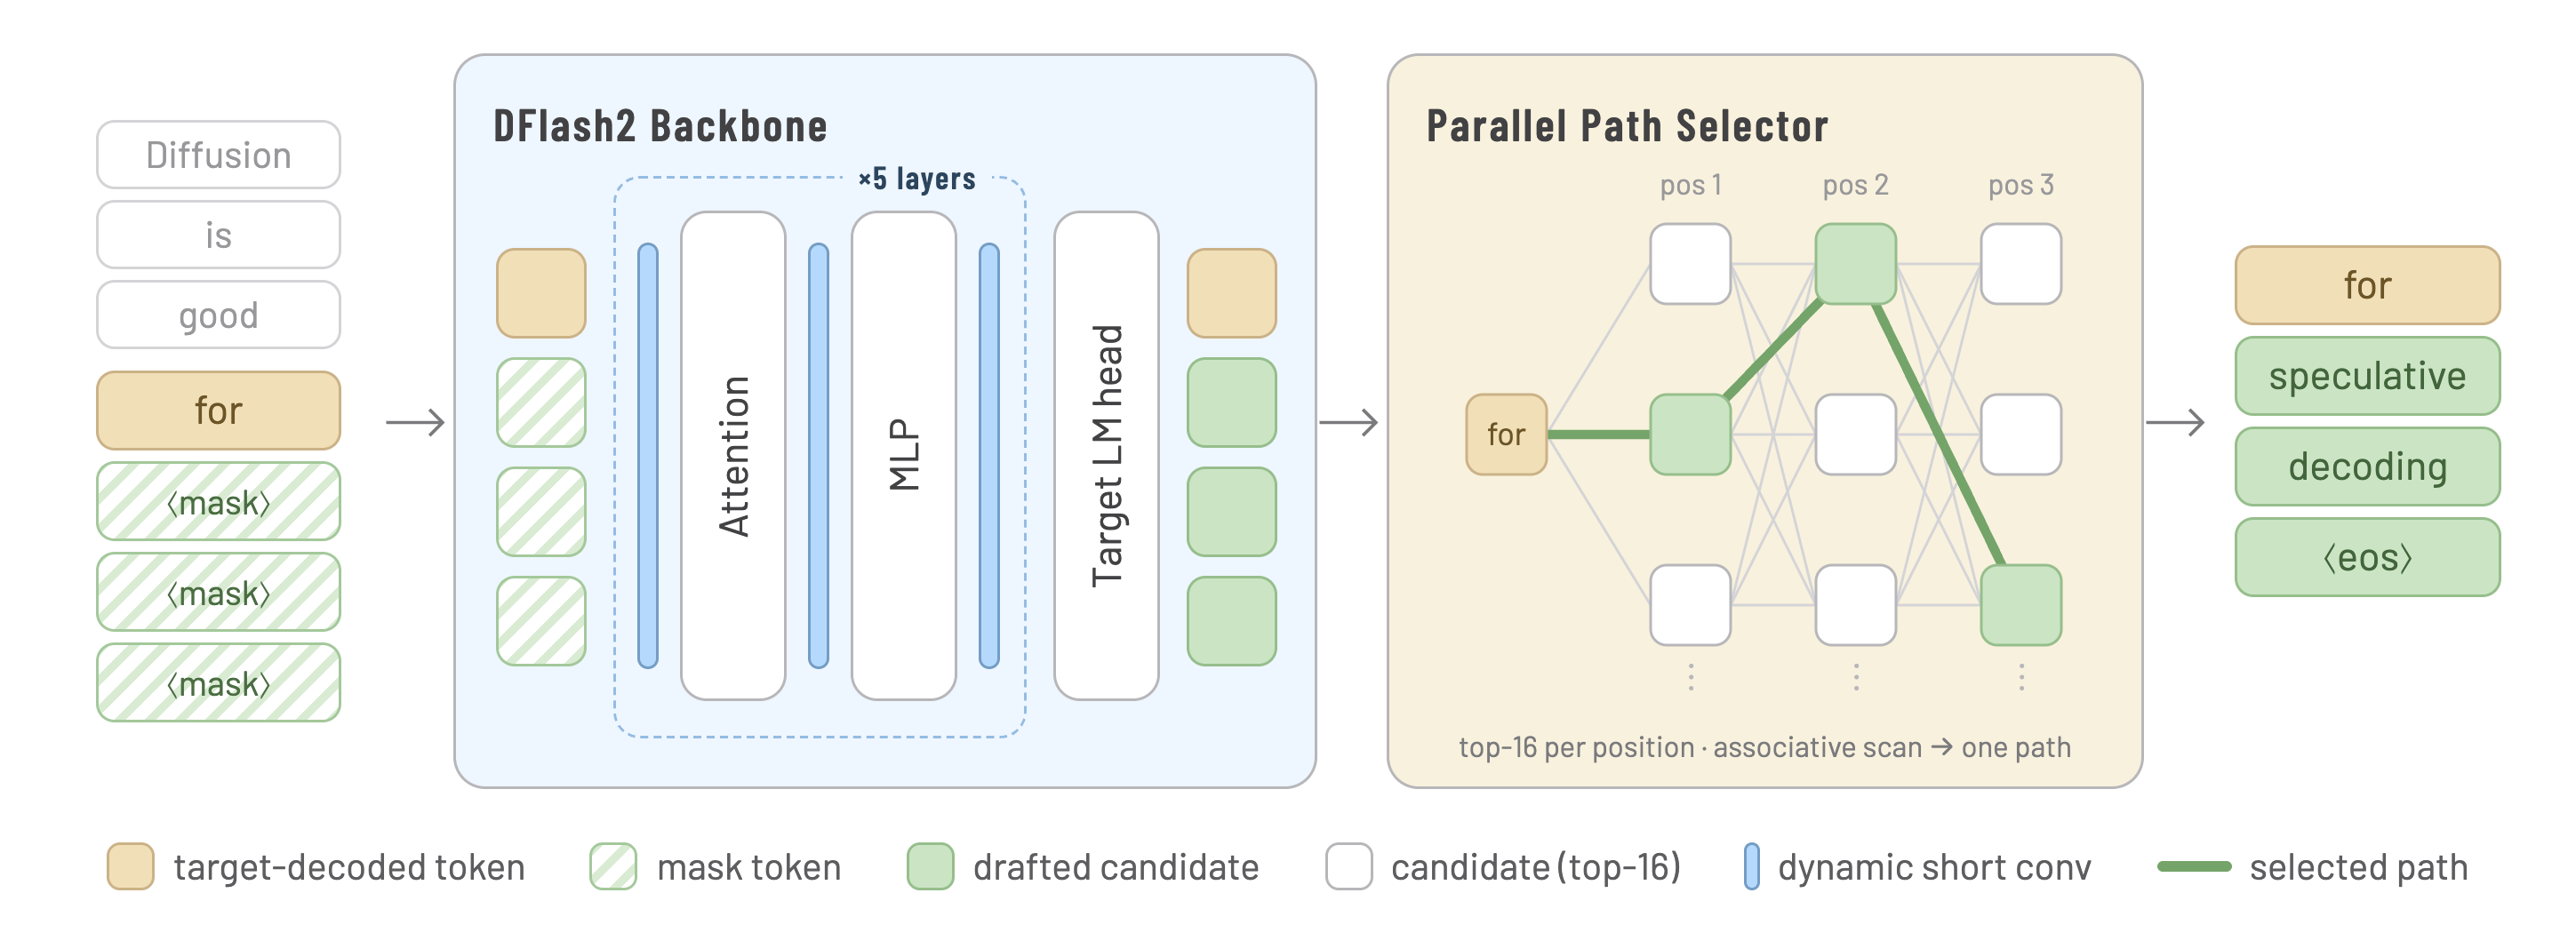
As a block diffusion-based drafter, it predicts entire token blocks in a single pass. By applying two-tab dynamic synthesis to the backbone, it prevents the degradation of draft quality towards the latter part of the block. This is a lossless decoding method where greedy outputs match the target model exactly, and the distribution is preserved during sampling.
Benchmarks conducted on a single NVIDIA H200 GPU using SGLang show a throughput improvement of up to 3.43x compared to autoregressive decoding. These figures are higher than those achieved by Qwen3.8's built-in MTP or the community DSpark drafter. Consistent performance improvements were observed across various benchmarks, including GSM8K, MATH-500, and HumanEval.
Released under the Apache-2.0 license, it is a BF16 model with 2B parameters. It can be applied in environments serving Qwen3.8-27B to reduce response latency. It can be used immediately by simply specifying the draft model path in existing inference server configurations.
z-lab/Qwen3.8-27B-DFlash2
The original page has no description.
text-generation
This introduction was generated automatically by AI. Check the original for the author's claims and context. Copyright belongs to the original author.
Our guide explains how the AI works. Report errors, attribution issues, or removal requests via Contact.