 AI Briefing
Pickheadroom: 95% JSON Data Compression, Perceived LLM Response Speedup
headroomlabs-ai/headroom
About the project
A context compression layer that reduces the token volume AI agents send to LLMs. It compresses all data agents read—including tool outputs, logs, RAG chunks, files, and conversation history—before it reaches the LLM. The core goal is to significantly reduce input tokens while maintaining identical responses.
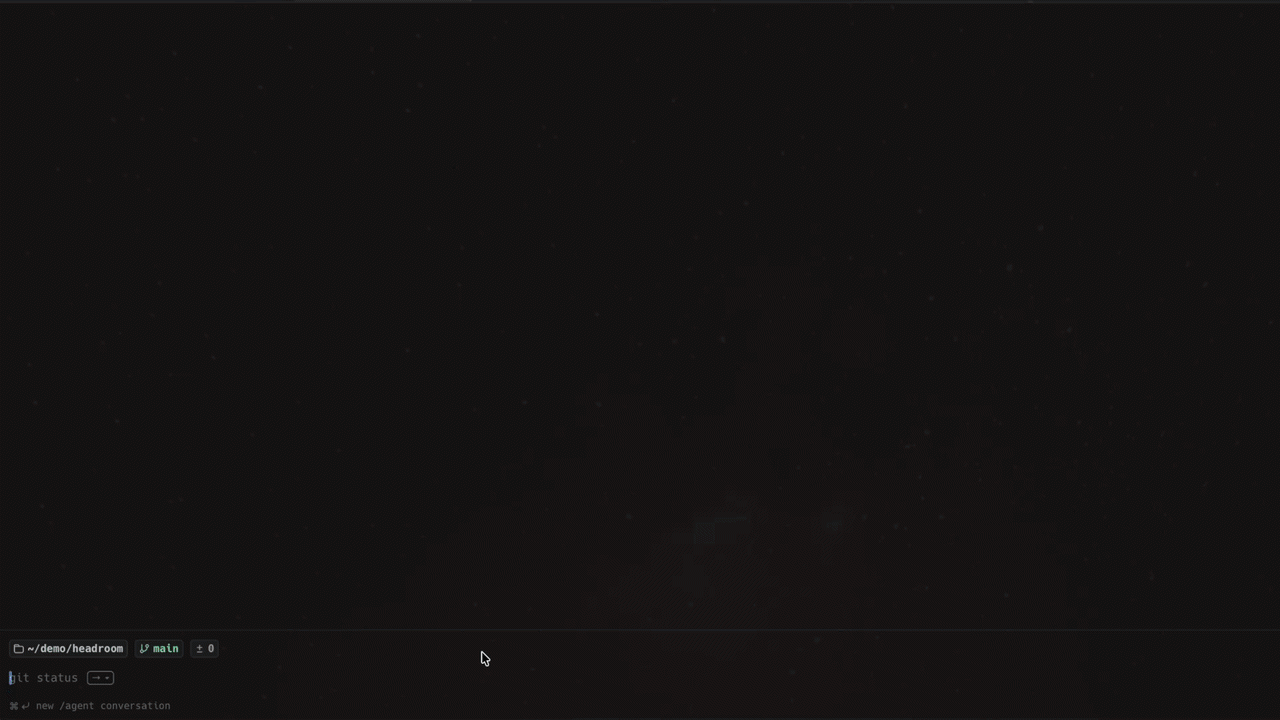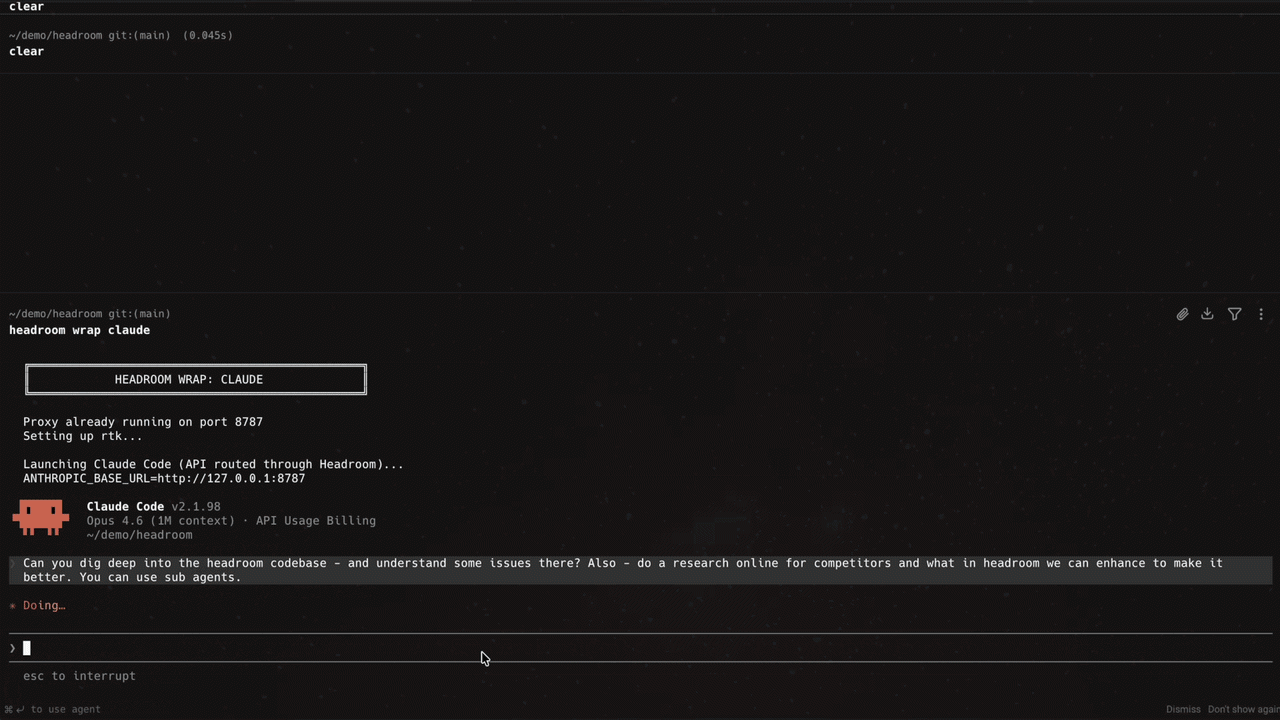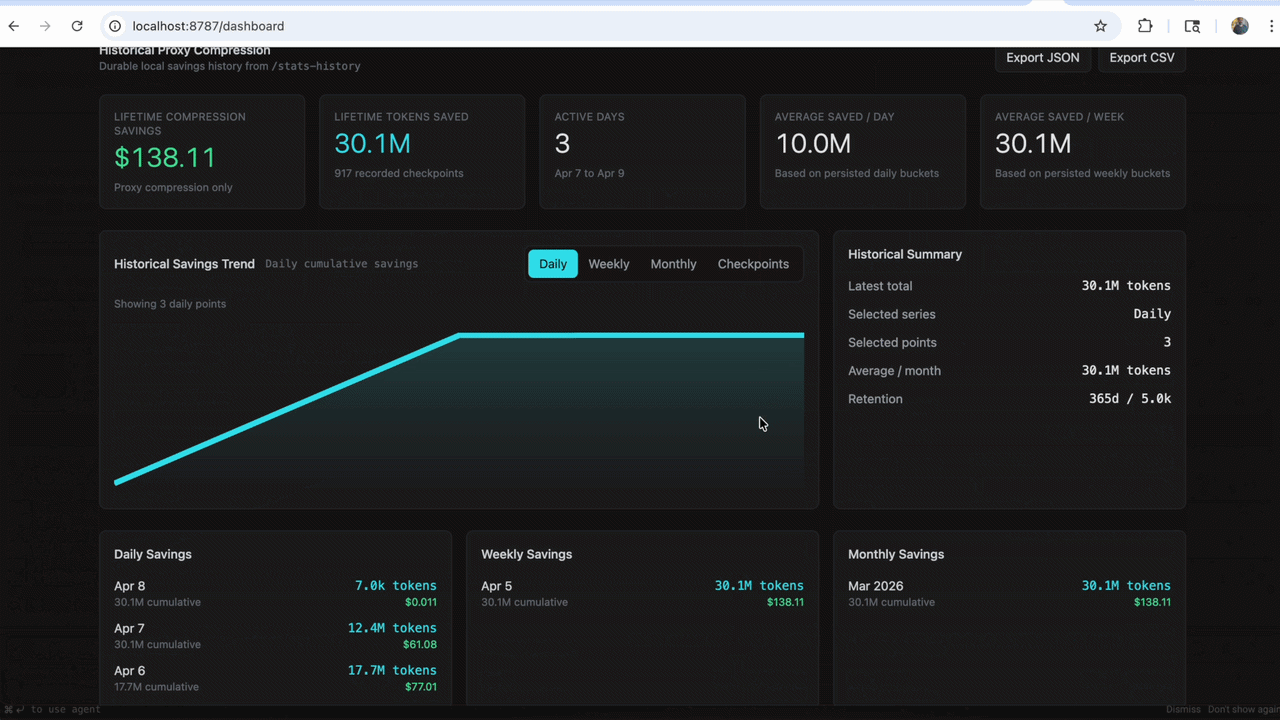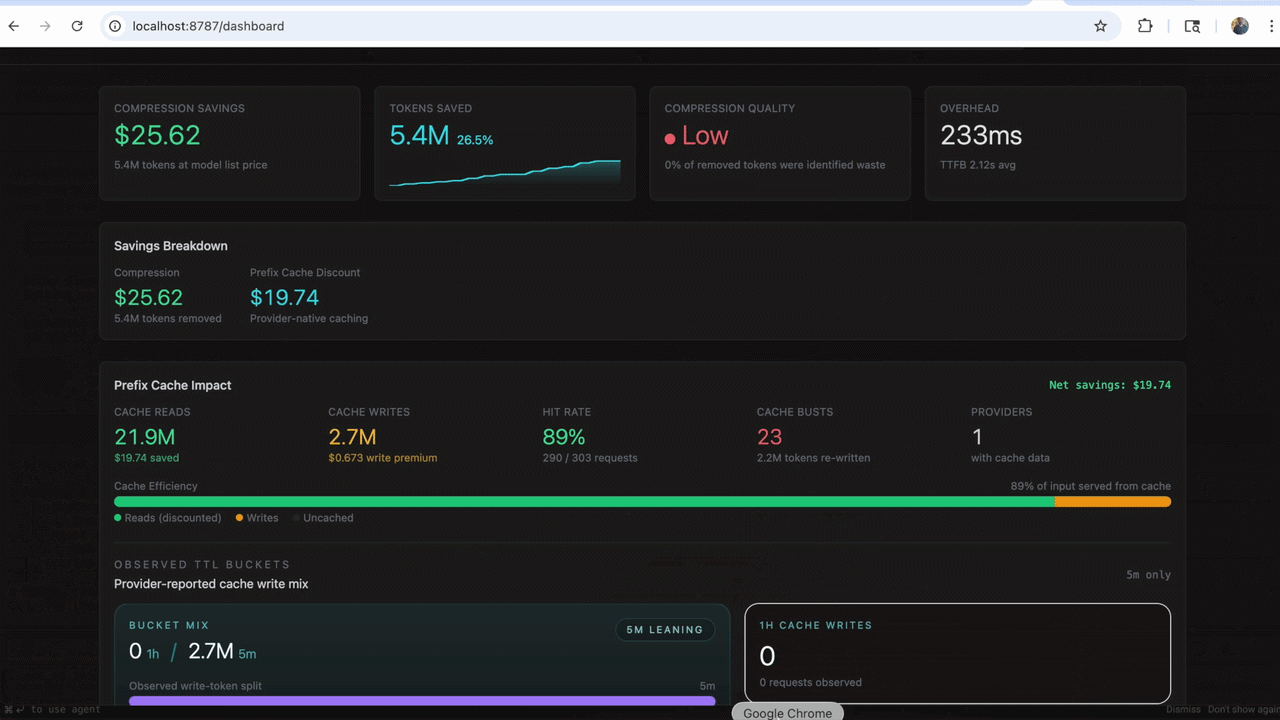
It delivers token savings of 60–95% for JSON data and 15–20% for coding agent workloads. Cases of up to 92% token reduction have been confirmed in real-world tasks such as code search and SRE incident debugging. Integration is possible via various methods, including Python and TypeScript libraries, proxies, MCP servers, and agent wrapping.
It adopts reversible compression, caching originals locally for retrieval when needed, rather than simple compression. It shares memory across multiple agents like Claude, Codex, Gemini, and Grok, eliminating duplicates. It also includes a learning feature that analyzes failed sessions and automatically logs corrections.
It optimizes not only input tokens but also output tokens generated by the model. It removes unnecessary preambles and code re-quoting, and lowers reasoning effort for routine steps. With a local-first design, data never leaves the local environment, and it is released under the Apache-2.0 license.
headroomlabs-ai/headroom
Compress tool outputs, logs, files, and RAG chunks before they reach the LLM. 20% fewer tokens for coding agents, 60-95% fewer tokens for JSON, same answers. Library, proxy, MCP server.
Python
This introduction was generated automatically by AI. Check the original for the author's claims and context. Copyright belongs to the original author.
Our guide explains how the AI works. Report errors, attribution issues, or removal requests via Contact.