 AI Briefing
modlens: Give Text-Only LLMs Vision with a Simple Image Paste
liustack/modlens
About the project
Text-only models like DeepSeek and GLM cannot directly recognize images. ModLens is a plugin engine that grants vision capabilities to these models, requiring only that you paste an image into the chat window. Unlike traditional methods that require saving files or passing paths, image paths are automatically generated and processed immediately.
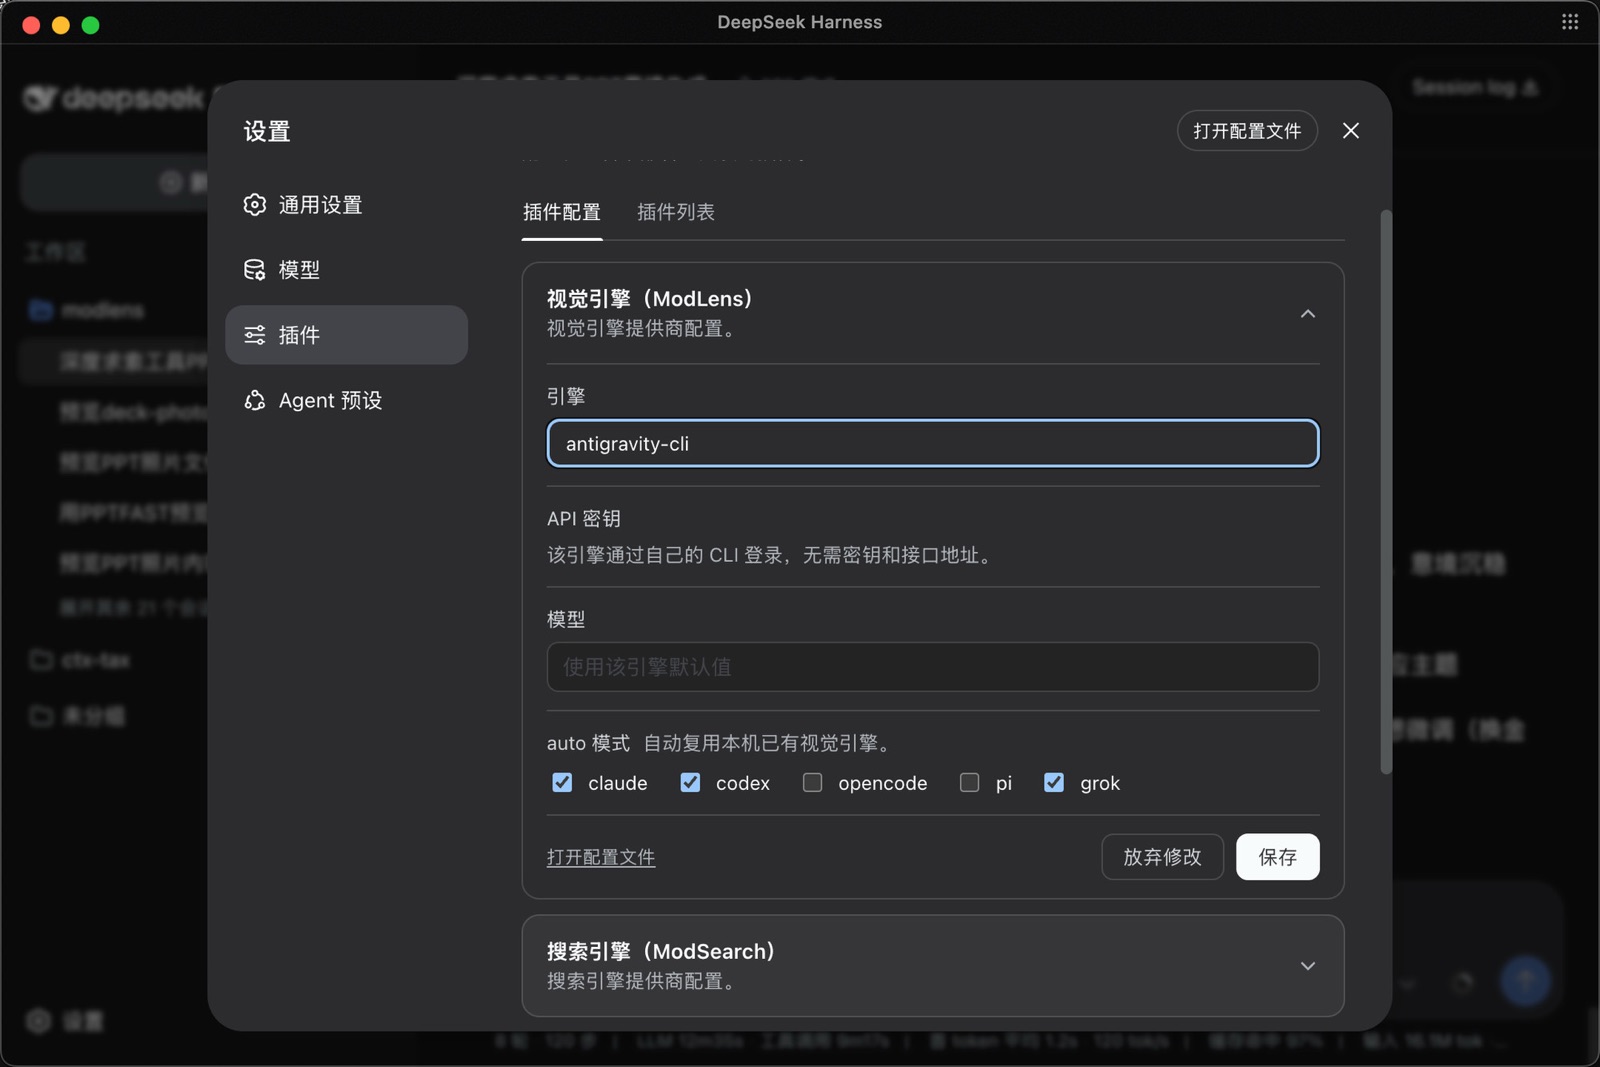
Image recognition goes beyond simple content summarization, providing structured evidence such as full transcriptions, layout regions based on reading order, and lists of entities and relationships. The model generates answers based on what it actually read, rather than guessing. There is no need to re-paste an image when asking follow-up questions about it.
To avoid dependency on specific vision services, it supports 10 sources. This includes 6 built-in providers such as Gemini, OpenAI, and Anthropic, as well as 4 local agent CLIs: Claude Code, Codex, OpenCode, and Pi. Credentials from already logged-in CLIs can be reused, and every reuse read is clearly logged to show who consumed the quota.
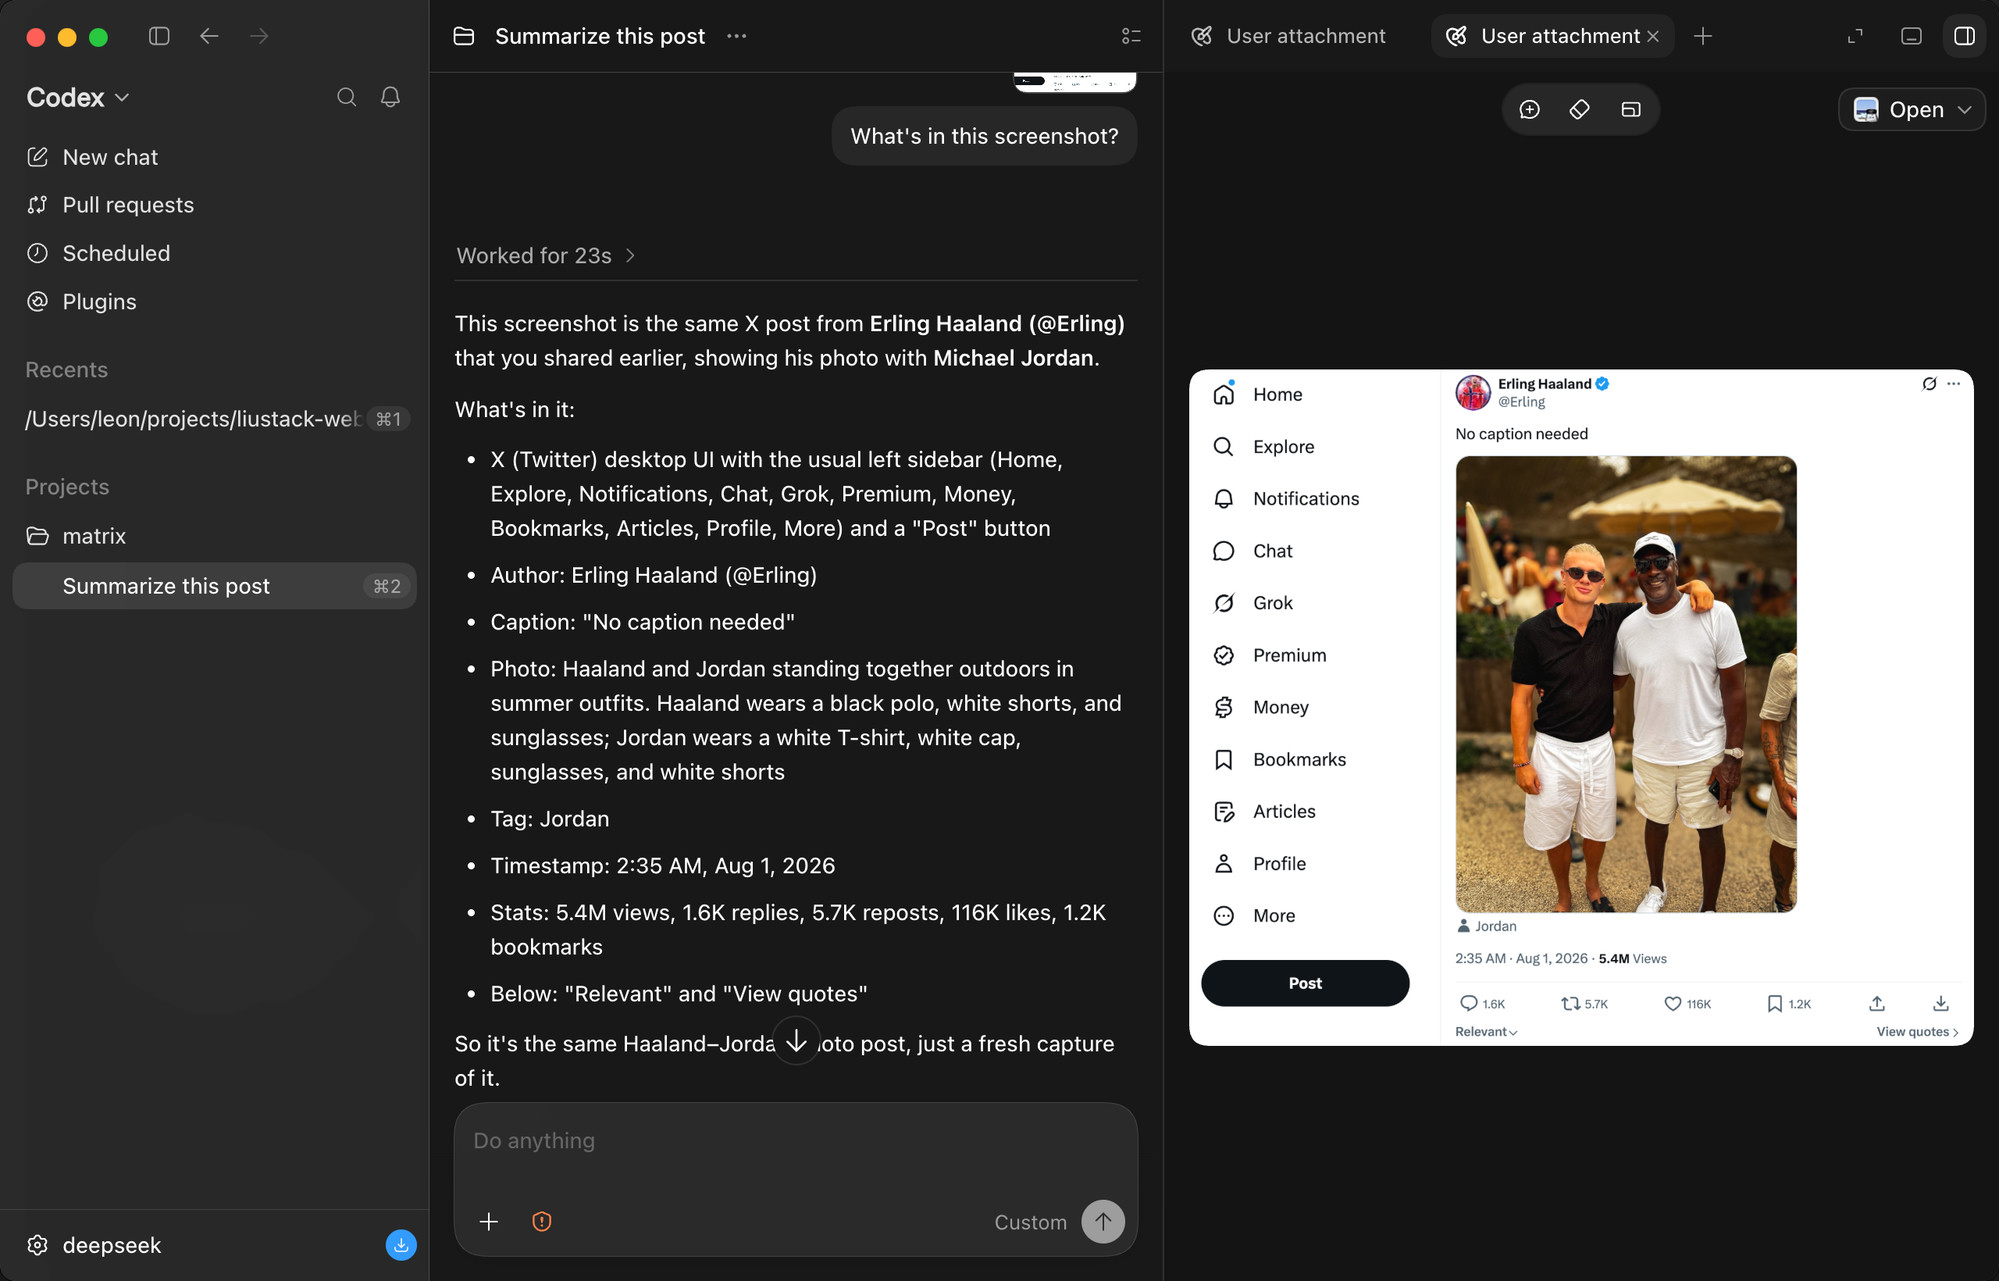
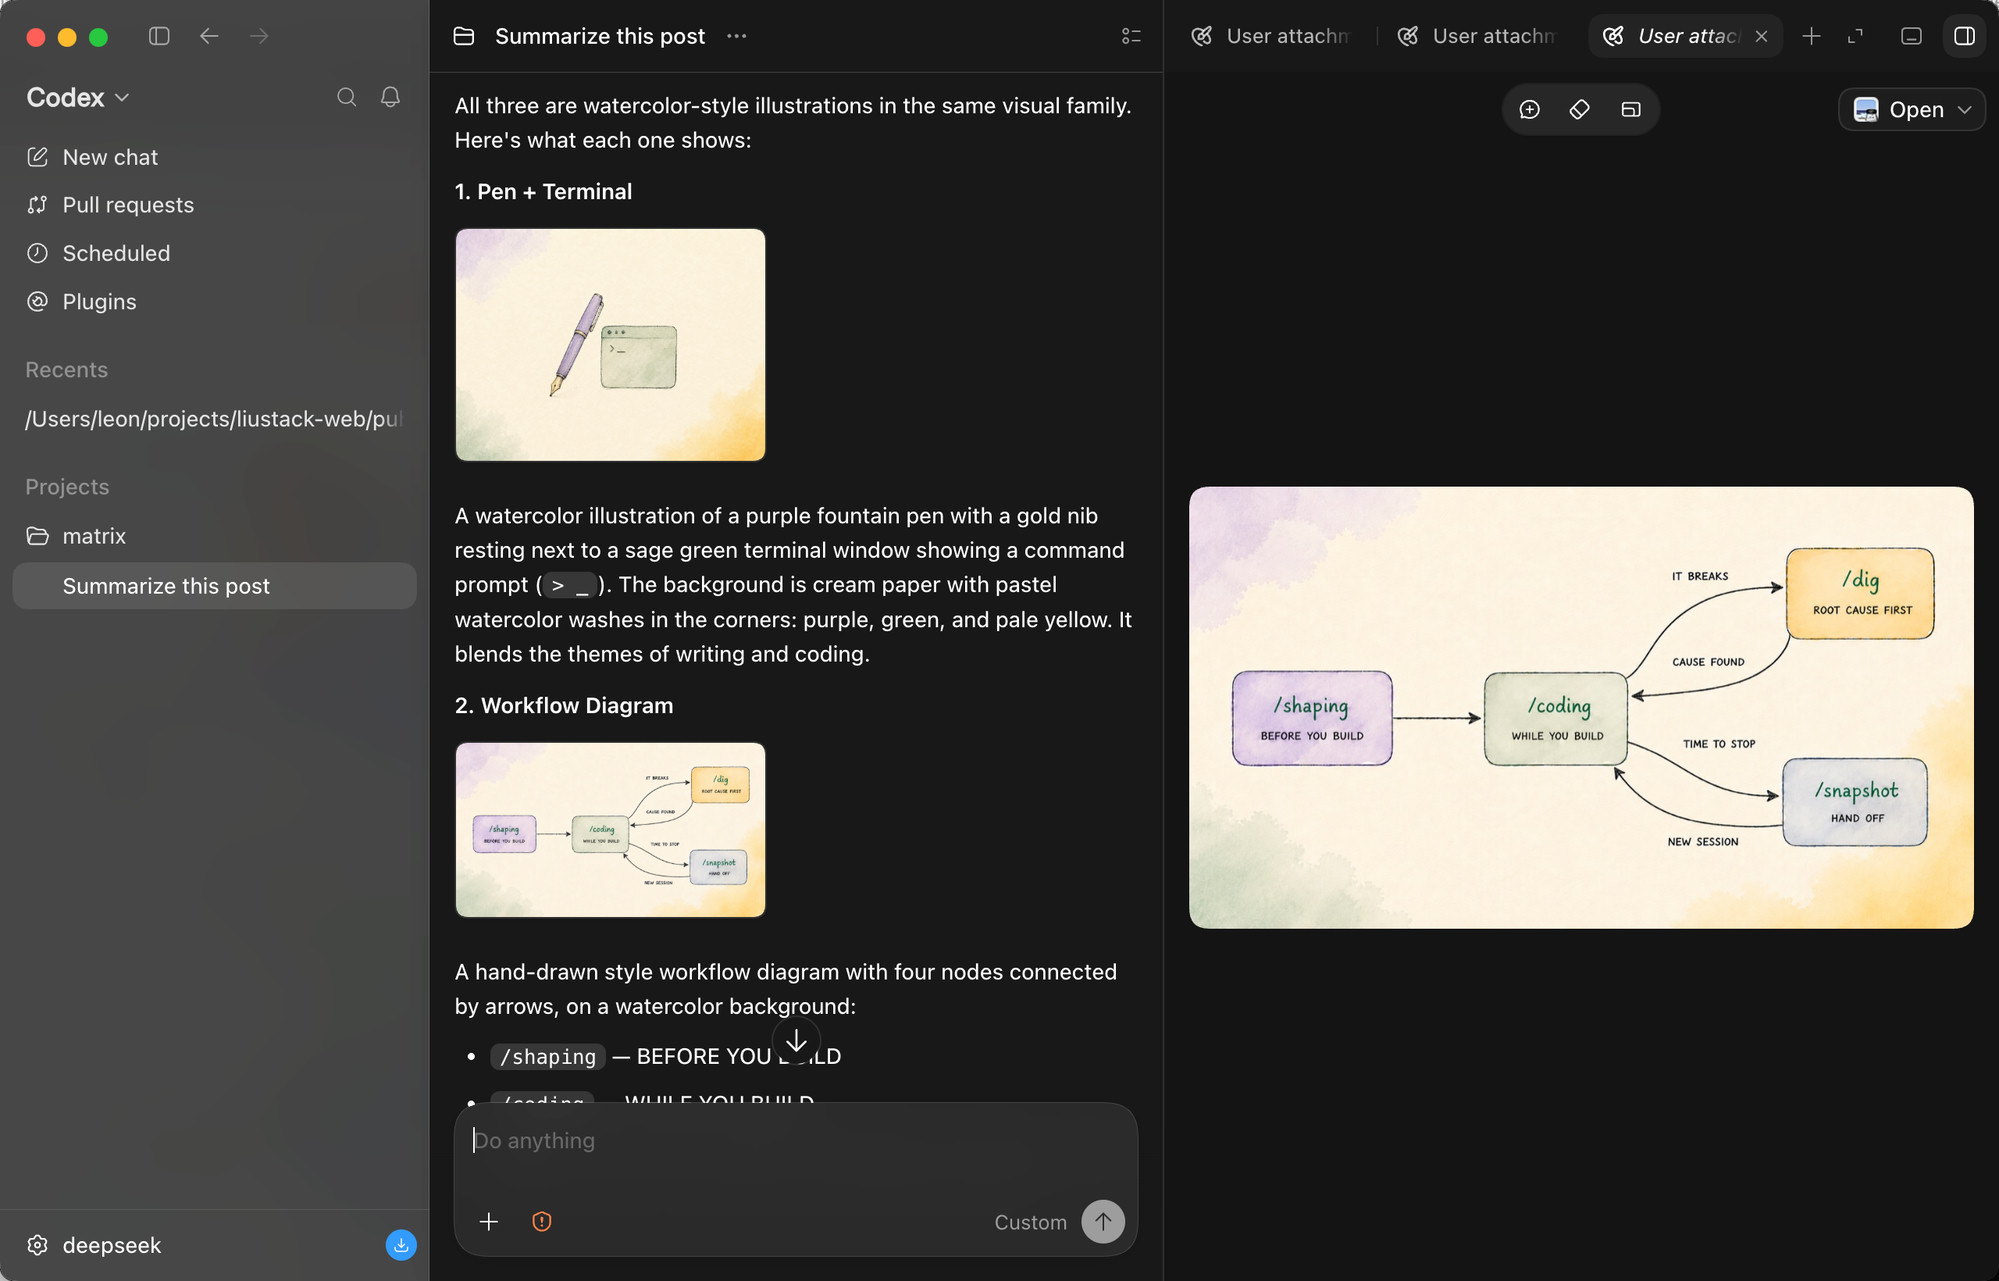
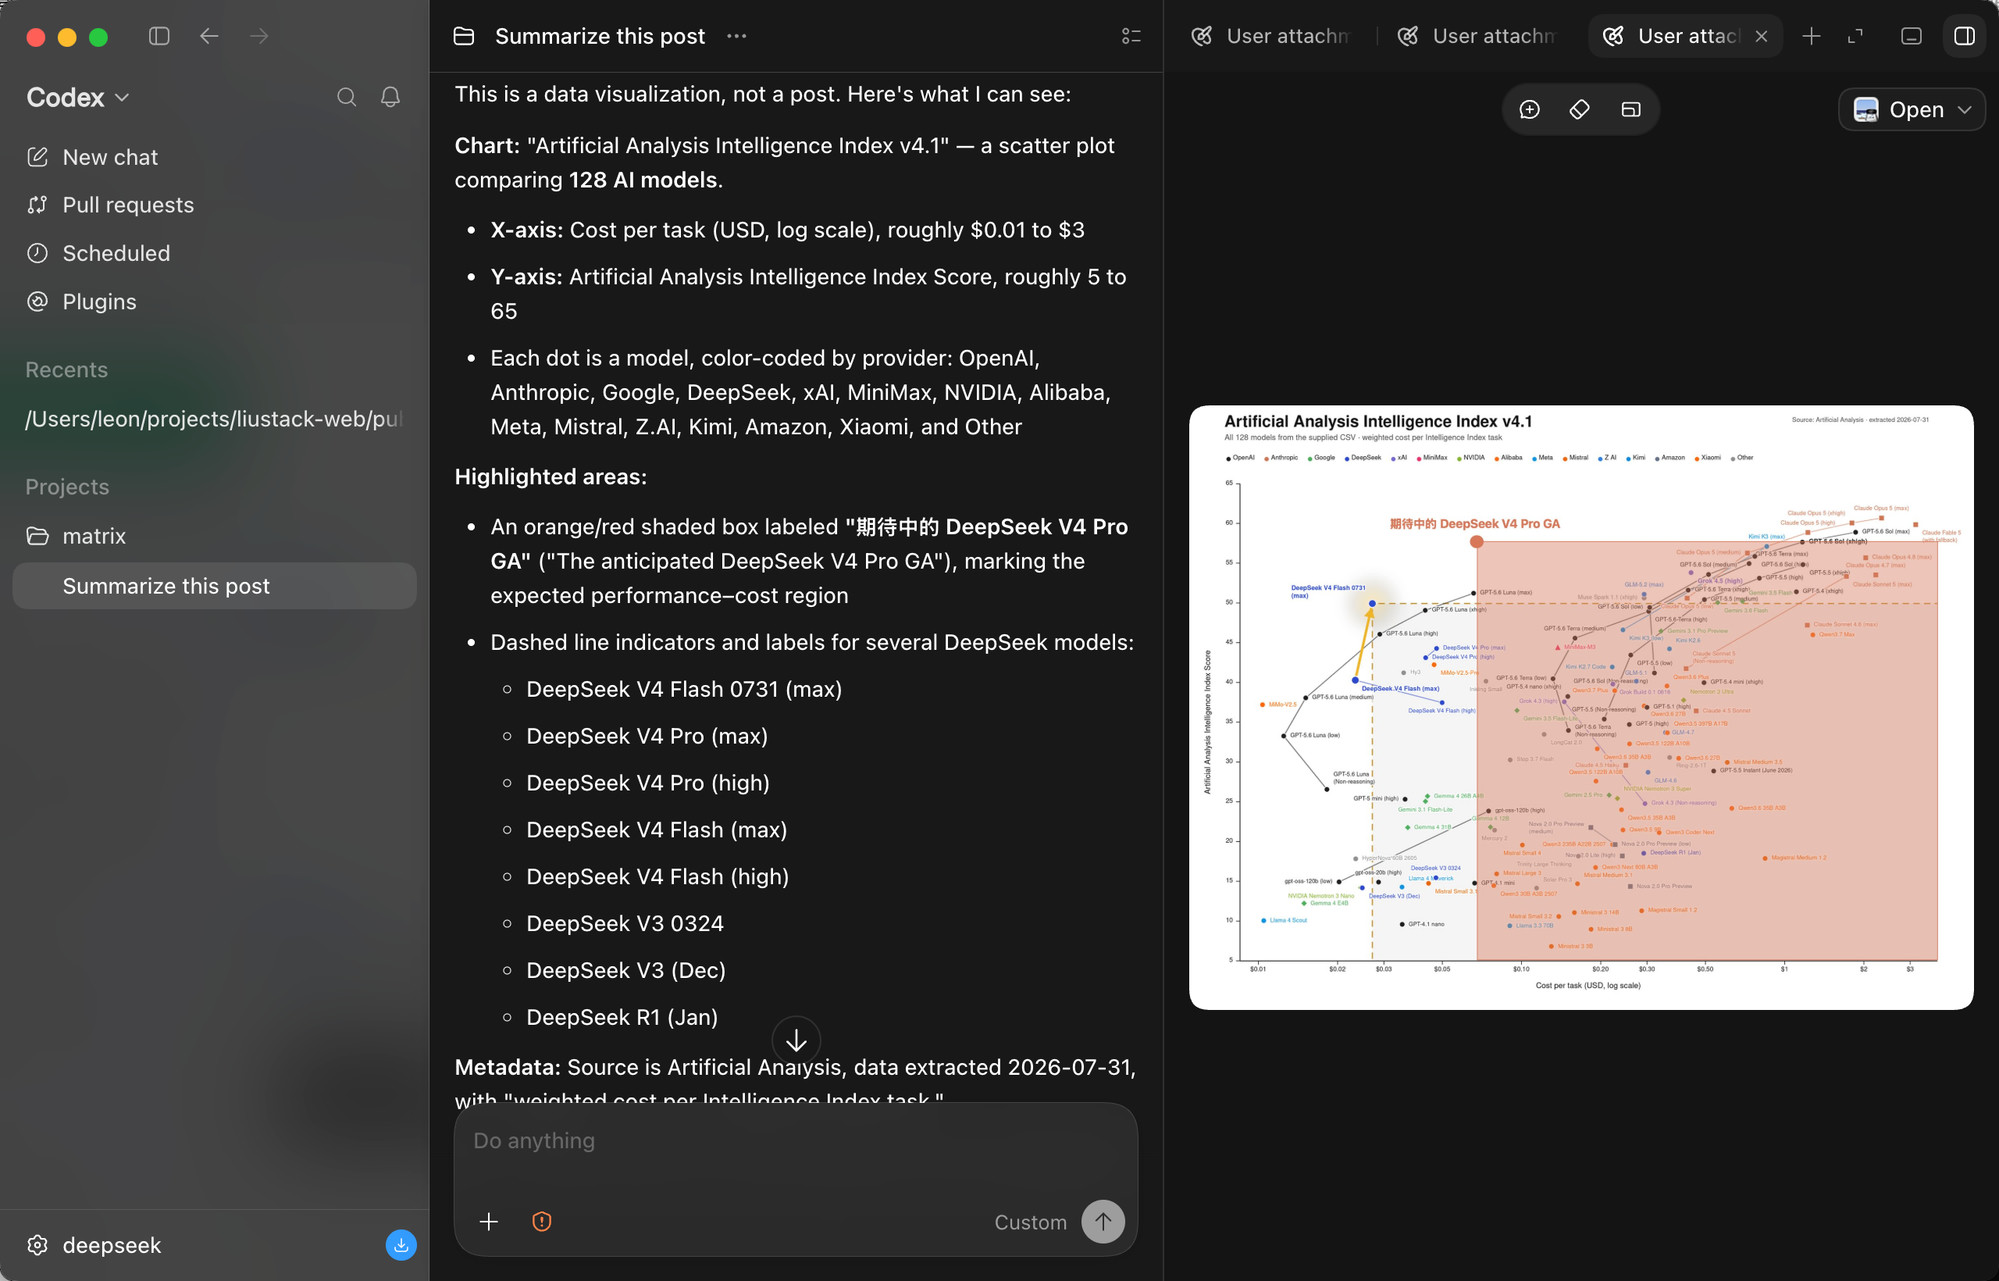
Installation and removal are simple and do not affect existing agent configurations. It operates as a single folder in Skill Harness and as a single plugin in dsh; deleting the folder restores the original state. Verified across various environments including Claude Code, Codex, Pi, and OpenCode, it is useful for developers using text-only models to perform image-based tasks.
liustack/modlens
The first vision plugin for DeepSeek Harness, and the vision bridge for every text-only coding agent. Paste an image, get structured JSON evidence (OCR, layout, semantics). | 全网最强 DeepSeek Harness 外挂视觉插件,为 DeepSeek、GLM 等纯文本模型外挂视觉能力,粘贴图片即得结构化 JSON 证据(OCR、版面、语义)。
TypeScript
This introduction was generated automatically by AI. Check the original for the author's claims and context. Copyright belongs to the original author.
Our guide explains how the AI works. Report errors, attribution issues, or removal requests via Contact.