 AI Briefing
laya-mlx: Local classification inference in 7ms on Apple Silicon
mizorewww/laya-mlx
About the project
An inference engine that makes structured decisions such as multiple-choice classification or scoring without LLM token generation. It utilizes a bidirectional encoder to process the input state and question in a single forward pass, eliminating the latency and uncertainty associated with existing generative models.
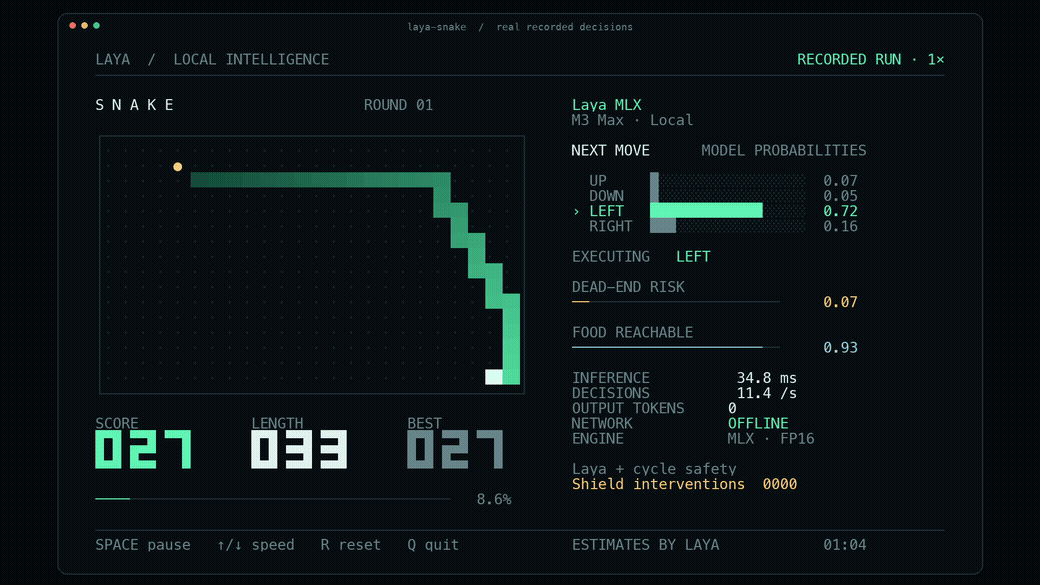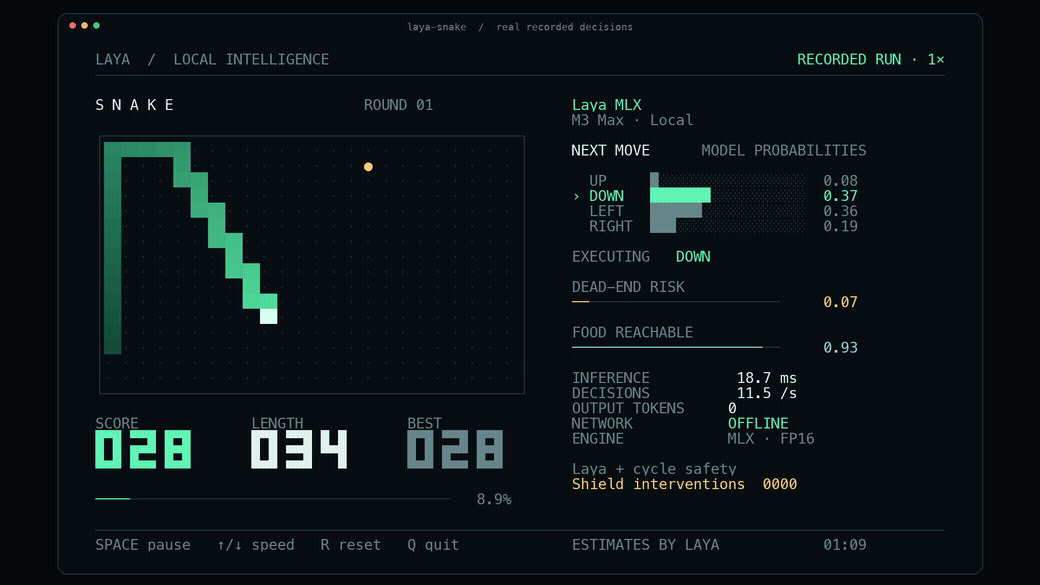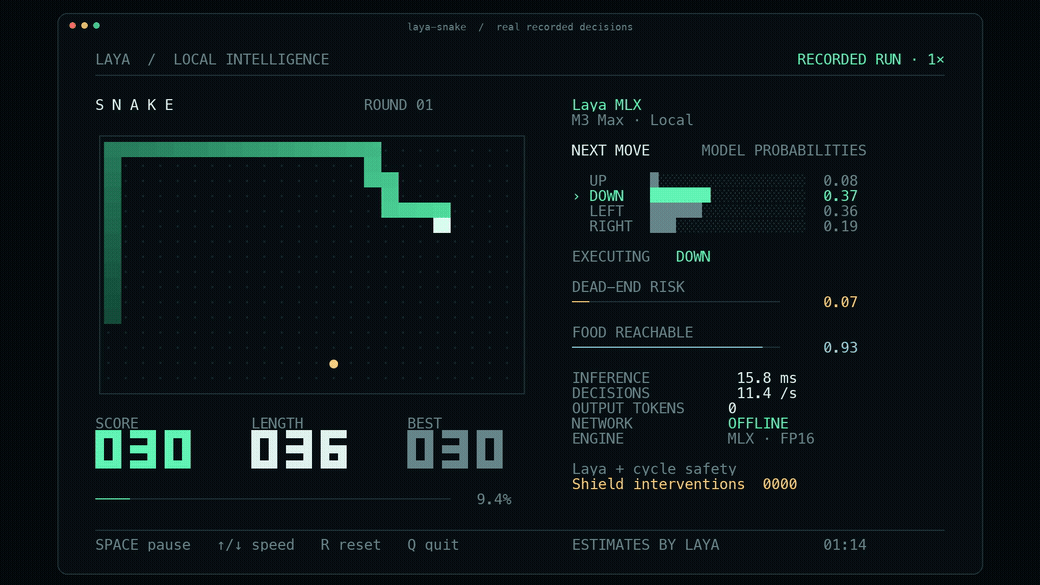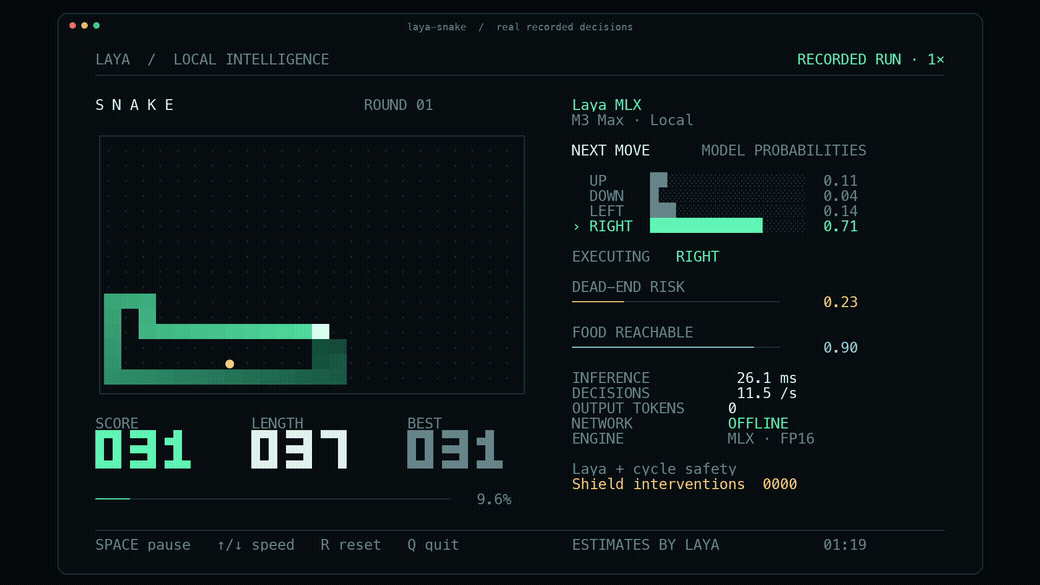
On M3 Max, it achieves ultra-low latency with a median of 13.4ms for English question processing and 7.4ms for the multilingual model. It runs natively on MLX without PyTorch or Transformers runtimes, providing immediate local responses without cloud API calls.
It supports three task types: choice (selecting one option), score (rubric scoring), and noul (returning true/false probabilities). Through router functionality, it automatically branches between English-only and multilingual models based on the input language to deliver optimal performance.
Suitable for agent workflows requiring real-time classification or applications requiring lightweight inference in offline environments. It is an independent port optimized for Apple Silicon hardware while maintaining the original weights from Convai Innovations.
mizorewww/laya-mlx
Native MLX runtime for Laya typed decision models — 7–14 ms short decisions on M3 Max. No text generation, PyTorch, or cloud API.
Python
This introduction was generated automatically by AI. Check the original for the author's claims and context. Copyright belongs to the original author.
Our guide explains how the AI works. Report errors, attribution issues, or removal requests via Contact.