 AI Briefing
PickTeleOCR: 90s range recognition rate on real-world documents, ranked 2nd among models under 500B
XingChen-AGI/TeleOCR
About the project
Converts text and layout from scanned or photographed documents into digital data. Built on the Qwen2.5-VL architecture, TeleOCR goes beyond simple character recognition to extract complex tables and charts in a structured format.
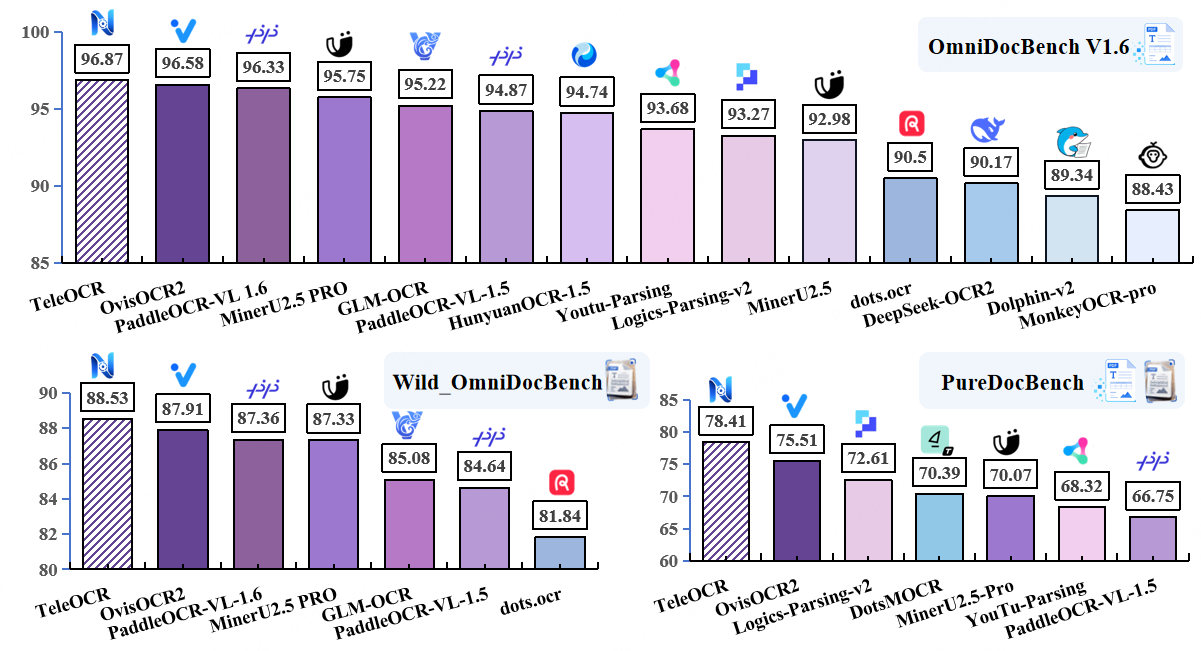
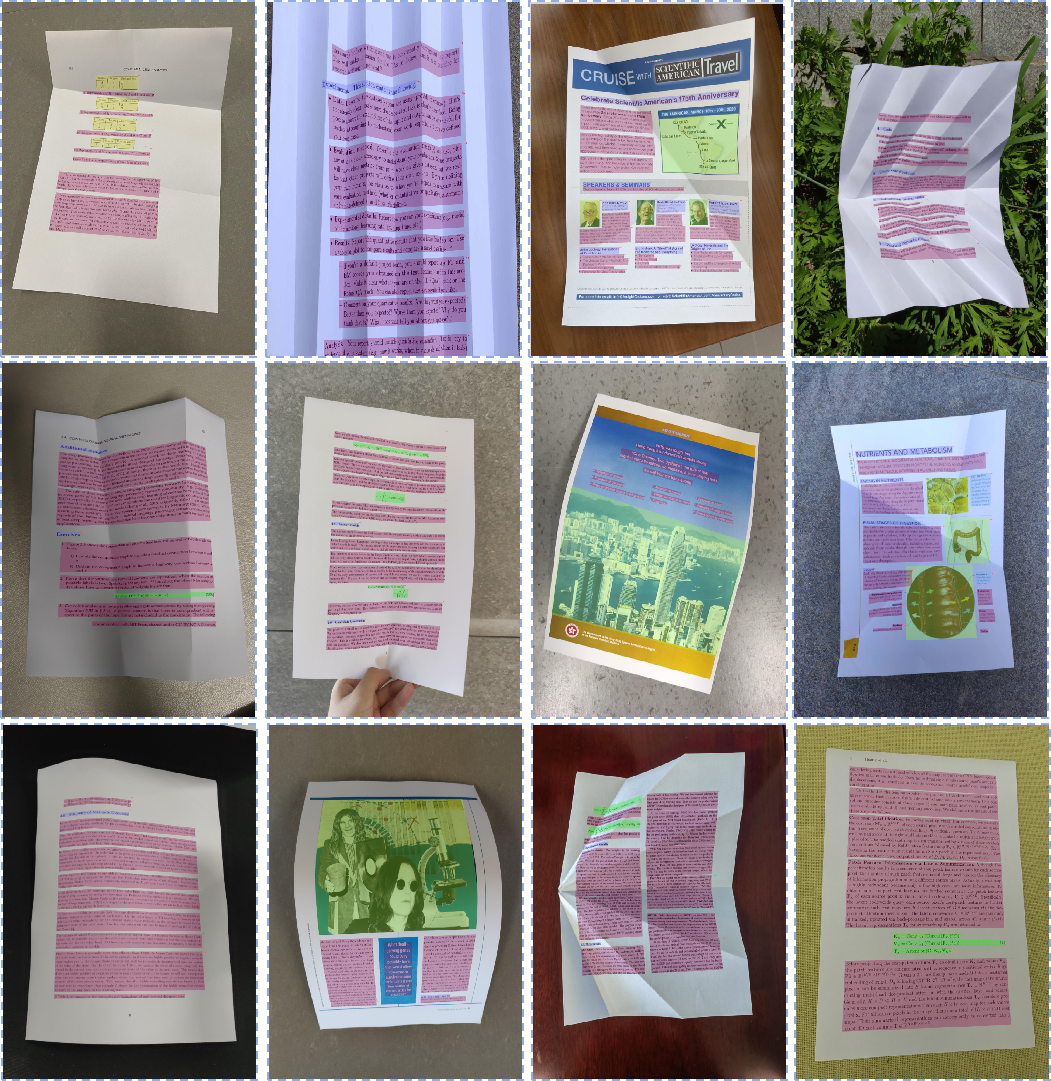
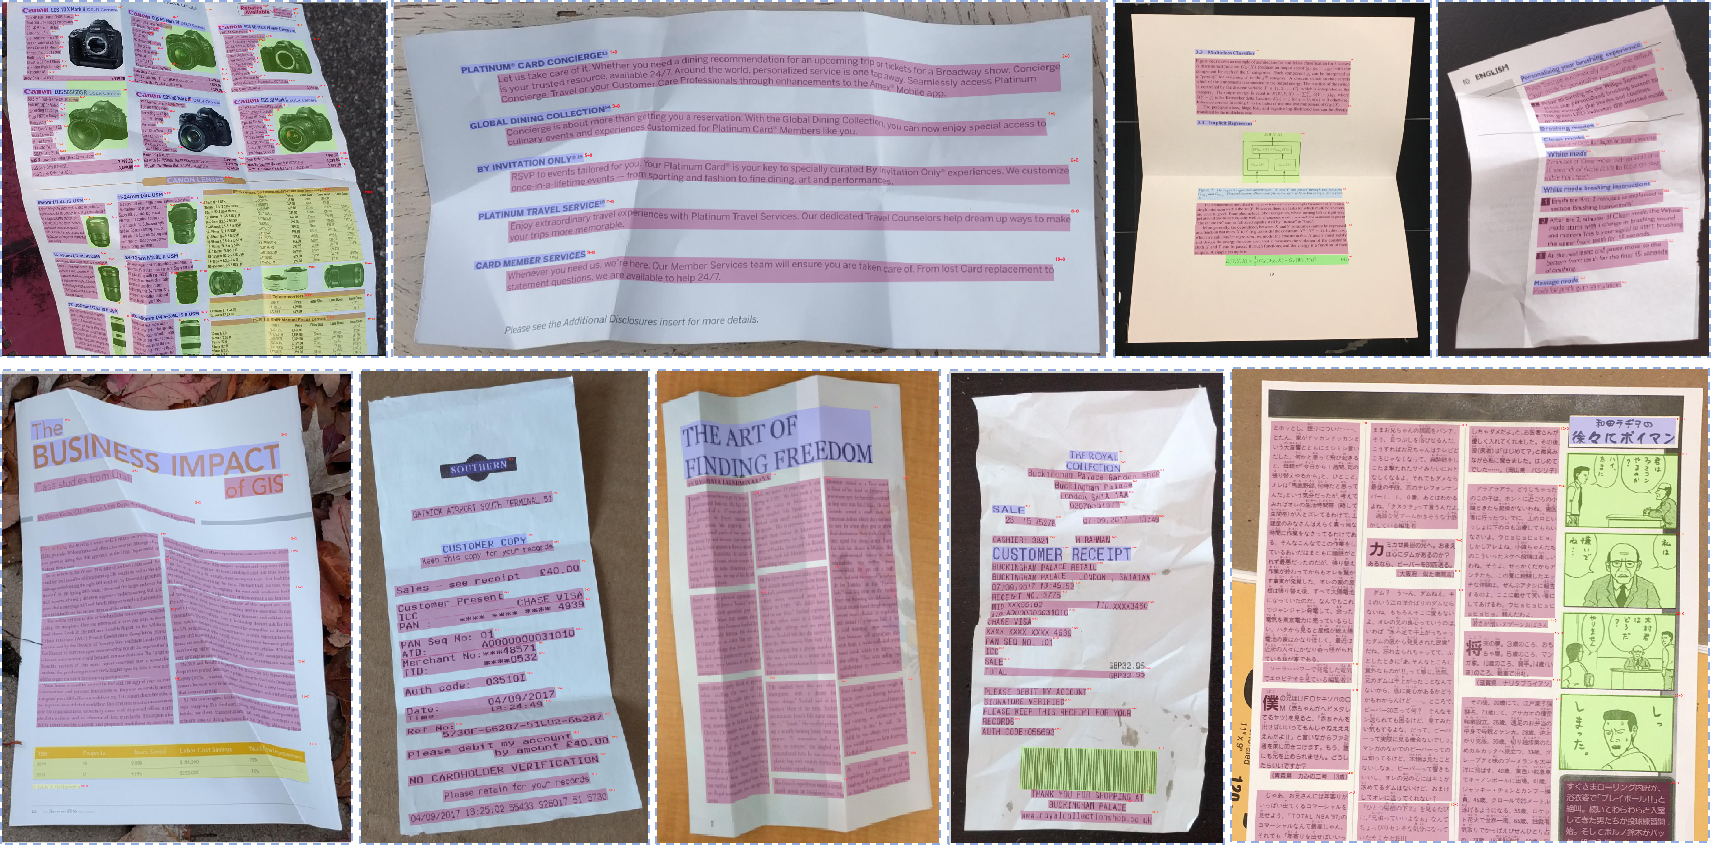
It scored 90.72 on the Real5-OmniDocBench evaluation, ranking 2nd among models with fewer than 500B parameters. Notably, it maintains high accuracy even with distorted scans, tilted documents, and various lighting conditions.
On ParseBench, it achieves performance in the 85s for text content recognition and the 80s for layout analysis. It handles multilingual documents, including Korean and English, and is freely available in the open-source ecosystem under the Apache 2.0 license.
XingChen-AGI/TeleOCR
The original page has no description.
image-text-to-text
This introduction was generated automatically by AI. Check the original for the author's claims and context. Copyright belongs to the original author.
Our guide explains how the AI works. Report errors, attribution issues, or removal requests via Contact.