 AI Briefing
Qwen3.8-27B-DFlash2: Draft model that boosts Qwen3.8-27B inference speed by 3.4x
incoai/Qwen3.8-27B-DFlash2
About the project
This is the DFlash 2 draft model designed to accelerate inference for Qwen3.8-27B. It is not a standalone language model; instead, it performs speculative decoding within inference servers such as SGLang or vLLM, pre-generating tokens for the target model to verify. It is released under the Apache-2.0 license and provided as a BF16 checkpoint with 2B parameters.
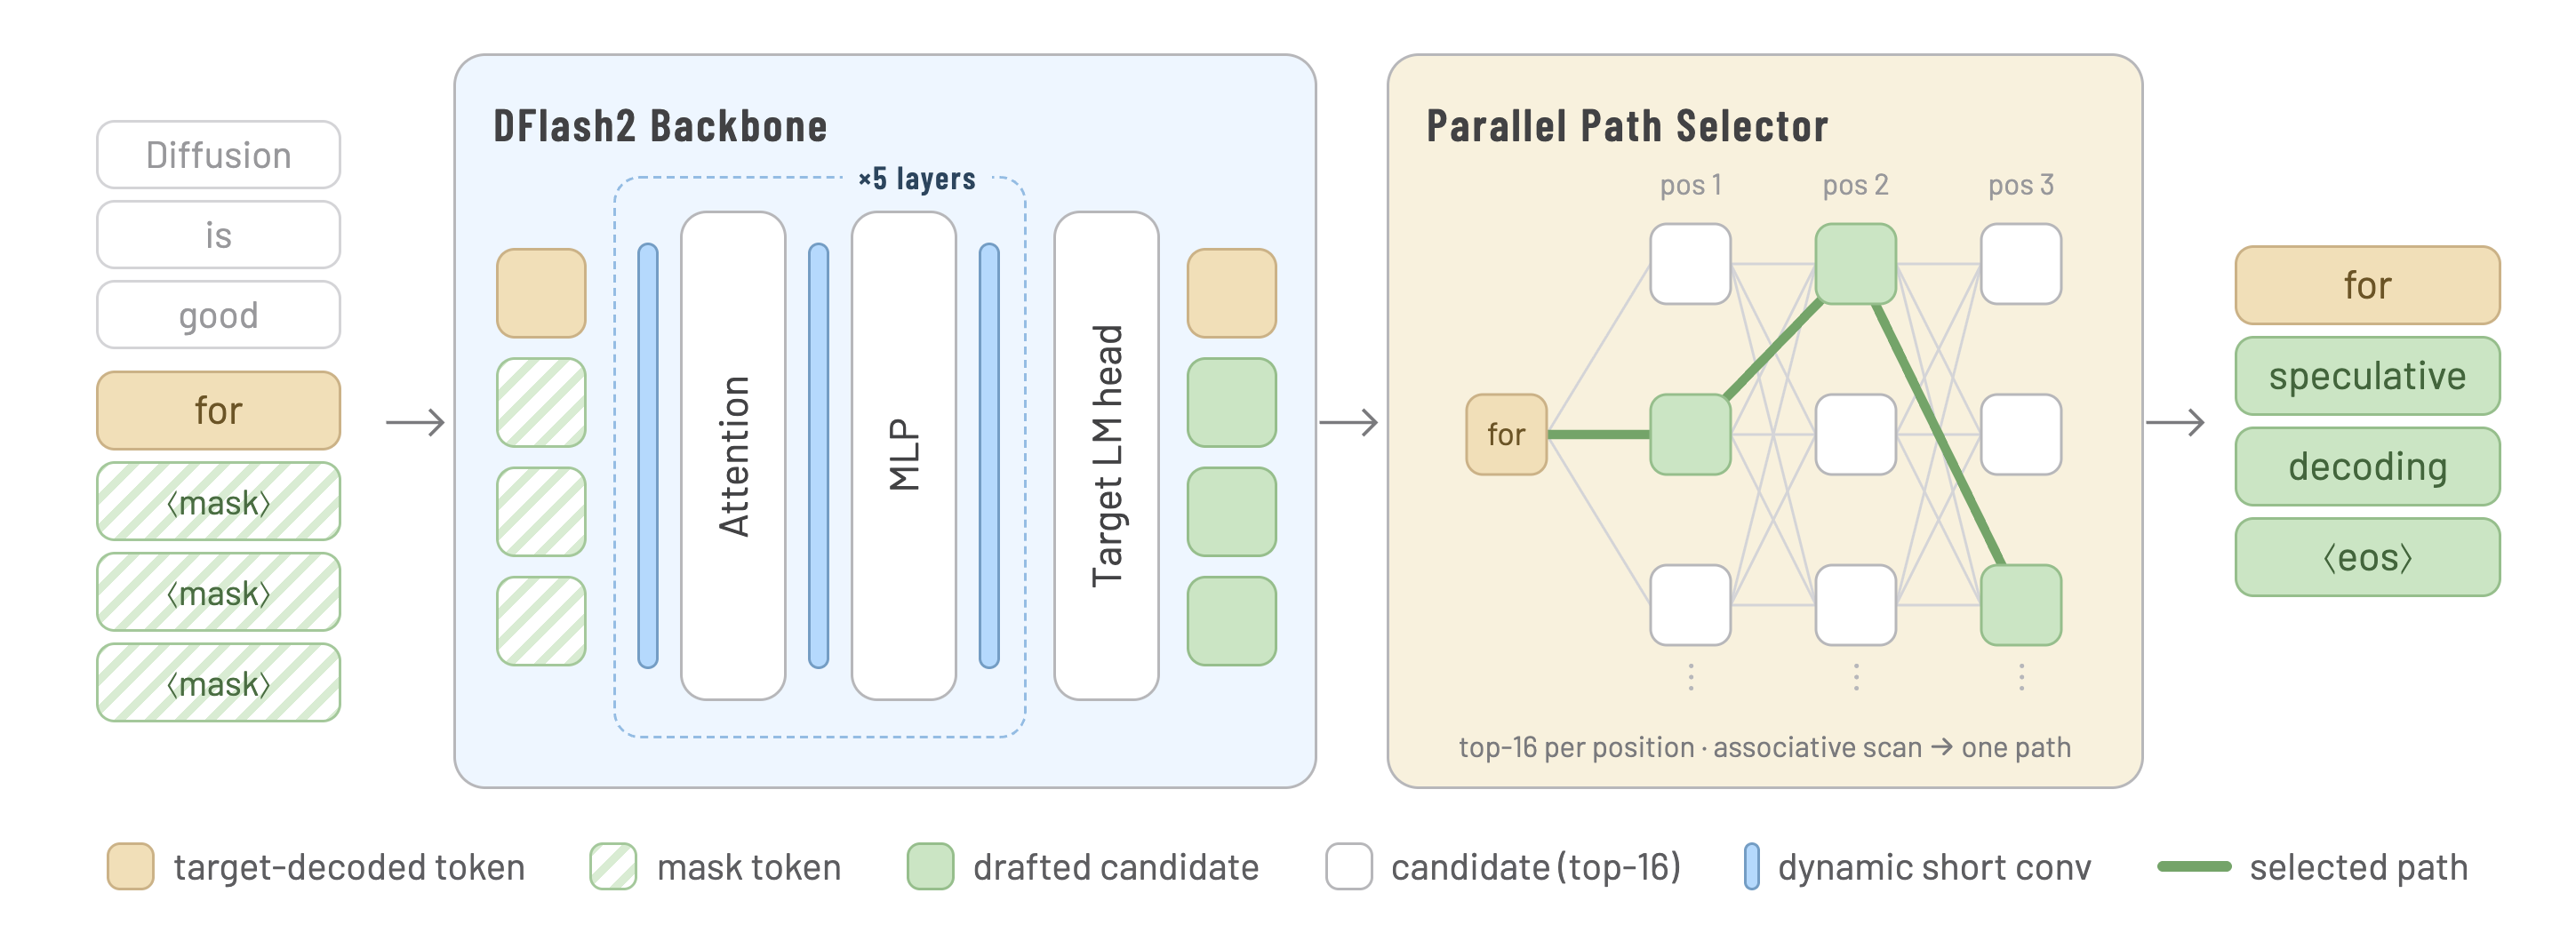
Unlike existing methods, it uses block-diffusion techniques to predict an entire block of tokens in a single pass. By applying two-tab dynamic synthesis to the backbone, it prevents the degradation of draft quality toward the end of the block. This process is lossless, ensuring that greedy outputs match the target model exactly and that the original distribution is preserved during sampling.
Benchmarks conducted on a single NVIDIA H200 GPU using SGLang show up to a 3.43x throughput improvement over autoregressive decoding. It achieves higher acceptance lengths than built-in MTP or other community draft models on major benchmarks such as GSM8K, MATH-500, and HumanEval. The speed advantage is most pronounced with a single concurrent request.
This model is suitable for developers looking to address response latency issues in large language models. It can be applied simply by specifying the draft model path in environments already serving Qwen3.8-27B, improving inference efficiency without requiring separate fine-tuning or complex configuration changes.
incoai/Qwen3.8-27B-DFlash2
The original page has no description.
text-generation
This introduction was generated automatically by AI. Check the original for the author's claims and context. Copyright belongs to the original author.
Our guide explains how the AI works. Report errors, attribution issues, or removal requests via Contact.