 AI Briefing
Nex-N2.5-mini: 35B Parameter MoE-based Multimodal LLM
nex-agi/Nex-N2.5-mini
About the project
This is a multimodal language model that accepts text and images as simultaneous inputs to generate responses. It adopts an MoE architecture based on Qwen3.5 to support efficient inference.
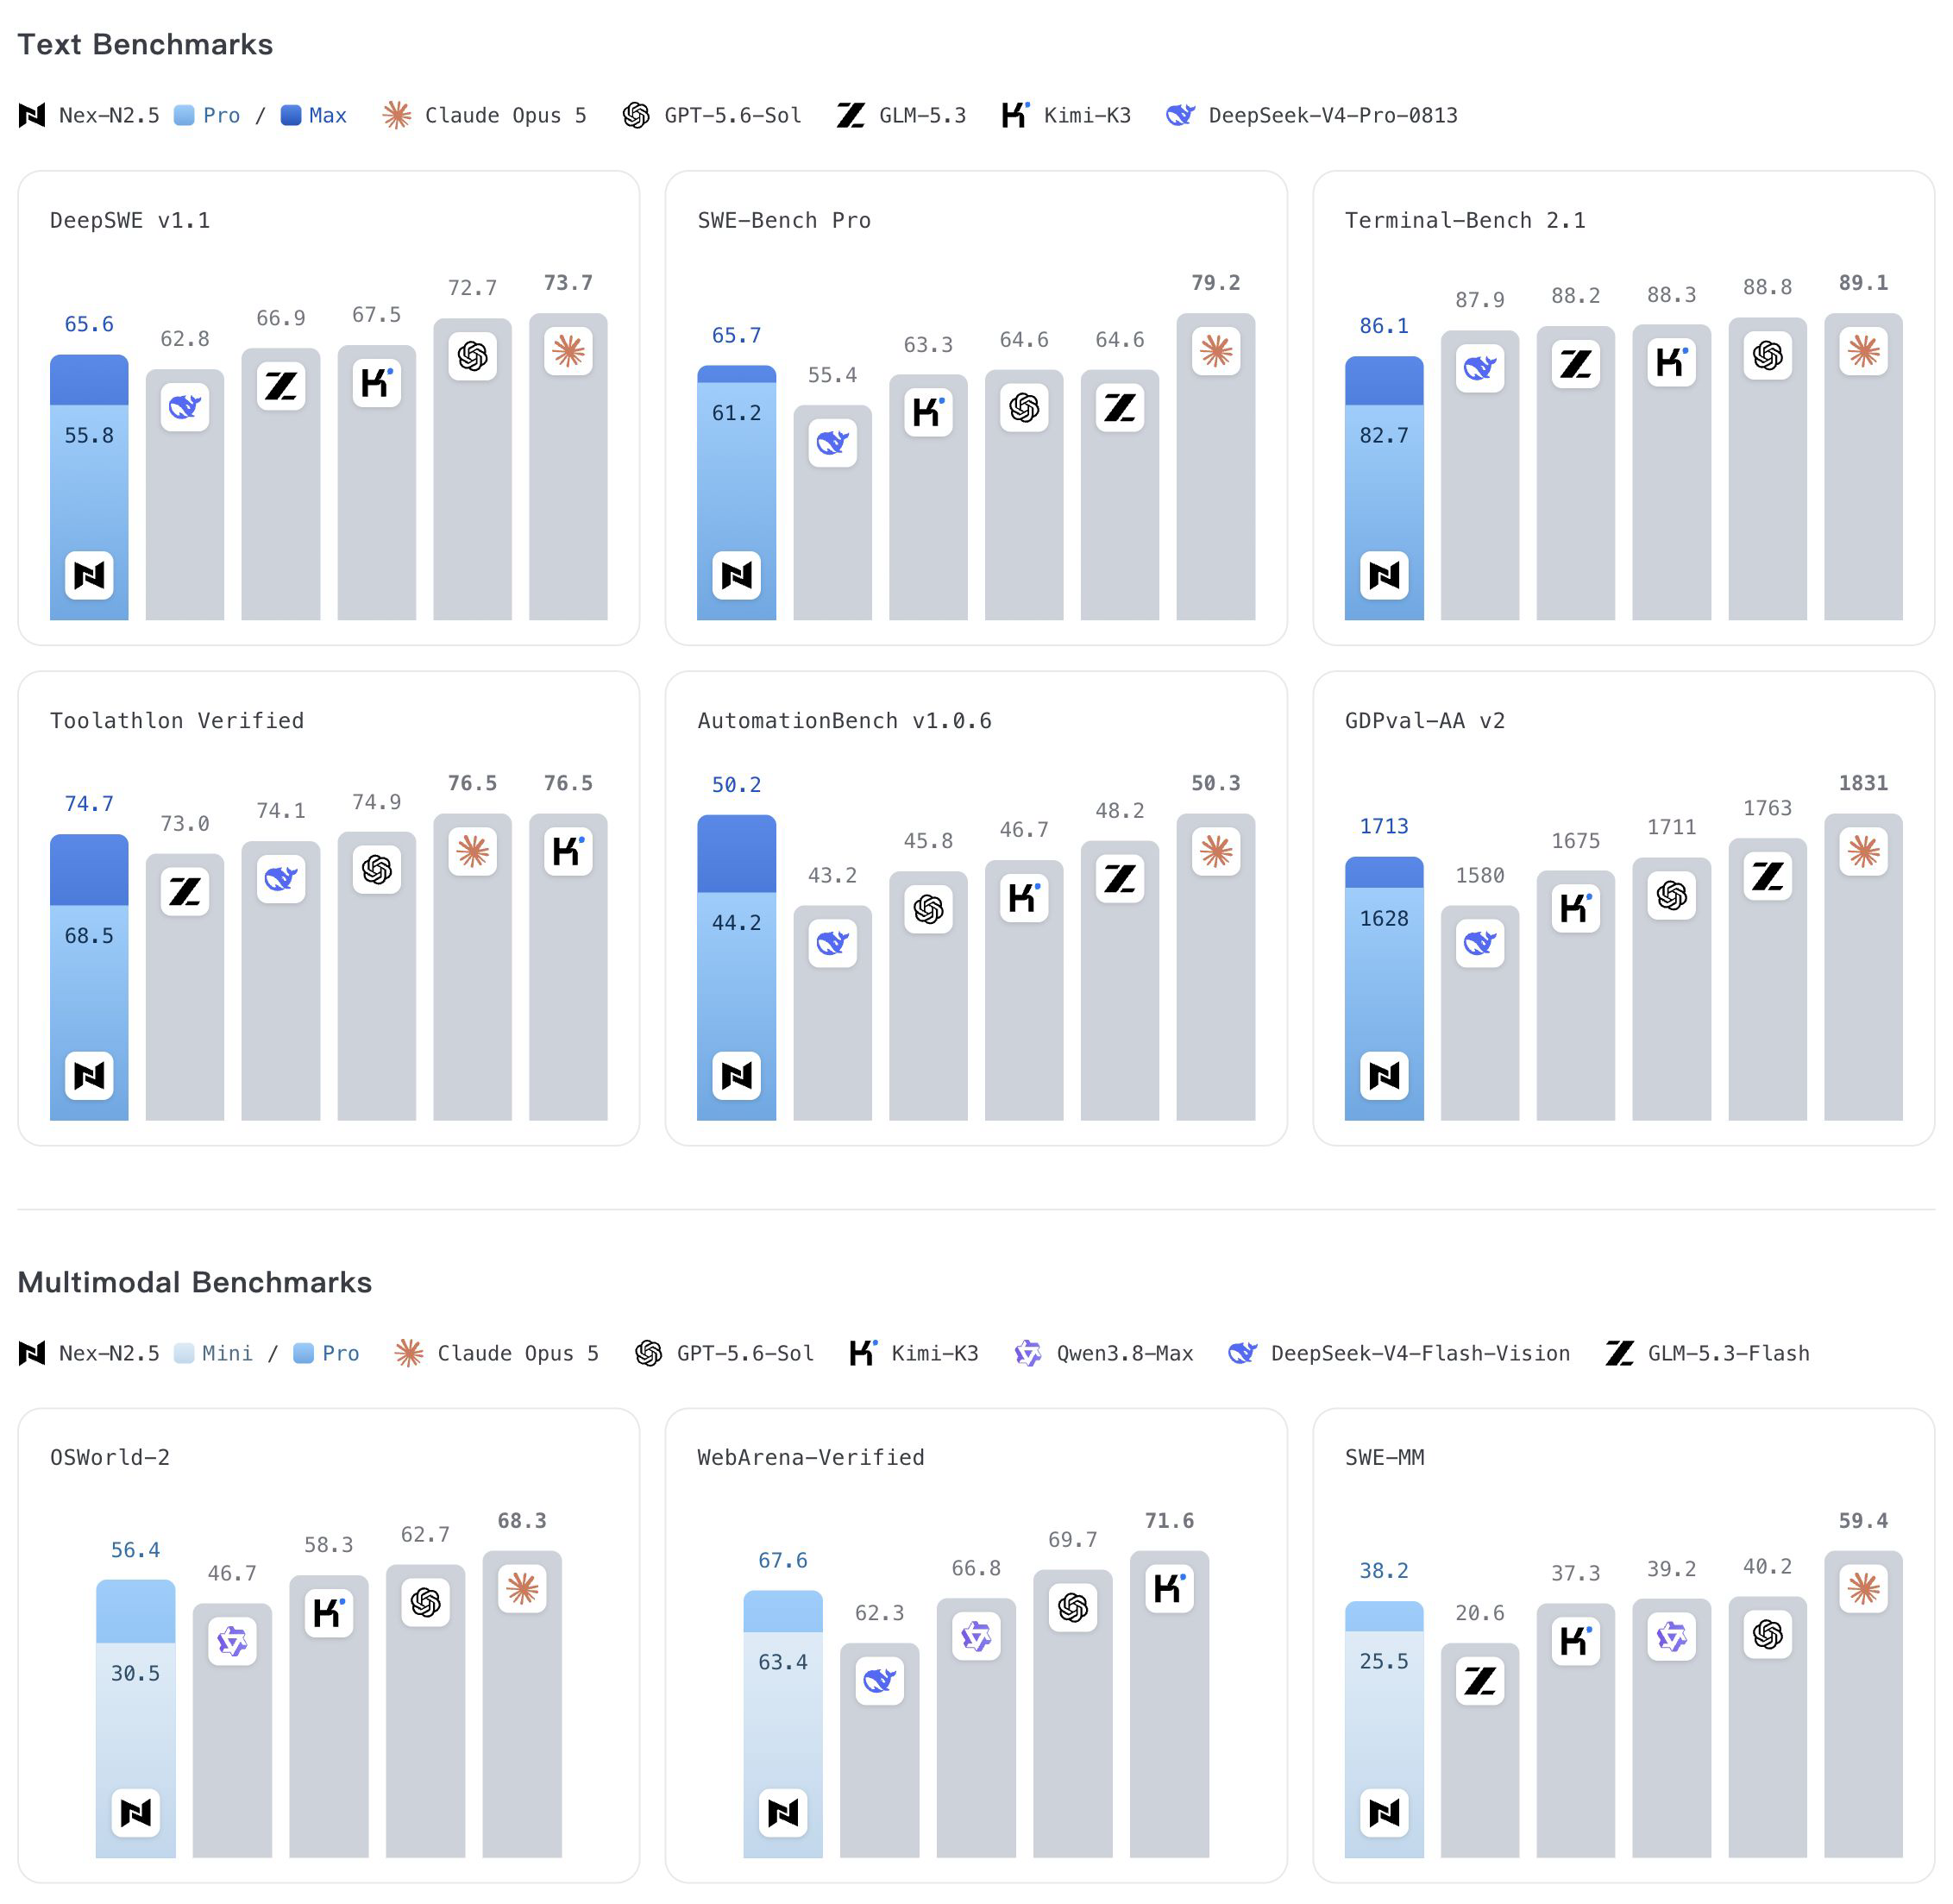
With a total scale of 35B parameters, it provides an image-text-to-text pipeline that processes images and text together. It maintains conversational context and can logically answer complex visual questions.
Distributed under the Apache 2.0 license, it allows for free commercial use. It is compatible with major inference engines such as vLLM and SGLang, and can be easily integrated via the OpenAI API format.
nex-agi/Nex-N2.5-mini
The original page has no description.
text-generation
This introduction was generated automatically by AI. Check the original for the author's claims and context. Copyright belongs to the original author.
Our guide explains how the AI works. Report errors, attribution issues, or removal requests via Contact.