 AI Briefing
SenseNova-U1.5-8B-MoT: 8B Unified Multimodal Model Handling Text and Images in a Single Architecture
sensenova/SenseNova-U1.5-8B-MoT
About the project
SenseNova-U1.5-8B-MoT is a native multimodal model that handles text understanding, image generation, and editing within a single architecture. Based on NEO-unify, this checkpoint enhances visual consistency and aesthetic quality by strengthening the patchify layer, data quality, and post-training pipeline. It is released under the Apache 2.0 license and supports English and Chinese.
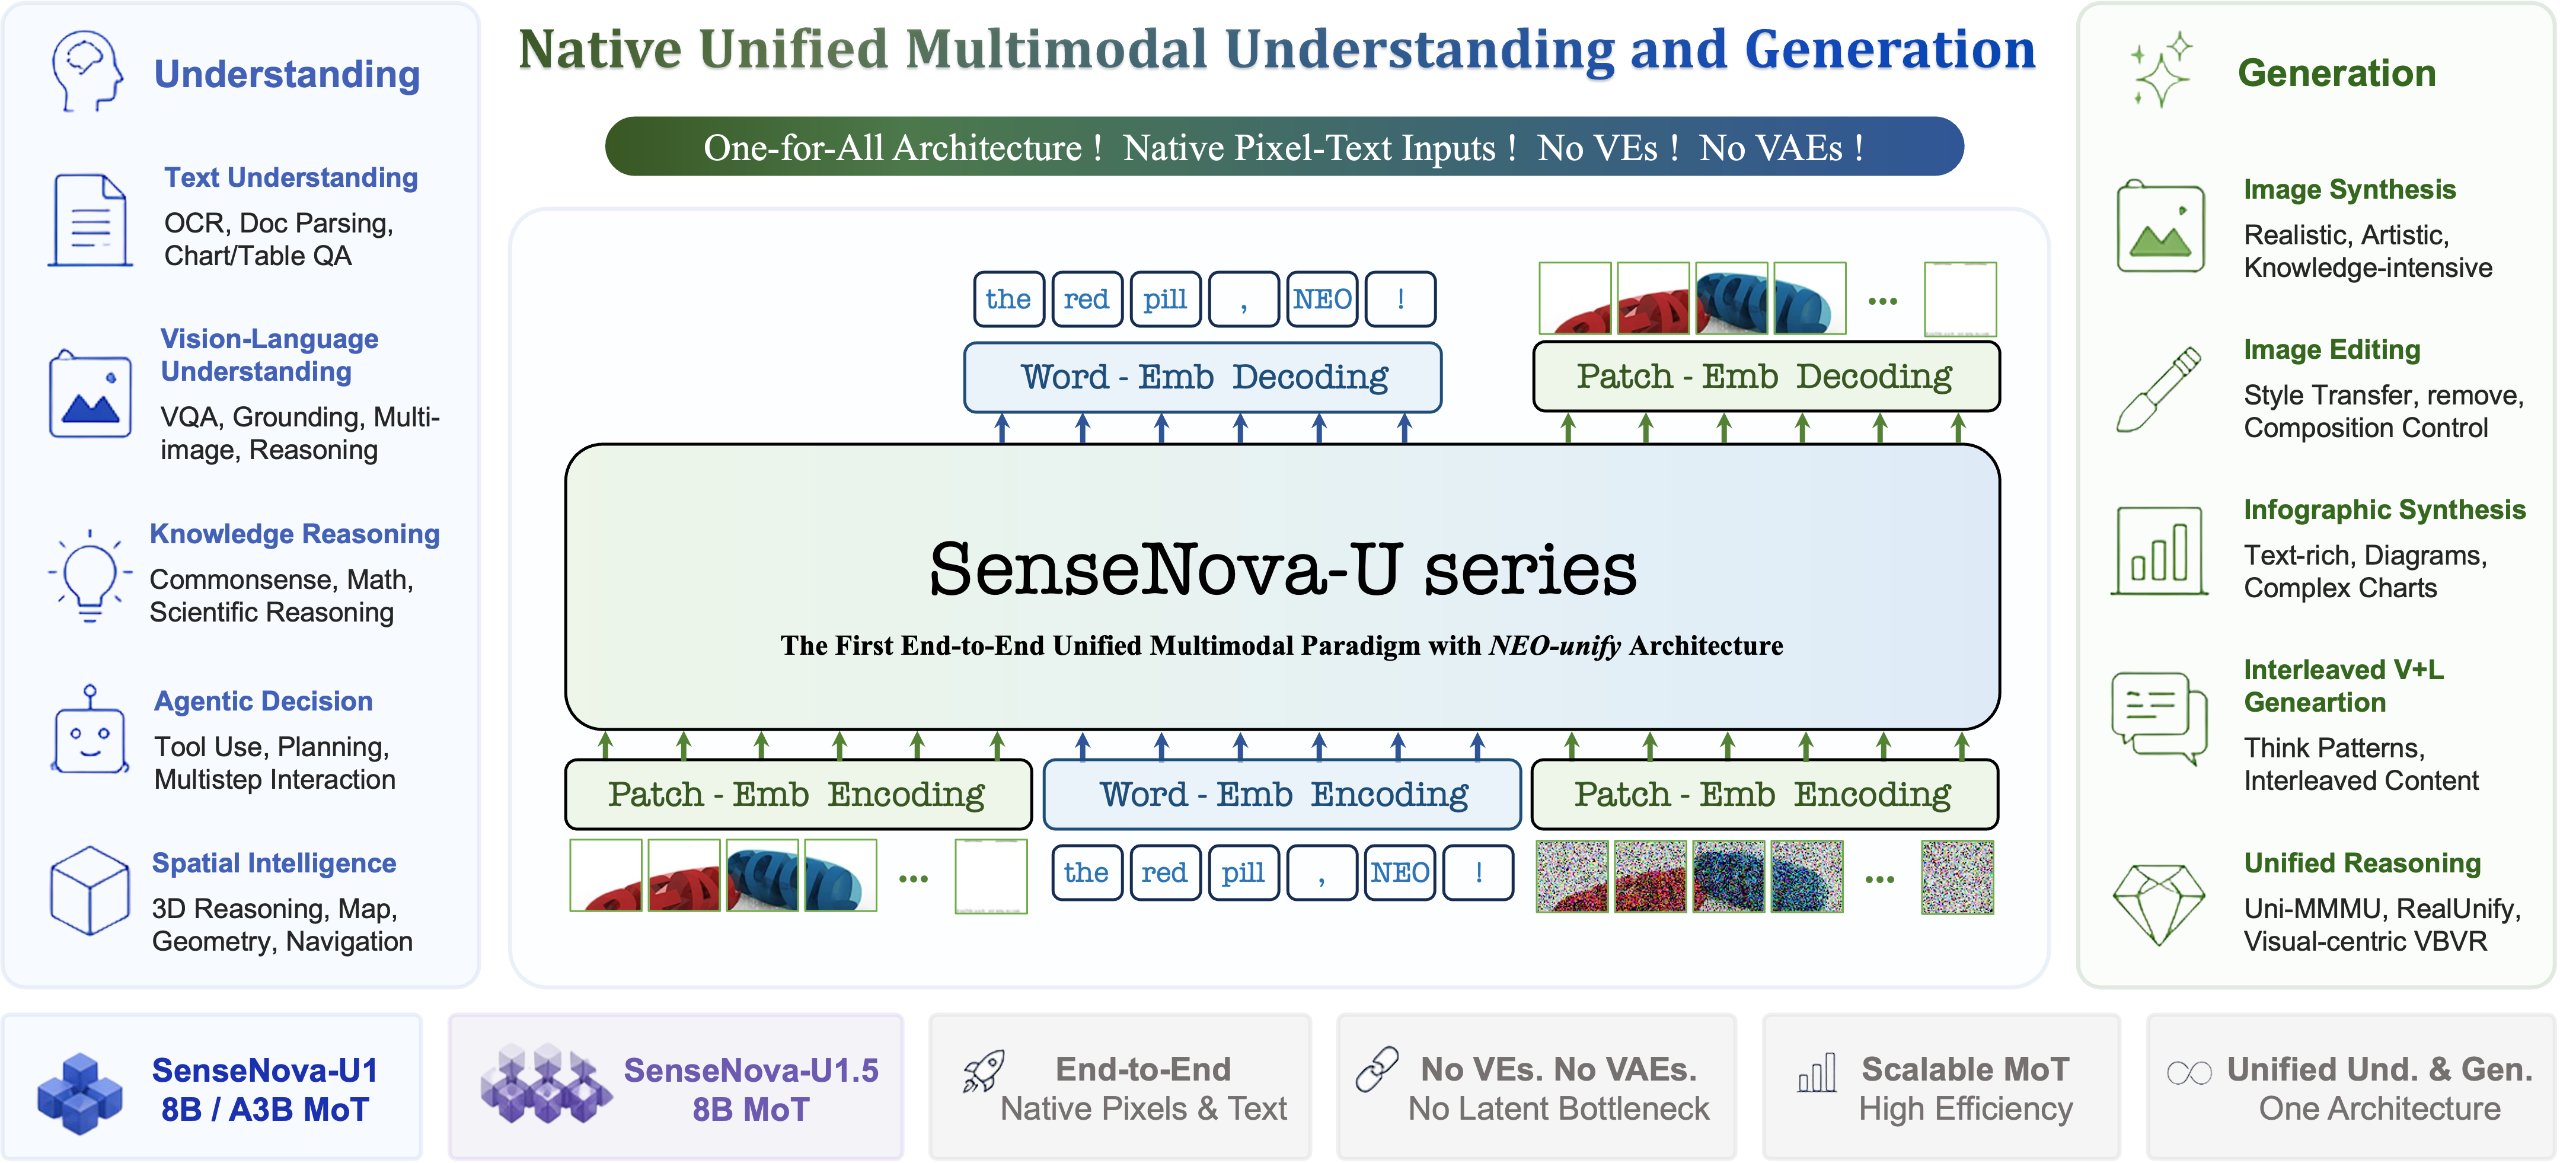
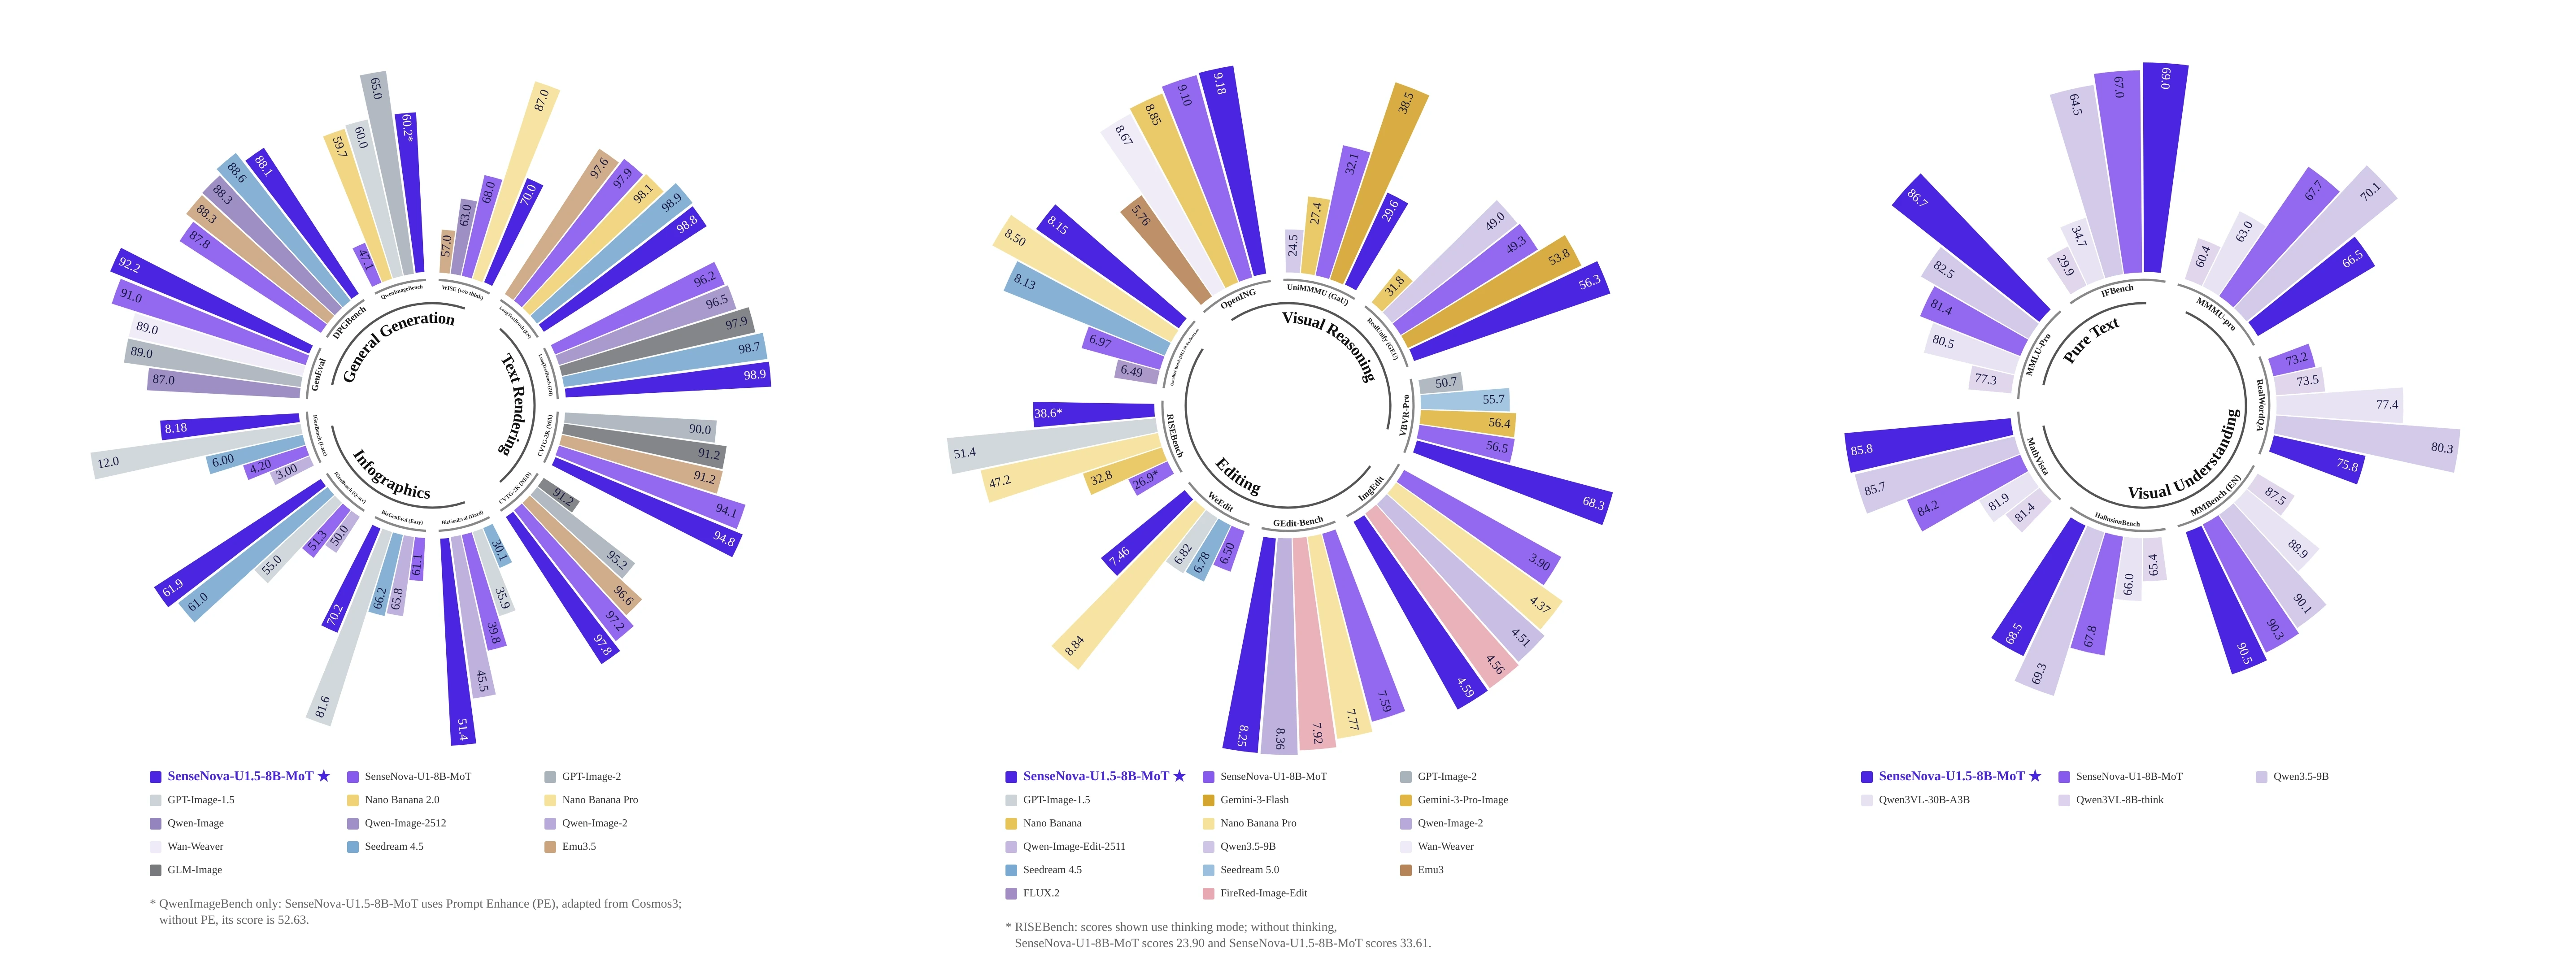
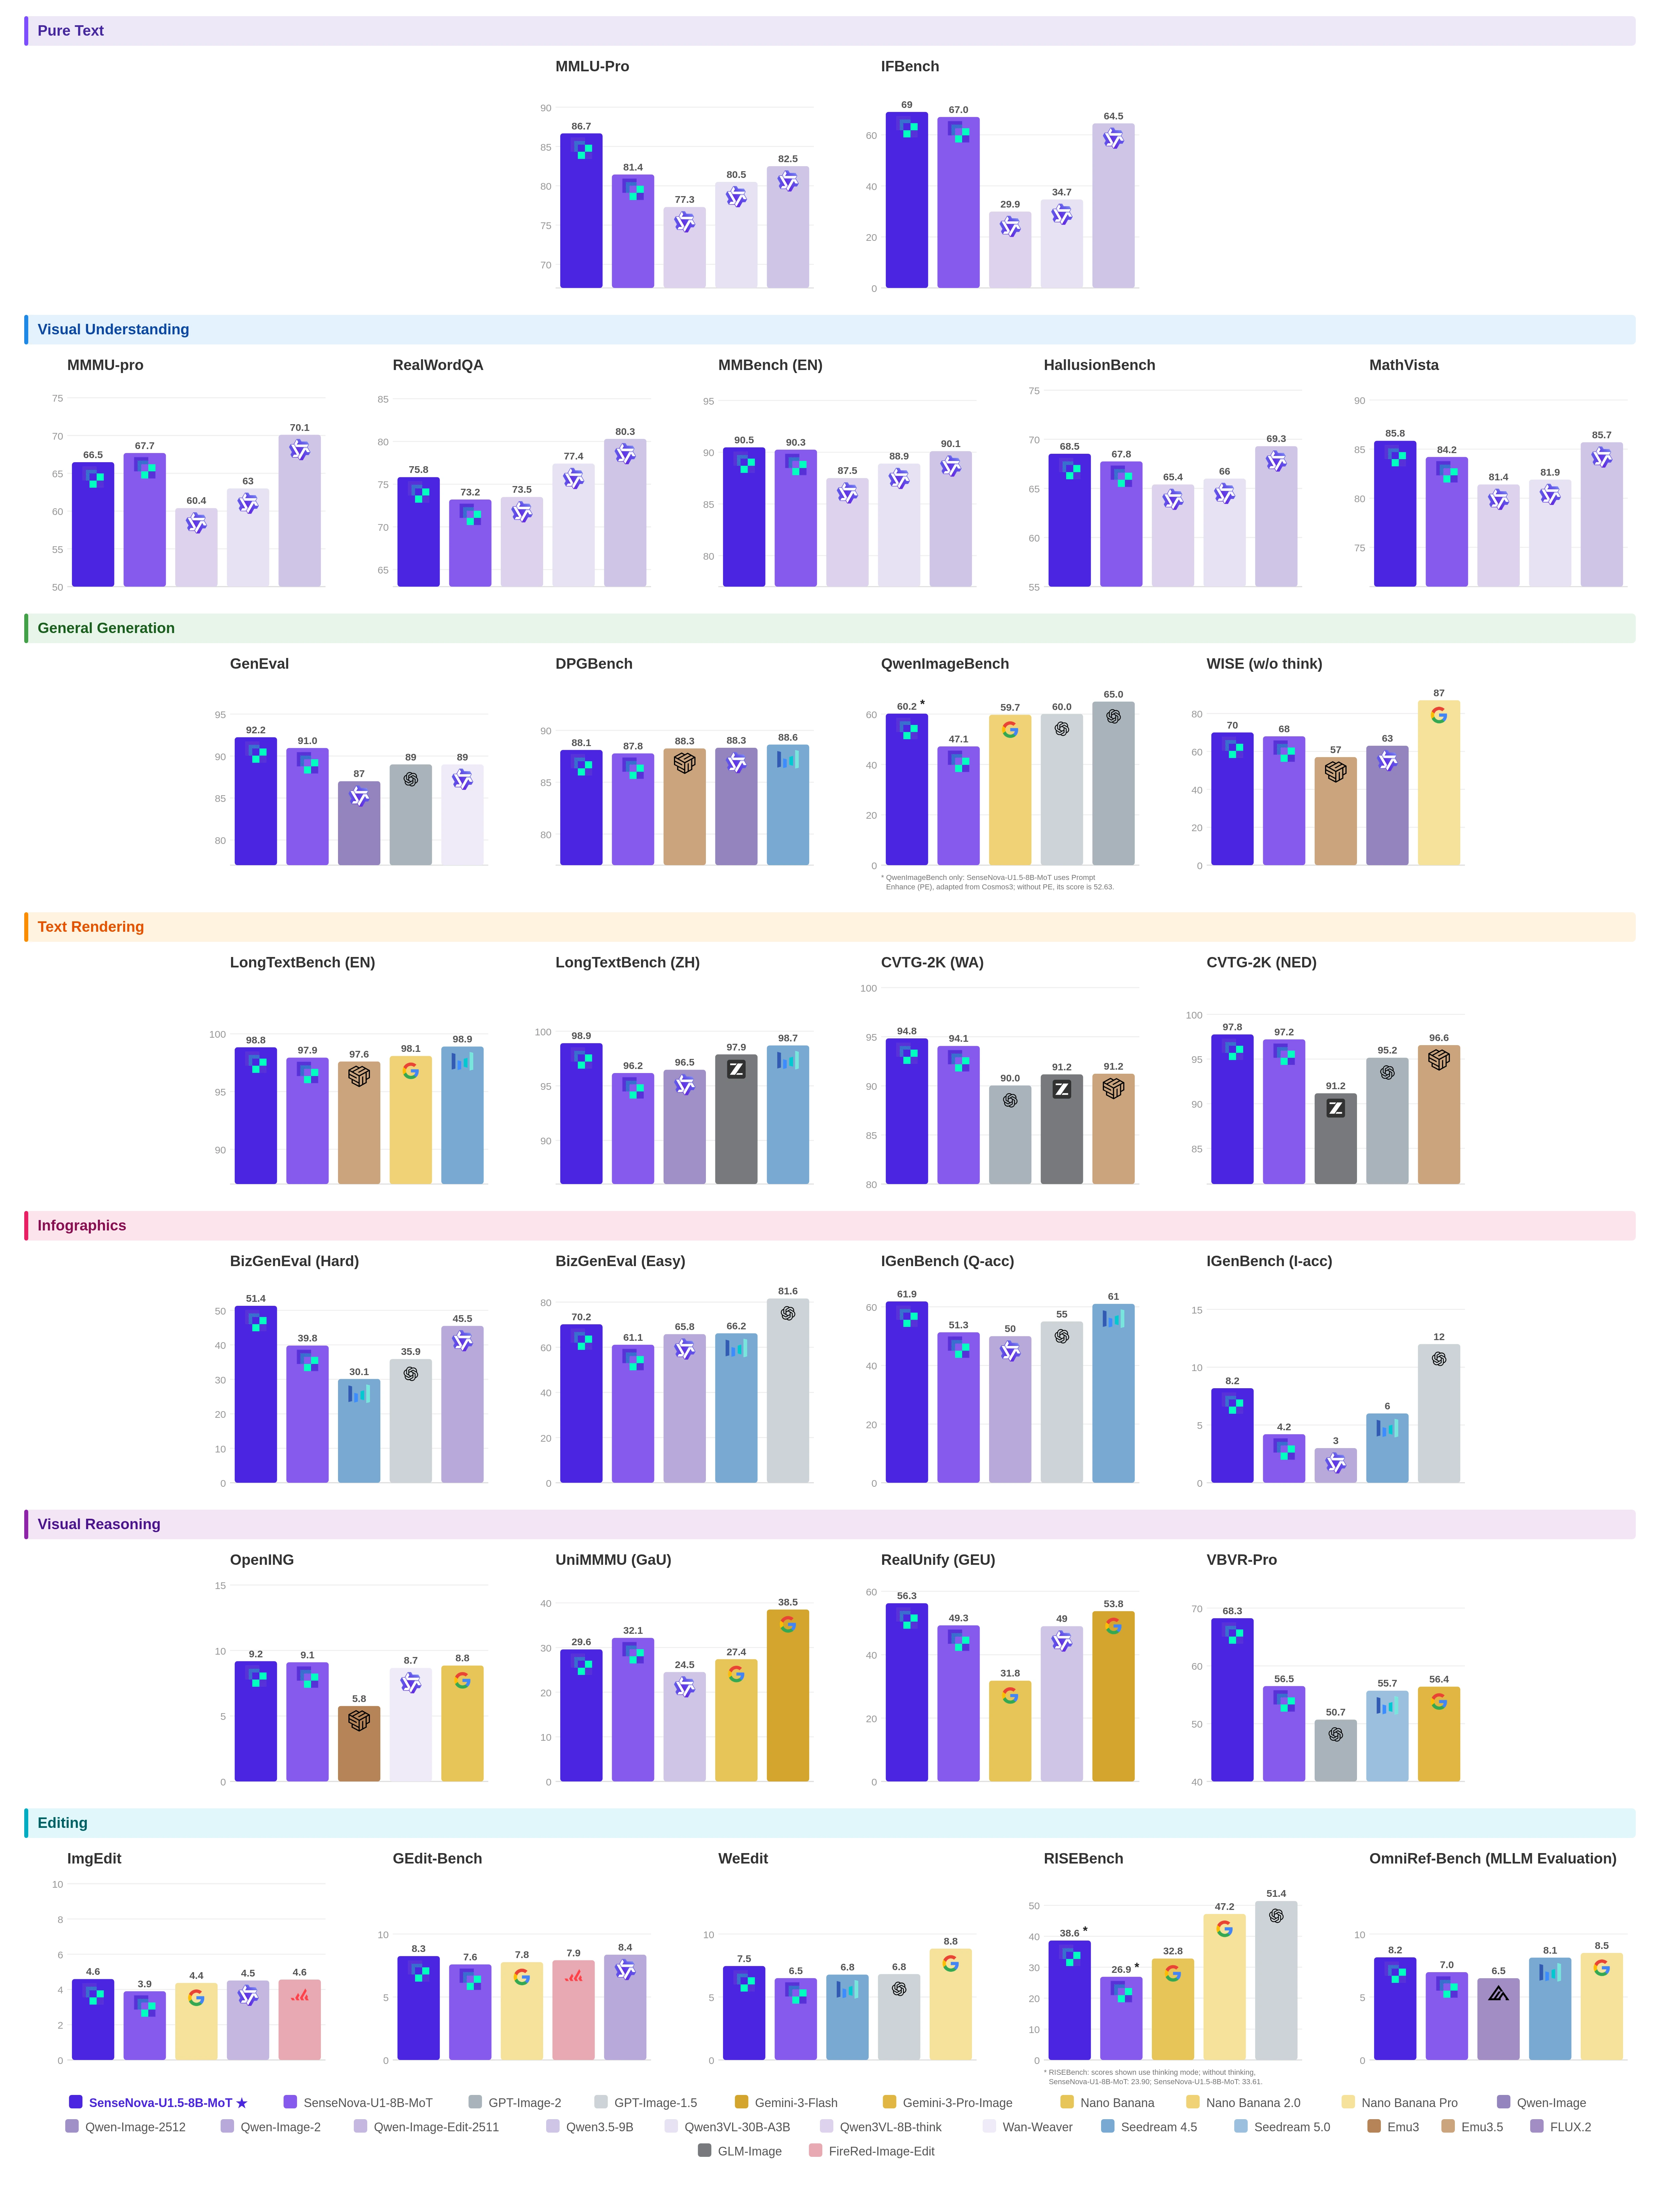
Given a text prompt, it natively generates images at 4K resolution while adhering to object placement and style control based on complex instructions. When provided with an image, it enables precise editing, such as modifying specific regions or replacing text. Control scope can be specified at the target level using bounding boxes or visual markers.
Unlike previous approaches, readability for English and Chinese has improved in text rendering and infographic generation, making it suitable for creating posters and brand assets. During image editing, it preserves subject identity, background, lighting, and composition in unedited areas. The ability to simultaneously handle multiple constraints—such as object count, spatial relationships, and layout—within a single request has been enhanced.
SenseNova-Studio is provided for immediate browser-based experience without a GPU, facilitating initial testing. However, limitations remain in high-density text, complex layouts, and detailed human anatomy, potentially requiring cfg_scale adjustments or prompt enhancement. It is suitable for developers building workflows that integrate visual generation and editing.
sensenova/SenseNova-U1.5-8B-MoT
The original page has no description.
any-to-any
This introduction was generated automatically by AI. Check the original for the author's claims and context. Copyright belongs to the original author.
Our guide explains how the AI works. Report errors, attribution issues, or removal requests via Contact.