 AI Briefing
AuK: Voice generation, editing, and separation with a single natural language instruction
tencent/AuK
About the project
A voice generation and editing foundation model based on 1.5B parameters, released by Tencent. Trained on millions of hours of audio data, it performs various voice tasks with a single natural language instruction, without requiring complex configurations.
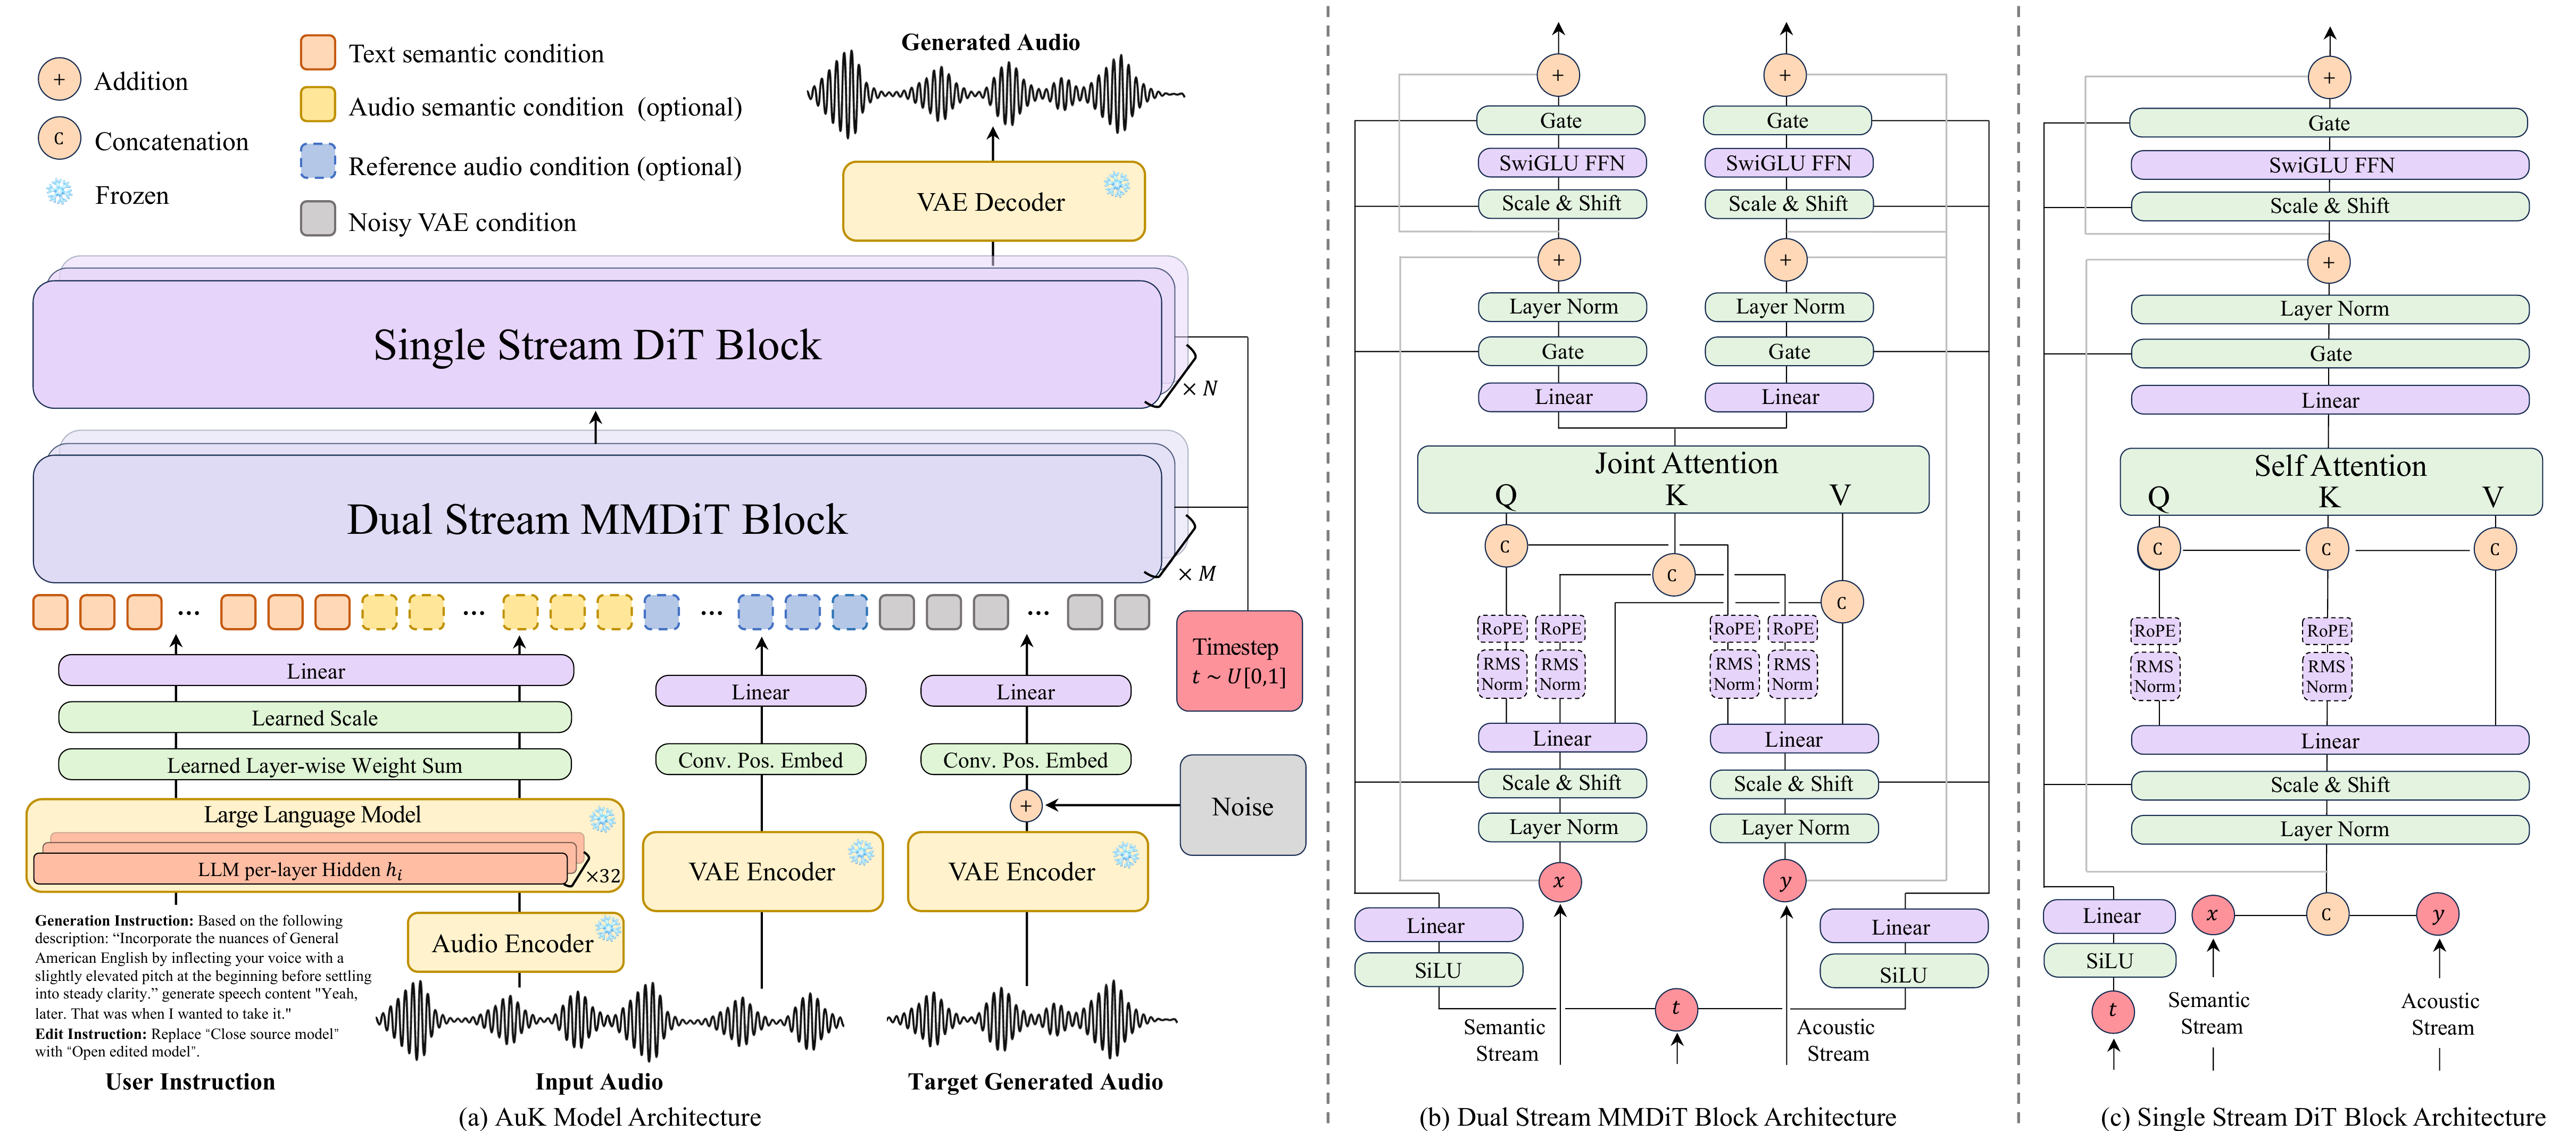
It supports everything from Zero-shot TTS based on reference audio to Instruct TTS, which generates speech solely from voice descriptions. Fine-grained editing is possible, including modifying the emotion, intonation, speed, and volume of already generated speech, or removing non-verbal sounds.
Audio processing features such as voice enhancement, speaker separation, and vocal extraction from music are also integrated. The base model and the AuK-Flash variant, which speeds up inference with 4-step reasoning, are provided under the MIT license with no restrictions on commercial use.
tencent/AuK
The original page has no description.
text-to-speech
This introduction was generated automatically by AI. Check the original for the author's claims and context. Copyright belongs to the original author.
Our guide explains how the AI works. Report errors, attribution issues, or removal requests via Contact.