 AI Briefing
PickQwen3.8-Flash-Next-GGUF: Running Qwen3.8-Flash-Next Locally with 72GB GGUF
unsloth/Qwen3.8-Flash-Next-GGUF
About the project
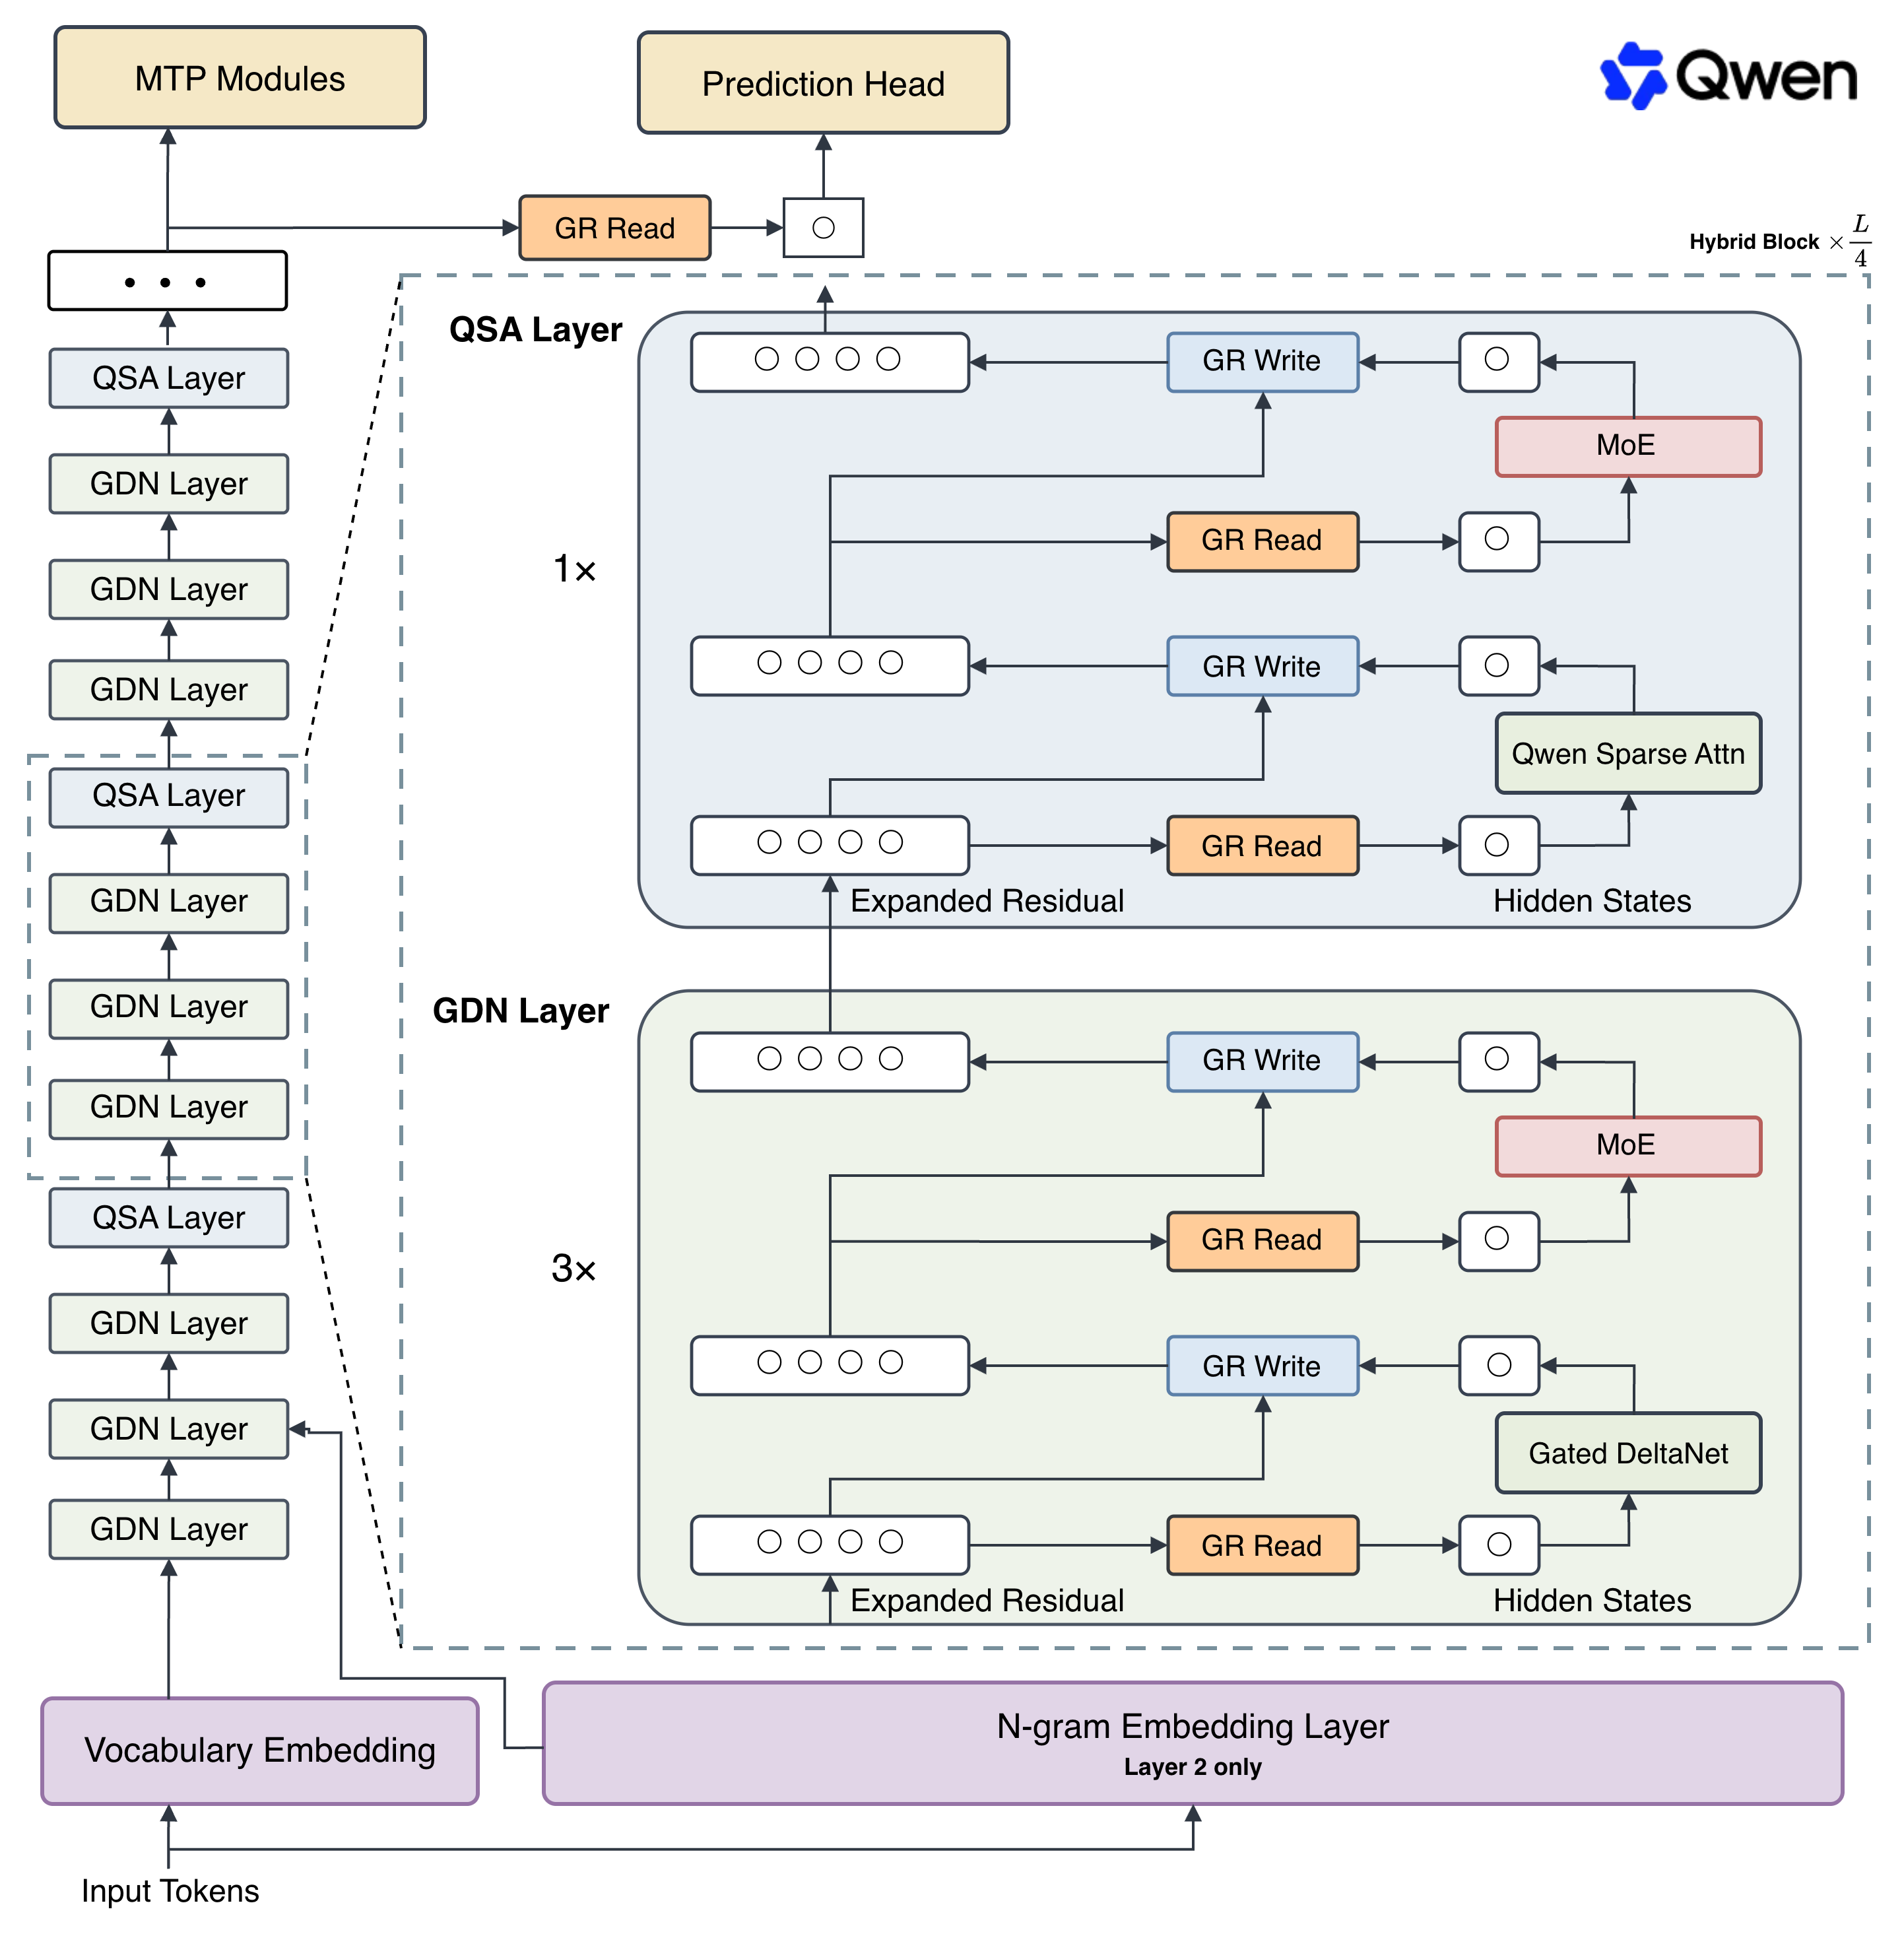
Unsloth has released the Qwen3.8-Flash-Next model in GGUF format. It is a multimodal LLM that understands both images and text, designed for inference in local environments. The total size is approximately 72GB, and it is provided in the UD-IQ1_S quantized version.
It is compatible with major local inference frameworks such as llama.cpp, vLLM, and LM Studio. You can launch an OpenAI-compatible API server or run it directly as a client in the terminal, making it suitable for developers who want to run models on their own infrastructure without cloud dependencies. Integration with the Transformers library is also supported.
The chat template includes logic for handling tool calling and reasoning instructions. By handling system message merging, developer role support, and multi-step tool calling structures at the template level, it reduces the burden of prompt engineering when developing agent-based applications.
Released under the Qwen Community License, it requires checking the terms before commercial use. Due to its substantial size of 72GB, a high-spec GPU environment is required. It is useful for experimenting with large-scale multimodal models locally or performing inference tasks that require privacy protection.
unsloth/Qwen3.8-Flash-Next-GGUF
The original page has no description.
image-text-to-text
This introduction was generated automatically by AI. Check the original for the author's claims and context. Copyright belongs to the original author.
Our guide explains how the AI works. Report errors, attribution issues, or removal requests via Contact.