 AI Briefing
PickGLM-5.3-Flash: GLM-5.3-Flash: 84.3 on Terminal-Bench at 36 TPS
zai-org/GLM-5.3-Flash
About the project
GLM-5.3-Flash, released by zai-org, is an LLM that supports text generation and tool calling. It offers live inference on Hugging Face with a processing speed of 36.12 tokens per second. The model size is classified as under 500B.
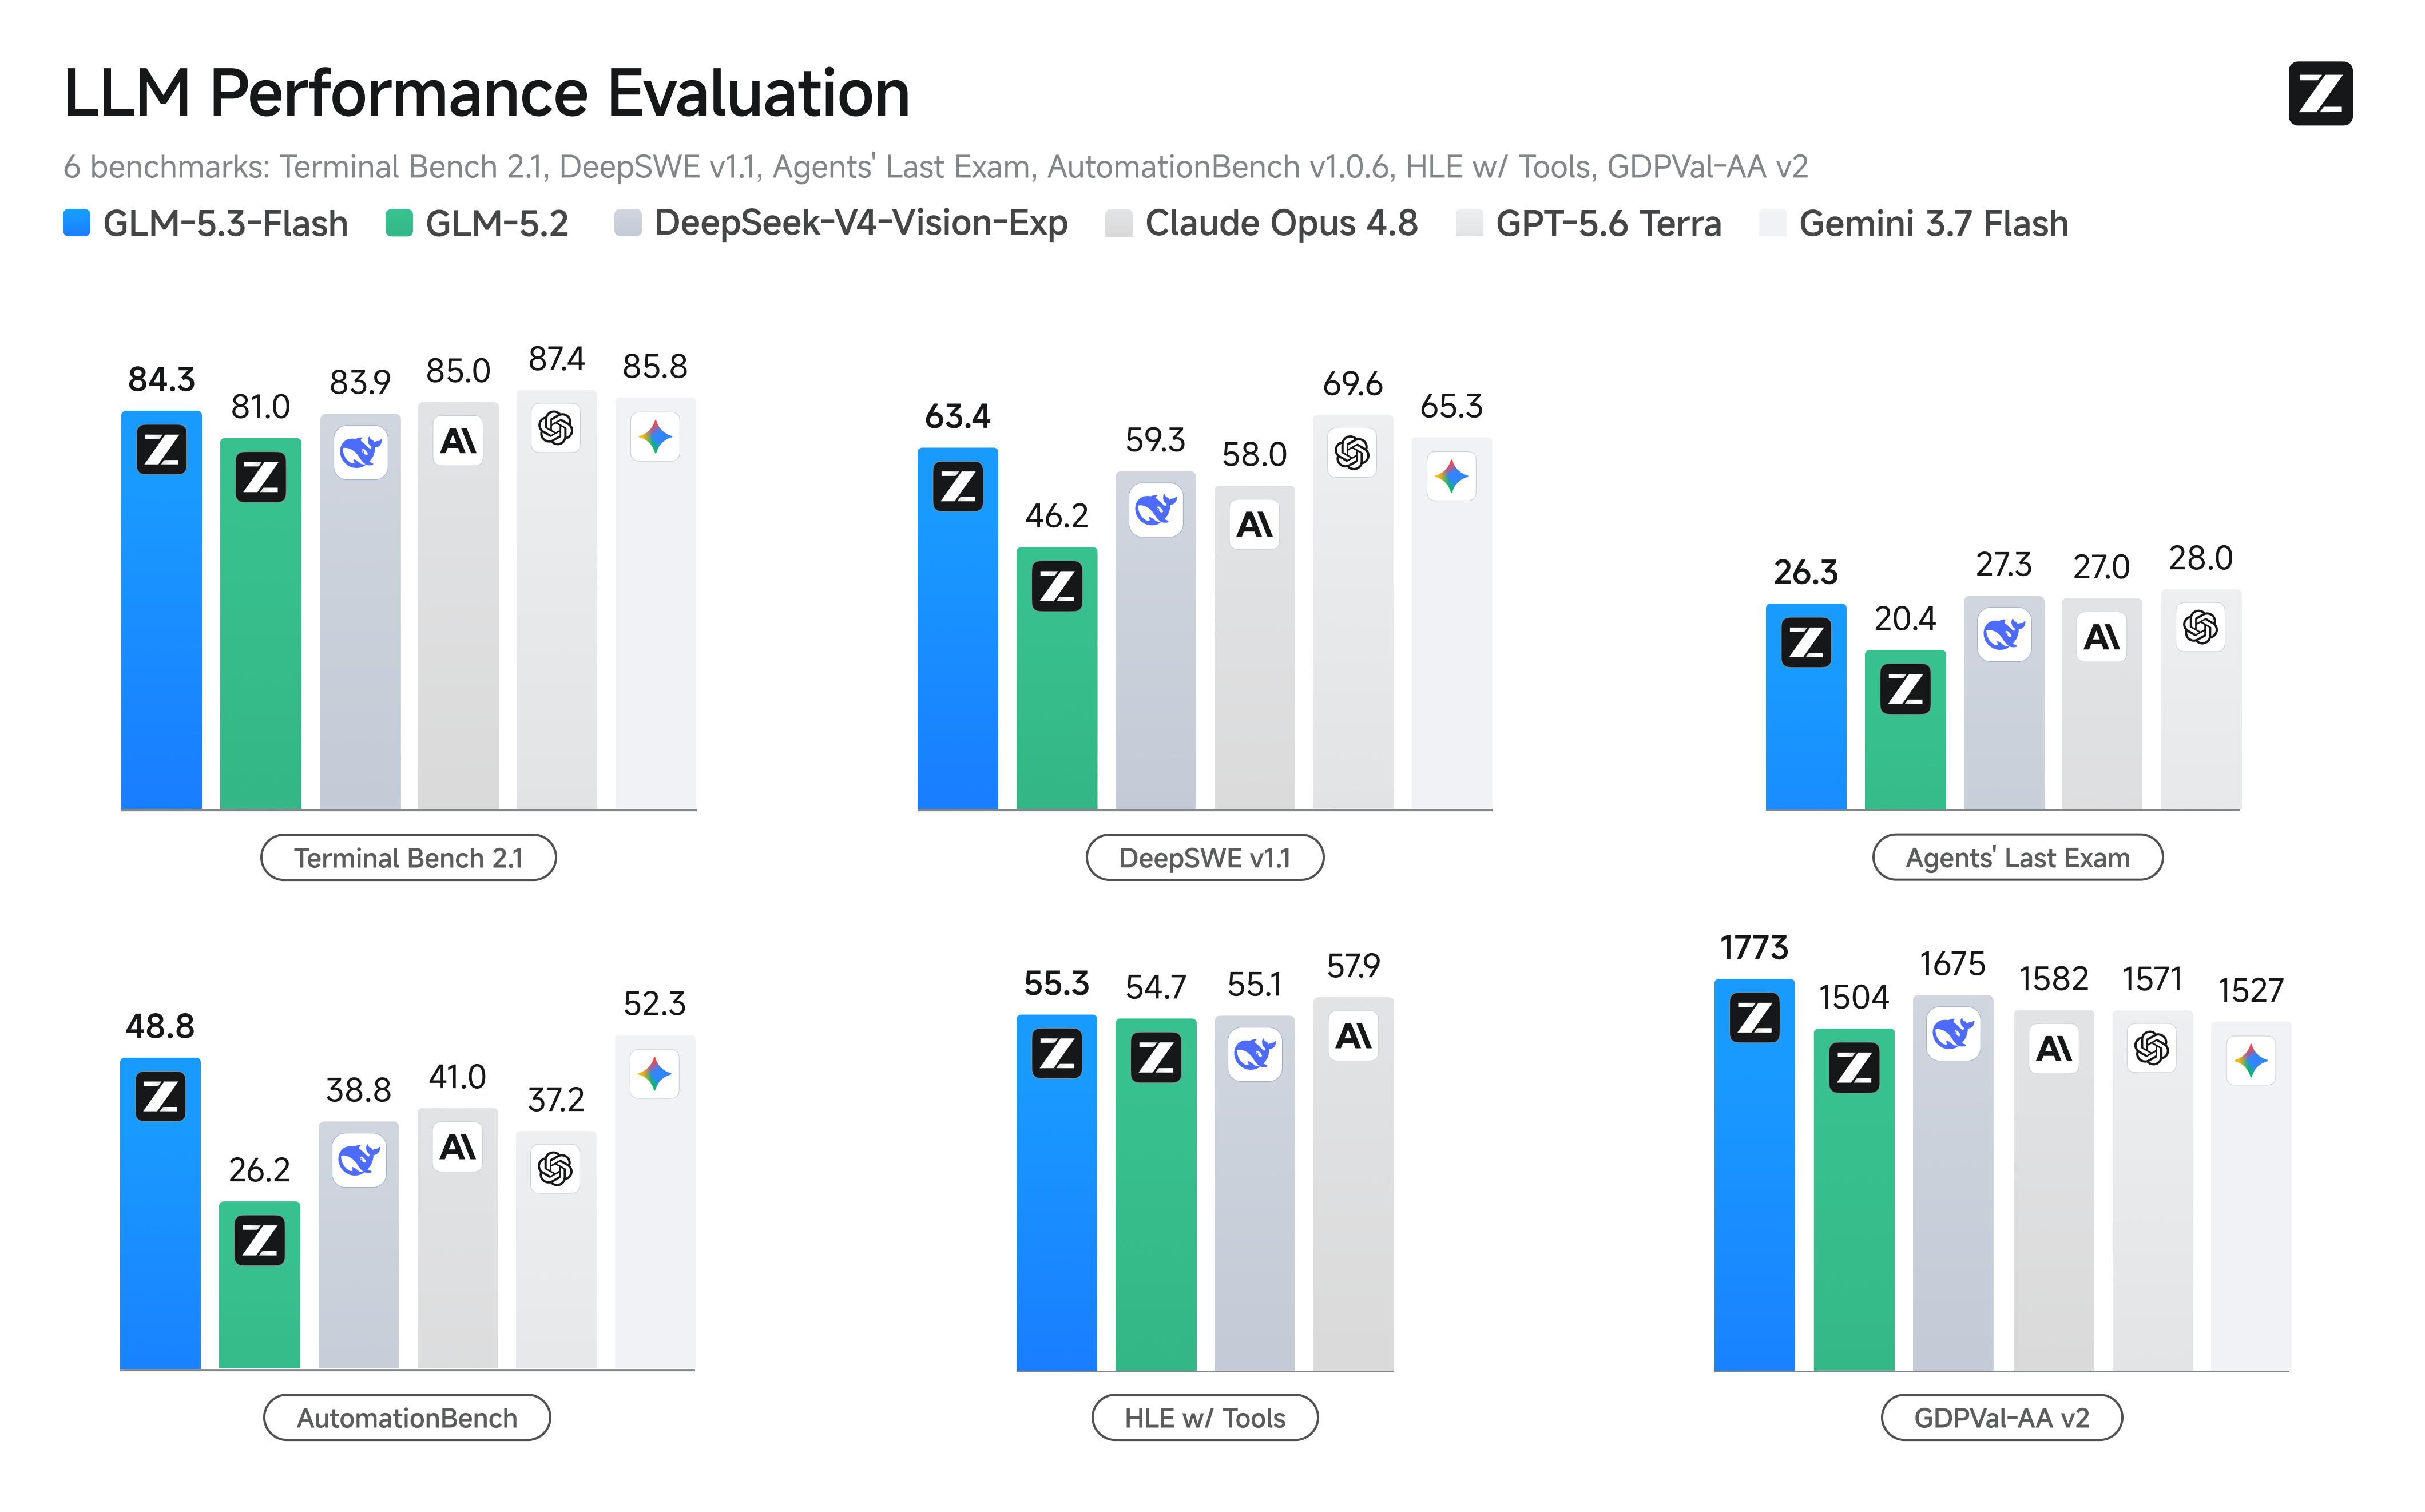
It excels in coding and terminal task execution. It scored 84.3 on the Terminal-Bench 2.1 benchmark and achieved 63.4 on DeepSWE. Notably, the DeepSWE evaluation was conducted using the mini-swe-agent harness in a 400K context environment.
It delivers stable performance on tasks combining complex reasoning and tool use. It recorded 55.3 on the HLE (Hard Logic Evaluation) benchmark, which was conducted with a 300K context management strategy and the full tool set applied.
It uses a Transformer-based architecture and structures system prompts, tool definitions, and user inputs via Jinja templates. For tool calls, it adopts a method of passing function names and arguments using XML-formatted tags.
zai-org/GLM-5.3-Flash
The original page has no description.
image-text-to-text
This introduction was generated automatically by AI. Check the original for the author's claims and context. Copyright belongs to the original author.
Our guide explains how the AI works. Report errors, attribution issues, or removal requests via Contact.